Skip to content

In conversations with three Chief Medical Information Officers across different healthcare systems, each was asked about their most recent cybersecurity incident. The answer was unanimous and telling: None had experienced a direct attack on their own systems. Instead, all three were grappling with the aftermath of third-party vendor breaches that cascaded through their operations.

This isn’t coincidence – it’s the new reality of healthcare cybersecurity.

The Vendor’s Vendor Problem

“We are big enough to have these experts on staff that are our experts to protect us,” one CMIO explained. “Sometimes I feel that that can be a barrier to agility because of how strict we are and how thorough we are in those evaluations. But I think that we can’t ensure that our partners do the same.”

Here’s the challenge: Healthcare organizations have become incredibly sophisticated at vetting direct vendors. The contracting process is rigorous, security assessments are thorough, and compliance requirements are non-negotiable.

But what happens when your vendor makes a deal with another vendor? Suddenly, you’re exposed to risks you never evaluated, from companies you’ve never heard of, through relationships you don’t control.

One security leader illustrated this perfectly: “I’m going to make a deal to use Vendor X to do something for me here. But Vendor X may make a deal with Vendor Y that lets them do their job. So if there’s a problem with Vendor Y who I’m not technically contracted with, but my vendor needs them to function, I can’t control that.”

When the Ecosystem Fails

OChange Healthcare incident provides a stark example. When its systems went down due to a cyberattack, it wasn’t just Change Healthcare that suffered – it was every healthcare organization that relied on its prescription processing services.

One CMIO described the impact: “We had a lot of issues sending prescriptions, receiving them, having issues being unclear of what went through, what didn’t go through, and who didn’t have their medications.”
Odownstream clinical impact was immediate and severe. Patients couldn’t get medications, providers couldn’t verify prescription statuses, and healthcare teams scrambled to identify which patients might be affected. This was a direct patient safety issue caused by a vendor incident completely outside the control of healthcare providers.

But the clinical impact was just the beginning. The compliance implications were equally severe, highlighting a fundamental challenge in healthcare’s regulatory landscape.

The Compliance Trap: When Vendor Failures Become Your Regulatory Problem

Healthcare organizations face a harsh regulatory reality: Vendor incidents don’t absolve them of compliance responsibilities. In fact, they often amplify them.

HIPAA requires covered entities to establish Business Associate Agreements with vendors handling protected health information. While these agreements theoretically transfer some liability, the practical reality is different. When a vendor suffers a breach, the healthcare provider still faces potential penalties, regulatory scrutiny, and mandatory reporting requirements.
Oreporting burden alone creates significant operational strain. HIPAA’s proposed 72-hour reporting mandates, similar to regulations like EU NIS2 and DORA for cross-border institutions, require healthcare providers to disclose incidents quickly, regardless of whether the breach originated from their own systems or a vendor’s.

As one CMIO noted: “We actually have to communicate to the state, to the Centers for Medicaid and Medicare Services: ‘This is what’s going on. This is where we are with our recovery.’”

This means that during an active incident – when clinical teams are scrambling to maintain patient care and IT teams are coordinating recovery efforts – compliance teams must simultaneously investigate, document, and report on incidents they didn’t cause and may have limited visibility into.
Odata sovereignty challenge adds complexity. Vendors storing healthcare data outside approved regions can trigger compliance violations that organizations may not even know exist until an incident forces a comprehensive audit of their vendor ecosystem.

“We require [vendors] to give us anything and everything we asked for to review,” explained one security leader who’s experienced a vendor ransomware attack. “So, there was actually no limitations on what we could ask.”

But this level of oversight is typically only possible with the largest vendor relationships, leaving many smaller but still critical vendor dependencies in compliance blind spots.

The CrowdStrike Wake-Up Call

OCrowdStrike incident drove home another reality: When critical infrastructure providers fail, the entire healthcare ecosystem fails simultaneously.

“We did [tabletop exercises] with the assumption that it would be a ransomware attack… a very kind of localized event,” one leader reflected. “And this was affecting the entire ecosystem. And that’s where we [learned] that we needed to have more resiliency practices that would incorporate where the ecosystem itself would be widely affected.”
Ochallenge wasn’t just technical – it was operational and regulatory. When everyone is down at once, the usual backup plans (like calling vendors for support or switching to alternate providers) simply don’t work.

Healthcare organizations faced not only interrupted patient care and massive downtime costs but also complex compliance reporting requirements for an incident that originated entirely outside their control.

Beyond Traditional Risk Assessment

Healthcare organizations are discovering that their traditional approach to vendor risk management isn’t enough. The standard process – sending questionnaires, reviewing documentation, checking compliance certifications – only covers direct relationships.

But post-incident, the conversation is changing. Instead of just asking “Do you do this? Do you do that?” organizations are demanding to see exactly how vendors execute security and recovery plans. They’re asking for evidence of testing, requiring contractual rights to review sub-vendor relationships, and building in financial protections.

The New Vendor Relationship Model

Forward-thinking healthcare organizations are taking several concrete steps to address ecosystem risk:

  • Data sovereignty: “We want to start taking more ownership over the data… so that we have something we can rebuild or even switch over to another third party if possible,” one leader said.
    Rather than letting vendors hold all the data, organizations are requiring regular data exports and maintaining their own copies of critical information. This approach helps address data residency requirements and enables compliance continuity even when vendors fail.
  • Enhanced contractual evolution: Post-incident contract negotiations now address compliance obligations explicitly. Organizations are demanding notification timelines that meet regulatory requirements, recovery guarantees that minimize downtime costs, and financial compensation for both direct losses and compliance penalties resulting from vendor-caused outages.
  • Compliance-aware update management: The CrowdStrike incident highlighted how vendor updates can create both operational and compliance risks. Many organizations have implemented “two versions behind” policies for critical security updates, balancing the risk of delayed patches against the risk of compliance violations from untested updates that could cause widespread outages.
  • Regulatory integration in vendor management: Organizations are building compliance considerations directly into vendor evaluation and ongoing oversight. This includes knowing vendors can meet the same 72-hour reporting requirements, maintain appropriate data residency, and provide the documentation needed for regulatory reporting.

The Insurance Industry’s Perspective

Perhaps most telling is how the insurance industry views these risks. As one security leader shared from a colleague in insurance risk modeling: “The number one risk that we have is the kind of outage like CrowdStrike, where we’re so dependent upon these technology platforms that when we’re out, there’s massive disruptions in services and in operations. She says that’s the number one risk in our risk model. It’s not ransomware attacks.”

This shift in risk assessment reflects a fundamental change. Traditional cybersecurity focused on preventing bad actors from getting in. Modern cybersecurity also must address the reality that critical vendors – with the best of intentions and strong security practices – still can bring down entire ecosystems through operational failures.

The Minimum Viability Challenge in an Ecosystem World

Traditional recovery planning often assumes you can restore everything systematically, but when entire ecosystems fail simultaneously, organizations must focus on minimum viable recovery (MVR).
Oconcept of minimum viability becomes critical when your vendors, their vendors, and potentially your backup vendors are all affected. As we’ve explored in our analysis of healthcare cyber threats and MVR, the question isn’t just “How do we recover everything?” but “What are the bare essentials we need to keep patient care running while the ecosystem rebuilds itself?”

This ecosystem reality makes organizational recovery readiness more complex than ever. When you can’t rely on your usual vendors or backup providers, your MVR plan must account for true independence from the broader ecosystem – at least temporarily.

Moving Forward

Organizations can’t just secure their own perimeter; they need to understand and plan for the interconnected web of dependencies that modern healthcare relies on. This means fundamentally rethinking business continuity planning to account for simultaneous ecosystem failures. It means maintaining data sovereignty even when using SaaS providers. And it means accepting that some risks simply can’t be eliminated – only managed and planned for.
Ohealthcare leaders we spoke with weren’t pessimistic about these challenges; they were pragmatic. They understand that the benefits of interconnected, cloud-based healthcare systems far outweigh the risks.

Test Your Ecosystem Resilience

Understanding the risks is just the first step. The next is honestly assessing whether your organization is prepared for the new reality of interconnected failures. How confident are you that your MVR plan would work when your usual vendors and backup systems also are compromised?

Healthcare organizations serious about ecosystem resilience should evaluate their readiness across three critical areas: business-critical prioritization, measurable technical response, and organizational recovery readiness. Commvault’s Minimum Viability Healthcare Assessment helps evaluate your current capabilities and offers actionable recommendations for closing any gaps.

Don’t wait for the next ecosystem-wide incident to discover whether your recovery plans account for the reality of interconnected healthcare IT. Take the assessment today and build true resilience for tomorrow’s challenges.



Blogs relacionados:

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

A powerful go-to-market strategy is what separates leaders from the pack in the competitive cyber resilience market. At Commvault, we’re dedicated to providing our partners with the strategic resources needed to help grow revenue, build customer trust,esolidify your reputation as a market leader with Commvault.
That’s why we are excited to announce two game-changing resources designed to elevate your salesemarketing efforts: a reimagined Commvault Campaigns Hubrepensado e os novosGuias de Vendas para Parceiros “At-A-Glance.

Otimize seu marketing com o Campaigns Hub

Based on partner feedback, our newly imagined Campaigns Hub is your destination for ready-to-use, results-driven marketing. The Campaigns Hub is a powerful, intuitive platform that simplifies the creation of targeted campaigns, helping you build awareness, generate leads,eupsell Commvault’s suite of solutions. And now our platform integrates seamlessly with your existing strategies, enabling cohesive brand messagingemaximum impact.
With the Campaigns Hub, you’ll find:

  • Targeted campaigns you can launch in minutes. Choose from a library of pre-built multi-language campaigns – from “Securing Continuity for Minimum Viable Business” to “Microsoft Active Directory Protection” –ecustomize the content to fit your audience’s unique needs.
  • A new, powerful webcast program. Leverage Commvault’s best speakersecontent directly from the Campaigns Hub using our on-demand webcasts along with the promotional materials to drive leadseawareness.
  • A new, co-branded assessment tool. Contact our Marketing Conciergeerequest a co-branded minimum viability assessment tool that provides benchmarks to your customers in minuteseputs leads directly in your inbox.  
  • High-value customer assets to use on your platform or the hub. You can now access key Commvault customer contentepromotional campaigns through the Campaigns Hubeintegrate these valuable assets into your broader marketing initiatives on the hub, or downloadeuse on your platform.
  • Our complimentary Marketing Concierge service that makes campaigns even easier. You don’t need to use MDF or pay for our Marketing Concierge service to help you customizeerun the latest Commvault campaigns to grow your business. Try out the service with a sessão individual de ativação de campanha.

Aumente o sucesso das vendas com manuais de referência rápida

To complement your marketing efforts, Commvault also has launched our new Guias de Vendas para Parceiros “At-A-Glance. We’ve condensed our most popular os Manuais de Vendas para Parceiros into a concise, easy-to-use one-page format, packed with the essential tools you need to articulate valueeenhance customer engagement.
Each playbook includes:

  • Concise call scripts: Confidently articulate the unique value propositions of Commvault’s productsesolutions.
  • Objection handling: Turn potential roadblocks into opportunities with prepared responses to common customer challenges.
  • Customer-ready materials: Accelerate sales cycles by sharing curated whitepapers, solution briefs, case studies, eBooks,emore.

By combining the power of the Commvault Campaigns Hub with the strategic guidance of the At-A-Glance Sales Playbooks, you can create impactful, end-to-end campaigns that drive customer engagementeachieve greater sales success.

Desbloqueie seu potencial com a Commvault

Ready to transform your go-to-market strategyemaximize the value of Commvault’s offerings? Explore the Commvault Campaigns Hubeos Manuais de Vendas para Parceirosno Portal de Parceiros. Comece por conta própria ou agende umasessão individual de ativação de campanhacom nosso Concierge de Marketing gratuito para obter suporte personalizado.

More related posts


Cyber Resilience

Read more about Cyber Resilience

Quando os ciberataques ocorrem, a rapidez não é tudo. Restaurar rapidamente os dados comprometidos simplesmente reintroduz a ameaça, criando um ciclo vicioso de infecção e reinfecção.

Recentemente, escrevi um artigo técnico com meus colegas daKyndrylintitulado“Redefinindo Cyber Recovery: apresentando o tempo médio para recuperação limpa (MTCR) where we introduced a fundamental shift: measuring how fast you can restore from clean, verified data rather than just any available backup.

Here are the five critical steps that determine your organization’s MTCR:


  1. Crie um ambiente limpo para a recuperação.

The problem: Recovery to an infected infrastructure will simply reinfect your restored systems.

The solution: Isolated Recovery Environments (IREs) or cleanrooms – compute and storage infrastructure physically or virtually separated from production environments where attackers never had access.

Reality check: Without an IRE, modern forensic teams need 24 to 72 hours to certify complex hybrid environments as “clean.” Your MTCR automatically becomes measured in days, not hours.


  1. Encontre dados limpos para recuperar.

The hidden threat: Modern attackers operate in stealth for weeks before launching attacks, seeding malicious payloads throughout your environment – including backup systems.

The breakthrough: Automated scanning for Indicators of Compromise can help identify clean backup sets without the trial-and-error cycle of testing each backup until you find one that works.

Collaboration required: This step demands tight integration between SysOps teams (who manage backups) and SecOps teams (who understand current threats). Forensic analysis reveals attack signatures that must be fed into the scanning process.


  1. Recuperar dados em tempo aceitável.

The uncomfortable truth: Enterprise backup solutions often deliver “10+ hours per terabyte” recovery performance. Scale this to typical enterprise services requiring hundreds of terabytes, and you’re looking at weeks of recovery time.

The reality: Most backup infrastructure was designed for nightly incremental backups (5% data change), not full-scale business restoration (100% recovery).

The solution: Purpose-built cyber resilience platforms with high-performance recovery capabilities, combined with minimum viable company (MVC) prioritization – focusing on the critical 20% of services that enable 80% of business function.


  1. Mantenha a integridade dos dados em toda a platform.

The challenge: Enterprise systems don’t exist in isolation. During recovery, systems restored from backups taken at different times create data integrity nightmares.

Example scenario:

  • Banco de dados de clientes: backup às 3h da manhã de terça-feira
  • Sistema de faturamento: segunda-feira, 23h, backup
  • Sistema de inventário: backup às quartas-feiras às 6h

Result: Orders for customers who don’t exist, invoices for products not in inventory.

The Process: Restoration sequencing based on dependencies, data reconciliation across integrated systems, and comprehensive consistency checks before production return.


  1. Teste antes do retorno à produção.

The rush trap: Under pressure, IT teams often rush systems back online without comprehensive testing, leading to partially functional systems or reintroduction of attack remnants.


Validação abrangente:
  • Teste funcional dos principais processos de negócios
  • Validação de segurança por meio da verificação de vulnerabilidades
  • Verificação da integridade dos dados em todas as plataformas
  • Validação dos processos de negócios pelas equipes de aplicação

Critical success factor: Pre-define your MVC acceptance criteria – the specific functionality that must work before you’re truly “recovered.”


O Desafio da Integração

These aren’t sequential steps – they’re interconnected capabilities that must work together. Your MTCR is only as fast as your slowest step and only as reliable as your weakest validation point.

The investment reality: Clean recovery requires purpose-built cyber resilience platforms, isolated recovery environments, automated scanning tools, and dedicated recovery networks. But the cost of prolonged downtime and reinfection is far greater.


Próximos passos:
  1. Avalie quanto tempo cada etapa levaria em seu ambiente atual.
  2. Identifique sua maior lacuna.
  3. Calcule o custo do tempo de inatividade prolongado em comparação com o investimento em infraestrutura.
  4. Comece pelos serviços comerciais mais críticos.

The era of “backup and pray” is over. Organizations that master these five steps don’t just recover faster – they recover once, cleanly, and with confidence.


Saiba mais

Assista ao webinar “A métrica que faltava para Cyber Recovery” para saber mais sobre essa nova métrica. Leia o white paper completo,Redefinindo a Recovery cibernética: apresentando o Tempo Médio para Recovery Completa, para saber mais sobre essa métrica crítica.Darren Thomson is a Field CTO at Commvault. Be sure to catch him in the podcast series, STRIVE.

More related posts


CleanroomRecovery_Thumbnail_888x500

Commvault Cleanroom

Read more about Commvault Cleanroom

The fifth edition of theState of Data Readiness in ANZ report, a Tech Research Asia Insights Report commissioned by Commvault, offers a critical look into the current landscape of data management, cybersecurity, and regulatory pressures faced by organisations in Australia and New Zealand (ANZ).Based on research from 408 companies across the region, the report uncovers key trends and stark realities about how businesses are coping with an increasingly complex digital environment. Given we often look at research findings on a global scale, it is particularly valuable to have a local perspective on data readiness.While data growth rates have seen a slight easing, the challenges surrounding data management, security, and recovery have intensified. Here are some of the standout insights from the report.

The Data and Regulatory Environment: A Tangled Web

Organisations are grappling withsprawling data estates and a tightening web of regulations.

  • Slowing growth, persistent sprawl: The annual data growth rate in ANZ has marginally slowed from 28% last year to 27% this year. A majority, 62%, continue to operate in blended (multi- or hybrid cloud) data environments, and this is projected to increase to 71% by 2026.
  • Confidence gap: A concerning number of organisations lack confidence in their ability to restore business operations after a breach, with 54% of Australian and 63% of New Zealand businesses feeling unprepared.
  • Regulatory complexity: The regulatory landscape is becoming more difficult to navigate. Fifty-five percent of Australian and 53% of New Zealand companies are now required to maintain data copies in separate cloud environments for resiliency. Furthermore, more than a third of organisations face conflicting data regulations across different geographies.
  • The rise of AI regulation: AI-specific compliance is a growing concern, with 28% of companies already subject to such regulations and another 40% expecting to be within the next year.

The AI Paradox: High Adoption Despite High Risk

Enthusiasm for AI is strong,yet it’s coupled with significant security concerns.

  • Risk vs. reward: While 73% of ANZ organisations are using business-focused AI solutions, 68% of them believe this adoption increases the likelihood of a cybersecurity breach.
  • Lack of due diligence: A significant 63% of organisations admitted to not conducting thorough and extensive security audits of their AI tools before deployment.
  • Policy deficit: Only 29% of companies have comprehensive policies in place to protect the data and content generated by AI solutions.

Recovery: A Disconnect Between Expectation and Reality

The gap between business leaders’ recovery expectations and the on-the-ground reality for IT teams remains a major issue.

  • The expectation-reality gap: Eighty percent of business leaders expect to recover from a cybersecurity incident within five days. However, the stark reality is that it takes an average of four weeks to restore a minimal level of business operation.
  • Ransomware’s reach: Seventy percent of ANZ organisations have received a ransomware demand, and of those, 20% admitted to paying it. Interestingly, of the companies with a stated “no payment” policy, 15% still ended up paying the ransom when faced with an actual attack.
  • The power of experience: The report reveals a fascinating insight: Experience is a harsh but effective teacher. Companies that have been breached are 1.5 times more likely to conduct thorough reviews of AI tools and twice as likely to test all mission-critical workloads as part of their incident response plans. Conversely, companies that have not been attacked are 1.5 times more likely to believe they can recover within a single day.

The 2025 State of Data Readiness report underscores a challenging environment for ANZ organisations. From regulatory hurdles to the double-edged sword of AI and the persistent disconnect in recovery expectations, the path to true cyber resilience is complex.To gain a deeper understanding of these findings, download the full report.


More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

I’m thrilled to share that we were just announced as a winner in Udemy’s 2025 Learning Excellence Awardsin the Leading With Learning Science category. In this awards program, Udemy recognized organizations that have successfully achieved impactful results in learning and development through AI-supported upskilling.

As one of the winners in the Leading With Learning Science category, Commvault was recognized for prioritizing the integration of learning into the workflow, engaging learners through micro-learning, and crafting personalized learning experiences.

We are honored to be included on a list of visionary leaders that are transforming learning at scale and equipping their employees to thrive in an AI-forward future.

O investimento em nosso pessoal é importante

Over the past year, we’ve expanded on our investment in learning and development by implementing an all-new, comprehensive learning platform, Pathfinder, to provide our Vaulters with the tools, resources, and opportunities they need to enhance their skills and advance their careers.

Our new platform has a wealth of learning modules, ranging from live instructor led sessions to on-demand and self-paced learning modules, including Udemy Business’ 30,000+ expert-led courses covering topics across technology, business, leadership, productivity, cybersecurity, and GenAI. Udemy Business isn’t just another online training tool – it’s a strategic driver of capability building within Commvault, and we’re delighted to offer our global Vaulter community access to Udemy Business.

We’ve also developed curated learning paths tailored for our teams, with a focus on the power of AI. The development of our Vaulters is key to Commvault’s success, and with Udemy Business, we’re giving them the tools to build their future growth, all while harnessing the potential of AI.

To learn more about what it’s like to work at Commvault, clique aqui.


More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

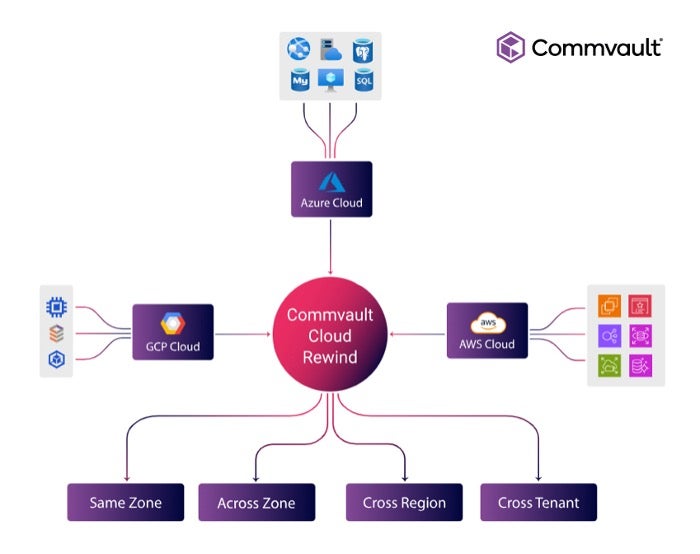
A mudança global para arquiteturas cloud redefiniu o que significa alcançar segurança e resiliência. Cloud são dinâmicos por natureza; os recursos são frequentemente atualizados, adicionados ou removidos; as aplicações se estendem por regiões e múltiplas nuvens; e a infraestrutura evolui mais rapidamente do que a maioria das ferramentas de recuperação consegue acompanhar. Os modelos tradicionais de backup, criados para sistemas estáticos, têm dificuldade em acompanhar esse ritmo e complexidade.Commvault Cloud Rewind™ is built from the ground up to handle this new reality. With an architecture purpose-built for cloud-scale recovery, Cloud Rewind helps you restore entire cloud environments, including applications and their dependencies, with ease.

This becomes essential in modern environments where applications are composed of microservices, containers, and serverless components that are often ephemeral and spread across multiple platforms.

Resources may change daily, and ownership is often decentralized across teams. Configuration drift, inconsistent change management, and the growing use of third-party services all make recovery harder. Even when manual backups are available, critical infrastructure metadata is often missing, making restorations unreliable or incomplete.

In this ecosystem, Cloud Rewind brings order to the chaos. By leveraging ongoing discovery, orchestration, and cloud-native operations, it provides fast and consistent recoverability. Whether you’re dealing with a simple misconfiguration or a full-blown cyberattack, Cloud Rewind helps restore critical resources in minutes.

A Deep Dive Into the Design: The Cloud Rewind Architecture 

Cloud e mapeamento de dependências:

  • Cloud discovery and dependency mapping: Cloud Rewind automatically discovers all relevant cloud resources and captures the metadata needed for accurate and repeatable recovery. This includes complete configuration settings, dependencies, and infrastructure details.
  • Drift analysis: Cloud environments change rapidly. Cloud Rewind tracks these changes with regular drift analysis, comparing current configurations to known protected states. This keeps security teams informed about any deviations from expected configurations, helping maintain crucial alignment.
  • Automated daily cloud rebuilds: Reverting to a safe state is not enough; it has to be done quickly and without errors. Cloud Rewind helps enable this with automated recovery testing. You can rebuild entire cloud infrastructures, applications, and data using on-demand environments. These temporary environments can later be deleted to help reduce testing costs.
  • Integrated cyber recovery: Cloud Rewind works with Commvault’s broader data resilience platform, effectively combining backup, recovery, and threat intelligence. This unified approach provides better control and coordination during security incidents, helping teams move from detection to full recovery with speed and clarity.

Com uma infinidade de recursos avançados adaptados para organizações modernas cloud, Cloud Rewind recuperação eficaz e simplificada. Embora várias soluções do setor ofereçam recuperação simples de desastres para cloud , esses recursos ajudam Cloud Rewind . Cloud Rewind a resiliência da recuperação a um novo patamar com:

Amplacloud , com suporte nativo para AWS, Azure e GCP.

  • Cobertura completa de recursos, incluindo computação, armazenamento, rede, IAM, DNS, contêineres e serviços sem servidor.
  • Proteção detalhada de metadados de infraestrutura, utilizando uma máquina do tempo com cofre duplo.
  • Gráficos explícitos de dependência de aplicativos, não apenas reconhecimento no nível dos recursos.
  • Recuperação como código, para uma recuperação orquestrada e orientada por código.
  • Validação contínua, utilizando reconstruções automatizadas regulares em cloud isolados cloud .
  • Baixa carga operacional, com alta transparência por meio de um modelo SaaS .
  • Cloud Rewind proteção, inteligência e automação para oferecer recuperação rápida e confiável em cloud complexos cloud . Isso ajuda Cloud Rewind em um campo competitivo e permanecer à frente.

Cloud para recuperação completa Cloud

O Commvault Cloud Rewind desenvolvido para oferecer cloud completa cloud , protegendo cargas de trabalho modernas e cloud. Em vez de simplesmente fazer backup de recursos isolados, ele captura e recupera cloud completos cloud , conhecidos como Cloud . O Cloud Rewind oferece suporte a uma ampla gama de serviços nativos da nuvem, incluindo máquinas virtuais, discos, gateways, grupos de segurança, VPCs, plataformas DBaaS e cargas de trabalho em contêineres. Assim que uma conexão com a nuvem é estabelecida, o Cloud Rewind realiza a identificação automatizada de todos os recursos em um ambiente. Em grande escala, isso pode ser extremamente significativo. Para um cliente da Commvault, foram descobertos 94.237 recursos, com 7.811 recursos protegidos organizados em 19 assemblies distintos.

Para obter proteção completa, os clientes podem começar definindo políticas personalizadas para seus conjuntos de nuvem. Essas políticas regem a frequência dos snapshots, as regras de retenção e as preferências de replicação. Os snapshots podem ser criados com frequência de até 15 minutos ou anualmente, dependendo dos objetivos de recuperação da carga de trabalho. Esses snapshots podem ser usados para backups rápidos em um momento específico e para reidratação rápida.

Com seu uso sofisticado exclusivamente de instantâneos na nuvem, o Cloud Rewind oferece proteção por uma fração do custo das caras arquiteturas tradicionais de alta disponibilidade ou réplicas de leitura. Como não é necessária uma infraestrutura de espera dedicada, os clientes pagam apenas pelo armazenamento dos instantâneos e pela computação temporária durante as operações de Recovery. Essa flexibilidade permite que os clientes ajustem com eficácia os cronogramas de proteção para equilibrar os requisitos de RPO com os custos de armazenamento.

Por fim, Cloud Rewind resiliência cloud , realizando a recuperação no nível Cloud . Quando chega a hora da restauração, Cloud Rewind recriar o aplicativo completo, incluindo as configurações de recursos, as definições de rede e as dependências, exatamente como existia em qualquer momento. A recuperação também pode ter como alvo a região original para uma reversão rápida ou ser redirecionada para uma região, assinatura ou projeto diferente para dar suporte a casos de uso de recuperação de desastres.

Ao centrar a recuperação nas aplicações dos clientes, Cloud Rewind a complexidade tradicional por uma clareza inestimável. Com descoberta automatizada, políticas flexíveis e proteção econômica baseada em instantâneos, Cloud Rewind ajudar os clientes a cumprir objetivos de recuperação rigorosos, minimizando os custos de infraestrutura.

Commvault Cloud Rewind is built for full-stack cloud resilience, offering protection for modern, cloud-native workloads. Instead of simply backing up isolated resources, capturing and recovering entire cloud applications, referred to as Cloud Assemblies.

Cloud Rewind supports a wide range of cloud-native services, including virtual machines, disks, gateways, security groups, VPCs, DBaaS platforms, and containerized workloads. Once a cloud connection is established, Cloud Rewind performs automated identification of all resources in an environment. At scale, this can be highly significant. For one Commvault customer, 94,237 resources were discovered, with 7,811 protected resources organized into 19 distinct assemblies.

For complete protection, customers can begin with the definition of policies tailored to their Cloud Assemblies. These policies govern snapshot frequency, retention rules, and replication preferences. Snapshots can be taken as frequently as every 15 minutes or as infrequently as annually, depending on the workload’s recovery objectives. These snapshots can be used for rapid, point-in-time backups and fast rehydration.

With its sophisticated use of only cloud snapshots, Cloud Rewind offers protection at a fraction of the cost of expensive traditional high-availability or read‑replica architectures. As dedicated standby infrastructure isn’t required, customers pay only for snapshot storage and temporary compute during recovery operations. This flexibility allows customers to effectively fine-tune protection schedules to balance RPO requirements against storage costs.

Finally, Cloud Rewind provides cloud data resilience by performing recovery at the Cloud Assembly level. When it’s time to restore, Cloud Rewind can recreate the complete application, including the resource configurations, network settings, and dependencies, exactly as it existed at any point in time. Recovery also can target the original region for a quick rollback or be redirected to a different region, subscription, or project to support disaster recovery use cases.

By centering recovery around customer applications, Cloud Rewind replaces traditional complexity with invaluable clarity. With automated discovery, flexible policies, and cost‑effective snapshot-based protection, Cloud Rewind can help customers meet stringent recovery objectives while minimizing infrastructure overhead.

Cloud Rewind um novo padrão de resiliência na cloud, afastando-se dos modelos tradicionais de recuperação de desastres e adotando uma abordagem projetada para ambientes dinâmicos e modernos. Ao se concentrar na recuperação completa de aplicativos, em vez de recursos isolados, ele ajuda a evitar tempo de inatividade, reduzir riscos operacionais e oferecer suporte à recuperação e restauração rápidas e coordenadas em cloud .

Uma de suas principais inovações é a máquina cloud com cofre duplo patenteada. Essa abordagem exclusiva protege cofres imutáveis em diferentes nuvens de hiperescala para recuperações rápidas de aplicativos. Esse design não apenas protege contra falhas e ameaças cibernéticas, mas também permite a recuperação precisa e pontual de ambientes de aplicativos inteiros. Com uma infinidade de recursos poderosos que apoiam o crescimento das empresas modernas, Cloud Rewind impacto:

Cloud Rewind introduces a new standard for resilience in the cloud, shifting away from legacy disaster recovery models toward an approach designed for dynamic, modern environments. By focusing on full application recovery instead of isolated resources, it helps avoid downtime, reduce operational risks, and support rapid, coordinated recovery and restoration across cloud platforms.

One of its core innovations is the patented dual-vault cloud time machine. This unique approach protects  immutable vaults in different hyperscale clouds for rapid application recoveries. This design not only defends against failures and cyber threats but also enables precise, point-in-time recovery of entire application environments.

With a myriad of powerful capabilities that support the growth of modern businesses, Cloud Rewind makes an impact:

Em todos os setores, Cloud Rewind proporcionando resultados mensuráveis. Assim, surgiram rapidamente casos reais proeminentes de organizações que se beneficiaram dessa solução inovadora. SaaS da empresa EdTechPragya Systems’ SaaS resiliency increased by a staggering 300% with Cloud Rewind. Similarly, backed by the powerful capabilities of Cloud Rewind, an líder em eDiscoveryse recuperou de um grande ataque de ransomware.

No setor de serviços financeiros, umaimportante instituição de crédito hipotecário decreased cloud application resilience cost by 85% with Cloud Rewind. Finally, leveraging Cloud Rewinds’ app-centric BCDR approach, a global cloud solutions provider achieved a 99.9% cloud app resilience SLA.

Cloud como nunca antes

O Commvault Cloud Rewind um ponto de inflexão na forma como as organizações abordam a resiliência. Em vez de depender de ferramentas fragmentadas ou processos de recuperação rígidos, Cloud Rewind uma arquitetura cloud que acompanha as mudanças. Com automação profunda, recuperação centrada em aplicativos e resultados comprovados em todos os setores, ele permite que as organizações protejam o que é importante, se recuperem mais rapidamente e operem com confiança.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

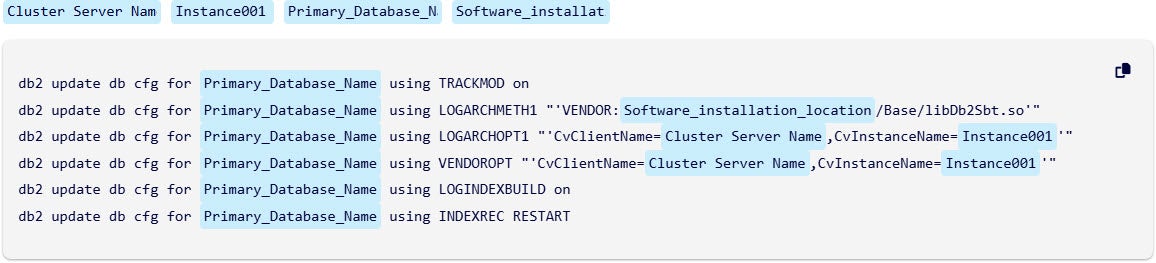
A maioria dos sites de documentação corporativa que contêm blocos de código utiliza estilos que indicam espaços reservados. A intenção deveria ser clara,e os leitores deveriam saber o que precisam alterar,mas a experiência deixa a desejar.Esses mesmos estilos também são usados para ênfase,rótulos da interface do usuário ou sintaxe em outras partes da documentação. Os espaços reservados mais comuns que as equipes de redação técnica utilizam para identificar blocos de código — e que são empregados como outros estilos — incluem:
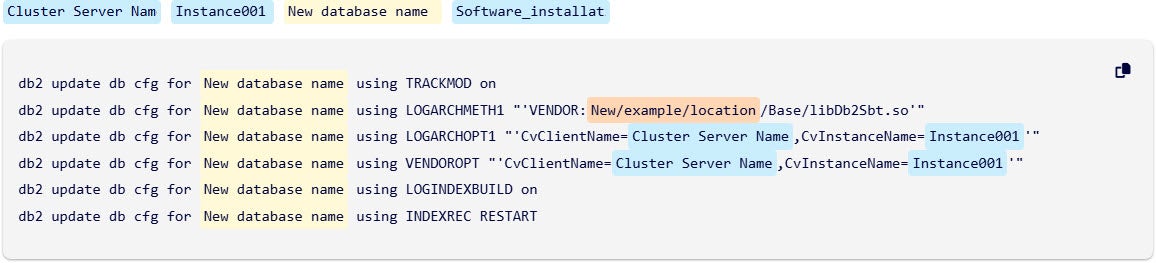
  • Italics
  • {Colchetes}
  • Bold
  • exemplo_nome_##
  • TODAS EM MAIÚSCULAS
  • Alguma combinação das opções acima
  • Algo completamente diferente

This overlap makes placeholder tracking and management more complex than it should be. On a small scale,this can feel like a nuisance. But as documentation libraries grow and spread across teams and years,it creates problems for both authors and readers. What is meant to simplify placeholder management instead complicates it,because the same styling is reused elsewSaiba mais no SHIFT 2025.

The result can put you in a familiar position: You must figure out the placeholder convention and attempt to update them all if you want to succeed. If you miss one placeholder,the command may not work as expected. Other issues can appear,such as errors,unexpected configurations,or even settings you didn’t know could be changed.

Other code block approaches only go so far:

  • Static blocks (with or without syntax highlighting) are essential when you already know the values. They are fast and copy-to-run ready. These are best when you don’t need to modify anything.
  • Inline editors go to the other extreme and enable you to update text directly within the code block,but often at the expense of context – undo becomes unreliable and small mistakes erase the structure you need.
  • Developer API editors let you try out requests in real time,and they’re a great fit when the main audience is developers working directly with APIs. But enterprise documentation serves broader roles and use cases,and that style of interactivity is often missing wSaiba mais no SHIFT 2025 it would still add value.

Preenchendo a lacuna com blocos de código interativos

Nossos blocos de código interativos preenchem essa lacuna,transformando uma parte historicamente frágil da documentação (o placeholder) em algo claro,editável e escalável.

You get the same command as before with the same formatting and structure,only now the placeholders have become editable fields. Each one has a clear label (like before) so you don’t have to interpret symbols or rely on guesswork.

You update the values right inside the block,with the surrounding context still visible. That means you see the example,the rest of the page’s contents,and your inputs all in one place. It can help you shape a more relevant snippet before you click Copy.

You can change those values before copying them or leave them as-is and edit them later in another editor. Either way,the structure stays the same and what you copy reflects exactly what you see in the block.

Placeholders in a code block that have the same name become linked. When you change the value of a placeholder field above the code block,all linked fields can update at the same time so that you can more consistently edit fields that have the same placeholder value. This helps reduce potential find and replace mistakes when working in a text editor.

A Mudança de Experiência

Essa mudança resolve dois problemas de uma só vez. Para os leitores,ela reduz as suposições e evita erros. Chega de decifrar chaves ou colchetes angulares. Para os autores,ela separa a semântica do estilo,permitindo que os placeholders sejam rastreados,auditados e atualizados programaticamente. Isso possibilita o reconhecimento de versões,regras de validação e consistência entre ambientes. Inconsistências herdadas são corrigidas ao longo do processo,tornando a biblioteca como um todo mais fácil de manter.

Blocos de código interativos transformam uma das partes mais difíceis da documentação — os placeholders baseados em estilo — em algo preciso,sustentável e rápido de usar. A experiência parece intencional,em vez de improvisada. E,pela primeira vez,gerenciar exemplos de código em grande escala cria oportunidades de melhoria,em vez de obstáculos.

Ao vivo agora em Software,SaaS e muito mais

This experience is already live across our documentation site for Software (versions11.42,11.40,11.36,and 11.32),SaaS,and other related sites on https://documentation.commvault.com/.

Try it out the next time you browse and run across a code block – edit a few fields,click “Copy,” and see how much easier it is to get started after you bring it into your editor.

Observações:
  • Carefully review any code before you run it,whether it’s from an interactive or static code block.
  • When you refresh a page after changing placeholders in an interactive code block,all changed placeholders revert to their default values.

Saiba mais sobre como usar blocos de códigoSaiba mais no SHIFT 2025.


More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Na corrida pela implantação da IA, as organizações estão investindo pesadamente na segurança da infraestrutura tradicional. As equipes de segurança cibernética estão implementando sistemas avançados de detecção de ameaças para terminais e implantando arquiteturas de confiança zero para ambientes em nuvem. No entanto, muitas estão dedicando menos atenção a um componente crítico dos sistemas modernos de IA: a camada de orquestração que conecta os modelos de IA às fontes de dados e aos aplicativos de negócios.

Essa camada intermediária inclui a infraestrutura que torna a IA funcional em ambientes corporativos: bancos de dados vetoriais que armazenam embeddings, repositórios de modelos, pipelines de dados que processam cargas de trabalho de IA, estruturas de coordenação de agentes e plataformas de orquestração, como o Model Context Protocol (MCP). Ao contrário dos aplicativos corporativos tradicionais, muitos desses sistemas carecem de estruturas de segurança estabelecidas e de práticas recomendadas.

O desafio emergente: lacunas de segurança na infraestrutura de IA

Traditional security models were designed for databases, web servers, and file systems with well-understood attack vectors. AI infrastructure introduces new components that don’t always fit neatly into existing security frameworks. Vector databases store high-dimensional embeddings, model registries house trained algorithms, and orchestration platforms coordinate between AI agents and external systems.

Take MCP as an example. While MCP itself incorporates security considerations, the broader ecosystem of AI orchestration frameworks often operates with different security assumptions than traditional enterprise applications.

Research from organizations like NIST has highlighted that AI systems frequently require elevated privileges to access diverse data sources, communicate across network boundaries for model inference, and integrate with legacy systems not designed for AI workloads.

This creates an expanded attack surface. According to recent security research, compromise of AI orchestration layers can enable attackers to manipulate model outputs, corrupt training processes, or gain access to the valuable datasets and custom models that represent significant organizational investment.

A consolidação de dados cria novas concentrações de risco

AI adoption has accelerated data centralization initiatives across industries. Organizations are aggregating diverse datasets into centralized repositories to enable machine learning workflows. While platforms like Databricks and Snowflake have built robust security features, the challenge lies in the volume and variety of data being consolidated.

These repositories often contain some of the most sensitive organizational data: customer behavioral patterns, proprietary research datasets, financial transaction records, and competitive intelligence. The security challenge isn’t necessarily inadequate access controls, but rather the concentration of high-value data in systems optimized for analytics rather than security.

A particular concern is training data integrity. Security researchers have demonstrated that subtle corruption of training datasets can introduce persistent vulnerabilities into AI models. For instance, researchers at universities have shown how poisoned datasets can cause fraud detection models to systematically miss specific attack patterns, or cause recommendation systems to exhibit subtle biases that may not be detected for months.

Exemplos do mundo real incluem:

A escala dos conjuntos de dados de treinamento modernos de IA agrava esses riscos. Quando as organizações processam petabytes de dados de treinamento, medidas tradicionais de segurança pontuais, como o gerenciamento abrangente de chaves de criptografia e o registro detalhado de acessos, tornam-se operacionalmente complexas. As organizações precisam de abordagens de segurança projetadas para a escala e a velocidade do processamento de dados de IA.

Modelos de IA, como ativos de alto valor, exigem proteção especializada

Trained AI models represent significant organizational investment – often millions of dollars in development costs and months of training time using expensive computational resources. More importantly, they embody institutional knowledge and competitive advantages developed over years.

However, many organizations apply traditional data security approaches to AI models without accounting for their unique characteristics. Unlike conventional intellectual property, AI models face specific threat vectors:

Model extraction attacks: Researchers have demonstrated techniques where attackers can query a model repeatedly to reverse-engineer its functionality or training data. Google’s research team has published studies showing how this can be accomplished against various types of production models.

Adversarial attacks: These cause models to make specific mistakes or reveal information about their training data. The field of adversarial machine learning has documented numerous examples across different model types and use cases.

Model stealing: Beyond intellectual property theft, stolen models can reveal insights about business processes, customer patterns, and strategic approaches. For example, a compromised fraud detection model provides information about an organization’s risk assessment methodologies and customer transaction patterns.

Casos documentados incluem:

  • Pesquisas que mostram ataques de extração contra APIs comerciais dos principais provedores de nuvem.
  • Estudos demonstrating how recommendation model theft reveals user behavior patterns.

As organizações estão começando a implementar medidas especializadas de segurança para modelos de IA, incluindo sistemas de controle de versão de modelos que detectam modificações não autorizadas, arquiteturas de serviço seguras que limitam a exposição dos modelos e procedimentos de resposta a incidentes projetados especificamente para cenários de comprometimento da IA.

Construindo Segurança Adequada para a Infraestrutura de IA

O desafio da segurança da infraestrutura de IA representa uma mudança nas prioridades de segurança corporativa. A segurança tradicional de perímetro e de terminais continua importante, mas as organizações também devem proteger sistemas onde existem ativos valiosos na forma de algoritmos, onde processos autônomos operam com privilégios elevados e onde procedimentos de treinamento consomem enormes recursos computacionais em sistemas distribuídos.

Organizações líderes estão desenvolvendo estruturas de segurança específicas para IA que abordam essas características únicas. Isso inclui a implementação de rastreamento da linhagem de dados para pipelines de treinamento de IA, o estabelecimento de processos seguros de desenvolvimento e implantação de modelos e a criação de sistemas de monitoramento projetados para detectar padrões de ataque específicos da IA.

A comunidade de segurança está desenvolvendo ativamente soluções para esses desafios. Organizações como o NIST estão publicando estruturas de segurança para IA, provedores de nuvem estão adicionando recursos de segurança específicos para IA às suas plataformas e fornecedores de segurança estão desenvolvendo ferramentas projetadas para a proteção da infraestrutura de IA.

O caminho a seguir envolve:

  • Implementar controles de segurança projetados para riscos e vetores de ataque específicos da IA
  • Desenvolver procedimentos de resposta a incidentes que levem em conta as características dos sistemas de IA
  • Criação de recursos de monitoramento e detecção para ameaças específicas à IA
  • Estabelecimento de estruturas de governança para o gerenciamento de dados e modelos de IA

As organizações que abordarem proativamente a segurança da infraestrutura de IA estarão melhor posicionadas para aproveitar os benefícios da IA e, ao mesmo tempo, gerenciar os riscos associados. À medida que os sistemas de IA se tornam mais essenciais para as operações comerciais, as estratégias de segurança devem evoluir para proteger esses novos ativos e processos de maneira eficaz.Registre-se agoraem nosso evento virtual SHIFT para saber mais sobre nossas inovações de produtos e estratégias de resiliência para sua organização.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

How do you take 40 minutes of viewpoints from a panel of leading experts and condense it into a 5-minute read designed to provide you with actionable advice you can immediately use? That’s the challenge I posed to myself as I prepared to write this blog, so let me know if I delivered.

The panel: Nathan McAfee, Lead Economic Validation Analyst at Enterprise Strategy Group; Jaimie Fox, Azure Technology Strategist at Microsoft; and Chris DiRado, Principal Technologist at Commvault.

Their goal: Unpack the key findings from this crucial research (Enterprise Strategy Group Economic Validation), providing a clear-eyed view of how organizations can prepare for, and recover from, the inevitable.

The High Stakes of Slow Recovery

A cyberattack’s impact isn’t just about the initial breach; it’s the prolonged downtime that cripples operations, erodes customer trust, and racks up exorbitant costs. As Nathan explained, the study aimed to quantify the real-world difference a modern, integrated recovery solution could make.

The findings highlight a stark contrast between traditional approaches and a prepared strategy. Without an effective plan, organizations face extended outages; significant data loss; long-lasting brand damage; and a painful, manual recovery process that can take weeks or even months.

The Solution: A Unified Defense with Commvault and Azure

The study focuses on the economic benefits of the joint solution from Commvault and Microsoft Azure. This isn’t just about backup; it’s about a holistic cyber resilience platform. Jaimie emphasized the power of the integration, which provides a secure, scalable, and intelligent foundation for data protection: “The power of the Commvault solution is in the simplicity and the thoroughness. How easy it is to do these recoveries … and in the automation of the rebuild process using Azure AI and on-demand Azure tenants.”

Breakthrough Findings: Customer Reported Results

The study provided hard numbers to back up the solution’s value. Organizations using the joint Commvault and Azure solution achieve:

  • 99% faster recovery: The most dramatic finding: where organizations previously required 8.7 hours on average (with some taking 24 days for full recovery), the joint solution between Commvault and Azure enabled one customer recovery in under an hour. Nathan noted: “The 99% faster recovery – I could put decimals on that because we had so many stories of scenarios that took months to do, and now we did it in hours.”
  • 30x more frequent testing: Organizations moved from annual tests of single systems requiring 40 FTE hours, to comprehensive monthly testing of entire ecosystems completed in 30 minutes. One customer shared: “It used to take 24 to 36 hours to recover a single server instance. We can now restore everything in less than an hour.”
  • Zero reported non-recoverable events: Every customer interviewed reported zero non-recoverable events since implementing the solution. “Every person that I interviewed told me that since they’ve gone to this solution, they haven’t had a single non-recoverable event,” Nathan emphasized.
  • 94% faster rebuild: The study documented 94% faster rebuild times through Cloud Rewind technology, enabling rapid restoration of entire application environments and infrastructure.
  • Dramatic cost reduction: Average testing costs dropped from $141,864 annually to under $11,000, even while testing frequency increased to daily in some cases.

The Mindset Transformation: From Hope to Certainty

The most powerful insight from the research wasn’t about technology – it was about mindset. Nathan repeatedly emphasized organizations moving from hoping their recovery plans would work to knowing they will.

“We were comparing hope vs. certainty,” he explained. “Certainty is a word you hear me say a lot because that really came out in the customer stories.”

As one global infrastructure director put it: “I wake up every day, check my Cleanroom Recovery report about the previous night’s restore, and know we are protected and can recover. We have eliminated downtime by always being able to recover from cyber events.”

The certainty shines through in being able to test recoverability of more than just one component. Nathan shared, “I went into this thinking about data recovery without thinking about ecosystem recovery. They’re now testing the recoverability of their entire ecosystem.”

Study participants also discussed testing in true chaotic environments. “So much of testing is done in a very calm environment. While any type of true restore is done in a chaotic environment. I heard quite a few stories about how Commvault specifically helped simulate the chaotic environment. So, in the time when it did happen, it wasn’t the first time you went through a high stress recovery,” Nathan shared.

Bonus Insights: AI Acceleration Through Confidence

Nathan shared additional findings from the research that are not called out in the report, including how organizations feel confident to accelerate their AI initiatives because they know they’re protected.

“AI comes with rapid change,” he explained, adding that the customers he interviewed “called out the assurance that no matter what happens, I can get to my minimum viable company somewhat quickly. It gave organizations more confidence in going through the rapid change that AI is injecting into their company.”

This confidence proves critical as organizations grapple with AI governance challenges. Jaimie highlighted: “One of the biggest concerns that most of my customers have with implementing AI now is how are we going to keep it safe, from an ethical standpoint, as well as from outages and a business continuity standpoint. With Commvault integrated with the Microsoft solution, the most complex and extremely large AI workloads are resilient and recoverable. Customers now have the confidence that their data is protected and recoverable with the resilience they need.”

Begin Your Transformation Today

The transformation from hope to certainty in cyber recovery isn’t just possible – it’s happening right now. The only question is: When will your organization make the leap?  Download the complete ESG Economic Validationreport and watch the webinar,Cracking the Code: Recupere-se 99% mais rápido de ataques cibernéticos, to hear from our expert panel. Use these as your blueprint to begin your organization’s transformation.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

The modern, tech-dependent businesses of today may not run entirely on Windows – but nearly every organization relies on it somewSaiba mais no SHIFT 2025. Whether through business applications, identity management, or the countless tools that keep operations moving, Windows remains a critical touchpoint across industries.

This widespread adoption brings with it a unique challenge: It makes Windows solutions the natural target for cyberattackers. The more common the technology, the more determined adversaries are to find vulnerabilities. Especially in an era wSaiba mais no SHIFT 2025 cyberattacks are growing in complexity and sophistication, this poses a monumental threat to digital businesses.

In an blog anterior, exploramos a necessidade de passar de uma defesa reativa para uma proativa. Sabemos que visibilidade e rapidez são essenciais para os resultados da Recovery. Agora, com o Threatwise v8.2, estamos dando o próximo passo.

Ao introduzir sensores de ameaças pré-configurados para o Windows Server 2022 e 2025, esta versão se baseia nos alicerces que já estabelecemos. Ela ajuda você a restaurar mais rapidamente, ao compreender com facilidade o alcance do impacto, e oferece às equipes de TI um sistema de alerta precoce mais robusto para impedir que os ataques se espalhem.

Tecnologia de Engano: O que é e por que é importante?

O Commvault Threatwise leverages cyber deception technology to help redirect attacks and uncover threats. Deception technology plants digital lookalikes across your environment. These decoys mirror true company assets and network activity, yet they serve a very different purpose: to lure attackers into revealing themselves.

Threatwise extends this approach with decoys that are quick to deploy and simple to scale. These lookalikes trick criminals into believing they have gained access to an enterprise’s most critical systems, when in reality, they have pulled the virtual fire alarm.

While invisible to everyday users, the moment a bad actor interacts with a sensor, security teams receive a high-fidelity signal of compromise. Such early alerts help defenders prepare a response before damage escalates.

With v8.2, organizations gain access to preconfigured sensor templates for the latest Windows Server editions. This allows you to help protect your system with faster setups, broader coverage, and greater resilience.

Minimizando o raio de impacto

Every cyberattack carries a blast radius. When it comes to cybersecurity, the blast radius refers to the potential spread and impact of a single security breach or system failure.

For backup administrators, the blast radius translates into the scale of data corruption, downtime, and recovery complexity. The larger the impact, the longer and more expensive the recovery. What’s more, beyond the operational disruption and economic losses, these attacks also can damage company reputation and trust, potentially undoing years of dedicated service.

In our proactive detection series, we discussed how reducing the blast radius requires early detection, rapid isolation, and clean recovery environments. Deception technology aligns with this model. Triggering alerts early in the attack lifecycle can help defenders contain an attack before it cascades across production systems. This early visibility can give responders the needed head start, providing valuable time to preserve clean data and maintain operational continuity.

Superando adversidades: por que os administradores de backup precisam do Threatwise

In our highly competitive business ecosystem wSaiba mais no SHIFT 2025 speed is non-negotiable, backup administrators face a unique set of challenges. Recovery windows are shrinking, applications with exponentially larger data sets, and more and more complex infrastructure, often spanning across hybrid or multi-cloud environments.

In this environment, Commvault’s deception technology can help data administrators thrive in the face of adversity in several ways:

  • The How: Preconfigured decoys mimic application hosts, allowing admins to quickly create lookalikes and multiply them across blanked instances. With Threatwise v8.2, sensor templates for Windows Server 2022 and 2025 deliver coverage for the latest systems.
  • The What: Based on organizational SLAs, Threatwise can highlight which systems to prioritize and help to keep critical company crown jewels safeguarded.
  • The Why: Early high-fidelity signals can reduce uncertainty during an incident with critical threat insights. Backup admins can pinpoint infected applications that require restoration. Further, they can effectively prepare cleanroom environments to validate restore data and processes.

Esses recursos ajudam a proporcionar clareza e confiança aos administradores, mesmo nos momentos de alta pressão de uma emergência de Recovery.

Mais fortes juntos: colaboração e sinergia entre TI e segurança

O Threatwise oferece às empresas as ferramentas para ajudar a proteger seus ativos contra ameaças cibernéticas modernas e ransomware. No entanto, a detecção só é eficaz na medida em que a resposta que se segue também o for.

O Threatwise, como parte do Commvault Cloud, integra-se às principais soluções de SIEM e SOC, permitindo que os alertas circulem entre as operações de TI e de segurança. Essa colaboração ajuda a possibilitar uma coordenação mais rápida, comunicação multifuncional, conscientização organizacional compartilhada e um plano unificado de resposta a incidentes.

Além disso, a verdadeira oportunidade reside em como as operações de backup podem moldar a estratégia de segurança mais ampla ao assumir o papel de inovadoras. Ao assumir esse papel e alinhar-se com a equipe de segurança, os administradores de backup ajudam a mudar o foco da defesa reativa para a resiliência proativa. Testes de rotina dos manuais de resposta e das iniciativas de recuperação reforçam essa sinergia e geram confiança no poder de uma abordagem proativa.

O que isso significa para o futuro da resiliência cibernética

Threatwise v8.2 helps make deception technology simpler to deploy and more effective against ever-evolving threats. By extending coverage to the latest Windows Server editions, it helps organizations stay a step ahead of attackers who seek to exploit vulnerabilities of the most widely used enterprise systems.

Early warning signals are not a luxury for a cyber resilient organization; they are vital for building business continuity by creating rapid recovery options. With deception in place, powered by Threatwise, organizations can face tomorrow’s threats with confidence.

Learn more about Threatwise Saiba mais no SHIFT 2025.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

AI and analytics are driving competitive advantage across every industry. At the heart of this transformation are data lakehouses built on Apache Iceberg, now one of the fastest-growing standards for structured data on object storage such as Amazon S3. From retail and healthcare to finance and tech, Iceberg is powering the pipelines that fuel AI-driven insights.

But while adoption is surging, resilience has not kept pace. Native Iceberg tools weren’t built for long-term protection. They fall short when it comes to compliance, ransomware resilience, and rapid recovery. For businesses, that gap means more than data loss – it can result in regulatory fines, flawed AI models, and costly downtime that undermines innovation.

When Native Tools Fail: A Financial Firm’s Story

Consider a global financial services firm processing billions of trades every day. Every few minutes, trades are written into Iceberg tables. Regulations require this firm to keep a full history of transactions for seven-plus years.

With native Iceberg snapshots, this can quickly become unmanageable. Too many snapshots can create performance bottlenecks, and recovering to an event from just five months ago requires a slow, manual process. In finance, where downtime equals millions of dollars in losses, that’s simply unreasonable.

And the challenge isn’t limited to finance. Any industry running AI and analytics on Iceberg may face the same risks: limited retention, fragile recovery, and exposure to ransomware.

Why Generic S3 Backups Aren’t Enough

Some organizations turn to standard S3 backup tools as a workaround. While these can be air-gapped, they copy data files but don’t preserve the relationships that define an Iceberg table.

That means recovery isn’t a simple restore – it’s a complex, manual “rewiring” process to rebuild the entire table structure. For a financial firm with billions of trades, that translates into extended downtime, higher costs, and potential data loss.

Clumio can eliminate this problem by natively understanding Iceberg, enabling recovery that is fast, accurate, and transactionally consistent.

Um caminho inteligente a seguir: Clumio para Apache Iceberg

Commvault is closing this gap with the industry’s first and only solution to deliver Iceberg-aware, air-gapped cyber resilience: Clumio for Apache Iceberg on AWS.

Here’s what makes it different:

  • Unlimited retention without performance hits – adhere to long-term compliance requirements without slowing down production environments.
  • Air-gapped, immutable protection – designed to defend against ransomware, account compromise, and accidental deletions.
  • Fast, Iceberg-aware recovery – ability to restore to any point in time or named snapshot with full table integrity.
  • Cross-region and cross-account recovery – extend resilience across AWS environments for verifiable disaster recovery.
  • Cost-efficient, incremental backups – enables capturing only changes to minimize costs while scaling with massive workloads.

Leia o anúncioem nosso comunicado à imprensa para obter mais detalhes.

Snapshots nativas x Backups genéricos do S3 x Clumio para Apache Iceberg

Capability Native Iceberg Snapshots Generic S3 Backups Clumio for Apache Iceberg
Retention Limitada; pode causar gargalos de desempenho com um número excessivo de instantâneos Possível a longo prazo, mas apenas no nível do arquivo Ilimitada, econômica e projetada para garantir a conformidade
Air-gapped protection ✘ Lives in same AWS account (lost if table deleted) ✓Can be air-gapped, but not Iceberg-aware ✓Air-gapped, immutable vault for ransomware resilience
Recovery process Manual, especialmente para snapshots mais antigos Manual “rewiring” of table metadata and manifests Recovery rápida, automatizada e compatível com o Iceberg
Data integrity Consistência transacional, mas com responsabilidade pela governança e conformidade Sem compreensão dos metadados do Iceberg; restaurações inconsistentes Restaurações com consistência transacional e fidelidade total
Enterprise scale Impraticável para retenção de longo prazo; altos custos de armazenamento Frágil e propenso a erros em grande escala Comprovado em escala de petabytes com bilhões de objetos


Por que isso é importante para sua empresa

Clumio doesn’t just protect files – it can safeguard your AI and analytics investments so they can deliver results. This new capability helps enterprises:

  • Accelerate AI innovation with confidence by protecting the data fueling critical pipelines.
  • Avoid compliance penalties with unlimited, cost-effective snapshot retention.
  • Recover in minutes, not days, thanks to Iceberg-aware automation that is designed to eliminate brittle, manual processes.
  • Strengthen cyber resilience with actual air-gapped protection against ransomware and insider threats.

Construindo resiliência para o futuro

As data lakehouses become the backbone of digital business, resilience shouldn’t be an afterthought. With Clumio for Apache Iceberg on AWS, enterprises finally have a solution that matches the scale, speed, and criticality of their AI and analytics workloads.

Because in the end, it’s not just about protecting data. It’s about protecting your business.

Saiba como proteger as tabelas Iceberggerenciadas pelo AWS Glue e Amazon S3 Tables com resiliência compatível com Iceberg. Quer saber mais?Solicite uma demonstraçãoe inscreva-se hoje mesmo para umteste gratuito no AWS Marketplace today.


More related posts


Clumio

Read more about Clumio

Ransomware attacks have become inevitable in today’s threat landscape, emerging as a major concern for all businesses. In fact, ransomware incidents have surged dramatically in the first half of 2025, resulting in a 49% increase compared to the same period in 2024.

Now, as organizations face even more sophisticated threats designed to encrypt data, paralyze operations, and exploit recovery processes, these numbers show no signs of slowing down.

The stakes are rising, and it’s increasingly evident that when disaster strikes, simply having backup isn’t enough. Organizations can’t adopt a reactive security posture and hope to function successfully. You need immutable data, intelligent detection of threats, clean recovery and testing of recovery plans, and 24/7 protection.

Commvault delivers a deeply integrated, multi-layered ransomware defense framework that prioritizes security, speed, and confidence. By combining state-of-the-art threat detection, isolation, and recovery mechanisms with partner intelligence, Commvault helps enable cyber resilience.

This article explores four components of Commvault’s ransomware defense strategy: data immutability, real-time threat scanning, validated recovery, and intelligent recovery automation. Together, these capabilities form a complete and dependable response to one of the most persistent challenges plaguing modern IT teams.

Data Immutability: The First Line of Defense

Data immutability is integral to any successful ransomware defense strategy. In a world wSaiba mais no SHIFT 2025 ransomware increasingly targets not just production systems but backup infrastructure itself, immutability is a critical safeguard. Commvault leverages data immutability with an array of capabilities designed to help keep your data tamper-proof. This is achieved through immutable storage, layered access controls, and enforced authorization protocols.

Here’s a closer look at Commvault’s data immutabilitycapabilities:

  • Immutable storage: Commvault implements a multi-layered approach to immutability. It combines its own software-level controls with hardware-enforced and cloud-based WORM (write-once, read-many) technologies. Retention Lock (formerly WORM Copy) prevents premature deletion or aging of backups, even by administrators, and protects against actions like removing storage policies or deleting storage libraries. This is a significant form of defense against rogue administrators or malicious attackers.
    Similarly, for hardware-enforced immutability, Commvault integrates with storage platforms that support the industry-standard S3 Object Lock API. S3 Object Lock operates in two primary modes: governance and compliance. While governance mode helps protect against accidental deletions and retains administrative flexibility, it is primarily suited for internal controls. The stricter compliance mode, on the other hand, enforces unbreakable retention periods and is designed to meet stringent regulatory requirements such as SEC Rule 17a-4, FINRA, and HIPAA 12.
    When Commvault writes backup data to an Object Lock–enabled target, such as an AWS S3 bucket or Zadara object store, it sets the Object-Lock-Retain-Until-Date metadata timestamp. Any API call to modify or delete the object before that date is rejected by the storage system, regardless of user permissions. Commvault also adds a default 7-day grace period to the WORM lock retention period configured in the software.
    Finally, on HyperScale X, Commvault’s scale-out integrated appliance, Commvault delivers immutability end-to-end using Retention Lock, a hardened OS, and an immutable file system. This integrated stack is certified for SEC 17a compliance, making it a powerful all-in-one solution for immutable storage.
  • Air Gap Protect: Air-gapped protection is delivered through a Commvault-managed, logically isolated backup environment that encrypts data, separates it from the production network, and eliminates egress charges. This feature is enabled for Commvault SaaS customers by default, helping data stay protected even if production systems become compromised.
  • Zero-trust enforcement: Commvault applies strict zero-trust principles to backup infrastructure through role-based access control, multi-factor authentication, and privileged access management. These layers limit exposure and enforce least-privilege access, reducing the impact of compromised credentials.
  • Multi-Person Authorization: To prevent malicious or accidental changes to protection policies, Commvault enforces quorum-based approvals for sensitive operations. This helps prevent a single administrator from disabling or deleting protected data without oversight.

Real-Time Threat Intelligence: Proactive Detection and Containment

Commvault’s Threat Scan suite is a cornerstone of its ransomware defense. Malicious files and programs can make their way into backups and stay hidden, waiting for the perfect opportunity to strike. So, Commvault’s real-time threat intelligence is designed to identify threats at every stage: during backup, after backup, and before restore.

Commvault is also the only cyber resilience vendor with built-in deception capabilities such as Threatwise sensors and canary files. These tools can trigger alerts while a threat actor is performing reconnaissance and before ransomware even reaches backup data.

Real-time threat detection is brought to life with these powerful features:

  • Inline, pre-, and post-backup scanning: While Threat Scan is a post-backup activity, Commvault actively monitors for ransomware indicators during inline and pre-backup stages. This includes looking for changes in attributes such as MIME type, backup size, and specific extension growth that mirror ransomware activity.
    With this comprehensive approach, whether data is in transit, newly stored, or being restored, it is continuously inspected for hidden or dormant threats. This allows early detection and helps eliminate blind spots.
  • Signature-based and AI/ML detection: Commvault leverages Avira’s anti-malware SDK, a trusted OEM engine used widely across the industry, to massively enhance its defensive capabilities. This engine includes several detection layers that combine to provide a comprehensive security approach.
    Signature-based scanning compares file hashes against Avira’s vast malware signature database. Updates occur every 24 hours to keep the engine current with emerging threats. This database is automatically updated every 24 hours via a secure connection to Avira’s update servers, providing protection against the latest cataloged threats.
    Similarly, for malware that is not yet in the signature database, the Avira engine uses heuristics to analyze the code structure, behavior, and characteristics of a file. This allows it to identify variants of known malware families and other suspicious code, even without an exact signature match.
    Finally, Machine Learning (MicroVision™), Avira’s local ML model, evaluates a broad set of code attributes and anomalies to identify previously unseen threats. It is especially effective against zero-day malware that lacks a known signature but shows signs of malicious behavior.
  • Entropy and MIME Mismatch Analysis: Commvault uses encryption detection models, consisting of multiple statistical features, to identify encrypted or disguised files. One such feature is entropy, which measures the level of randomness in data at the binary level. High entropy can indicate ransomware encryption, but it is just one of several properties used in Commvault’s encryption detection model.
    In parallel, MIME mismatch detection flags files wSaiba mais no SHIFT 2025 the content does not match the expected file type, such as a script disguised as a PDF. These techniques help uncover dormant threats that might otherwise go unnoticed.
  • Anomaly detection: Commvault continuously monitors for behavioral deviations. Unusual spikes in backup volume or changes in data patterns are treated as warning signs. Once these anomalies are encountered, they can be promptly investigated, helping lead to early containment.

Comprehensive Recovery: Isolated, Validated, and Automated

As ransomware grows in complexity and speed, clean recovery is imperative. With ransomware, restoring the wrong version can cause re-infection, operational downtime, or compliance failures. And it can be detrimental to company trust, confidence, and long-term success. Commvault addresses these risks with a set of validated recovery options that not only help restore clean data but also help verify its safety before it ever touches production systems.

Commvault’s Cleanroom creates a secure, isolated recovery environment for testing and validating backup data before reintroduction. This setup is ideal for running malware scans without risking spread to production. What’s more, cleanrooms are provisioned on-demand in the cloud, avoiding the need for dedicated infrastructure.

Within the cleanroom, Commvault supports a wide range of workloads, including virtual machines, file systems, and Active Directory. This flexibility allows teams to simulate live environments and fully verify operational readiness.

Cleanroom enhances Commvault’s ransomware defense:

  • Automated recovery workflows: Commvault automates the entire recovery lifecycle, from identifying clean points to final workload restoration. These workflows help reduce manual effort, provide consistency, and help teams meet aggressive recovery objectives.
  • Pave and Repave: For systems compromised at the OS level, Commvault supports pave and repave capabilities. This approach restores machines using clean operating system images, then overlays customer data from backup. It results in a fully rebuilt system free from OS-level malware or tampering.
  • Bad file indexing: During scanning, Commvault marks any infected or suspicious file versions as “bad.” These tags are automatically referenced during recovery, enabling the platform to select clean restore points without manual review.

Auto Recovery and Operational Intelligence: Fast, Orchestrated, and Scalable

Recovering clean may be the most essential aspect, but recovering fast is also a priority. Commvault’s auto recovery capabilities allow organizations to restore systems at scale with speed, confidence, and minimal manual effort. These capabilities combine intelligent orchestration, integrated scanning, and real-time visibility to drive recovery resilience.

Here’s a deeper analysis of Commvault’s automated operational intelligence solutions:

  • Auto recovery orchestration: Commvault automatically detects the most recent clean recovery point and initiates restore workflows based on pre-defined policies. These orchestrated processes eliminate guesswork and help reduce the time it takes to bring systems back online after an attack. The full Commvault auto recovery process involves automated steps detailed Saiba mais no SHIFT 2025.
  • Threat Scan integration: Recovered workloads are scanned as part of the recovery workflow before they return to production. This process enhances the confidence of restored data by helping keep it free from hidden malware or residual threats.
  • Recovery validation reports: Every recovery operation produces a detailed report that outlines scan outcomes, flagged anomalies, and any corrective actions taken. These reports give security teams invaluable visibility into what was recovered and why.
  • Security IQ dashboard: The Security IQ dashboard provides real-time insight into ransomware risk, data exposure, and overall recovery readiness. It helps administrators identify critical weak spots, track improvements, and act on changes as needed.

Ransomware Resilience When It Matters Most

Commvault’s ransomware defense architecture is an intelligent, multi-layered ecosystem. From the moment data is backed up to the second it’s restored, every layer is protected, validated, and recoverable. With a comprehensive design that encompasses every aspect of ransomware defense, Commvault gives your businesses confidence, trust, and resilience.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

A resiliência está no centro de tudo o que fazemos aqui na Commvault.Conforme compartilhamos earlier this year, we are proud to partner with Warrior Canine Connection (WCC) in its mission to create resilience and strength within the veteran community.

This is a cause close to our hearts and foundational to our VALOR Employee Group’s mission to honor our veterans and increase veteran recruitment and retention, while bolstering our community outreach and building a military-friendly culture that is inclusive of all.

Over the past couple of months, we’ve been thrilled to have members of WCC, including some furry friends, join us at customer and partner events across the United States. Heidi Pius on our Sales Engineering team has witnessed the pawsitive effect these service animals have had on everyone they encounter.

“Commvault’s partnership with WCC highlights the powerful combination of innovation and resilience in supporting veterans,” Heidi said. “This partnership helps both of us further veteran resilience through the healing power of service animals.”

Here are some highlights from our events throughout the summer:

Commvault’s Annual Public Sector Partner Day – Stone Tower Winery in Leesburg, Virgina.

WCC were the capstone presenter at our Annual Public Sector Partner Day and showcased how the organization furthers veteran resilience and helps military heroes reconnect with life, their families, and their communities through the healing power of service animals.


AWS Summit – Washington DC

WCC added a special touch to our booth at the AWS Summit in Washington, D.C. When the service dogs weren’t present in the booth, we had people asking about them and when they would return to the booth – we even ran out of mission cards during the event.

Having WCC as part of our booth experience is not only a great marketing tool but makes the booth experience relatable on another level – adding a human element that makes it real. The handlers were excellent in telling the story of resilience from both sides.

Having an impact is fundamental to our values and our culture. We’re committed to our partnership with WCC to raise awareness and help veterans receive the support and care they deserve.

To learn more about what it’s like to work at Commvault, visit our página de Carreiras.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

It’s no surprise that identity infrastructure, particularly Active Directory (AD), is a primary target for attackers. According to Gartner’s Market Guide for Identity Governance and Administration, more than 90% of Global 2000 organizations rely on AD for core identity and access management.

Yet, despite its critical role as the central nervous system of enterprise IT, AD security is often neglected, leaving it vulnerable to sophisticated attacks that can bring an entire organization to its knees.

The consequences of a compromised AD can be catastrophic, including widespread operational disruption, significant data loss, and a complete loss of trust. When attackers gain control of AD, they hold the keys to the kingdom – and they are able to move laterally, escalate privileges, and deploy ransomware with devastating efficiency.

Best Practices for Future-Proof AD Resilience

Achieving true AD resilience requires a strategic blend of proactive defence, meticulous planning, and robust recovery capabilities. This is not merely about having backups; it’s about cultivating a resilience-first mindset and implementing a multi-faceted strategy.

1. AD forest recovery: Planning for the worst-case scenario

A complete forest recovery remains the ultimate test of AD resilience. This involves the ability to restore the entire AD environment to a known-good state after catastrophic corruption or compromise.

  • Maintain regular, offline backups of all domain controllers.
  • Document and periodically validate the forest recovery process through tabletop exercises and simulations.
  • Leverage tools like Microsoft’s AD Forest Recovery Guide or third-party automated solutions that reduce recovery time.
  • Recovery images should remain secure, offline, and immutable.

Without these preparations, organizations risk prolonged outages, as recovering AD manually without a plan can be highly complex, error-prone, and time-consuming.

2. Entra ID recovery: Protecting and recovering break-glass accounts

Beyond restoring the forest, organizations should build resilience through Entra ID recovery – protecting and rapidly recovering break-glass accounts used in emergencies.

  • Maintain dedicated, highly secure and monitored administrative accounts that are disconnected from regular directory services (Tier-0 accounts).
  • Store credentials for these accounts in secure vaults (e.g., CyberArk, Azure Key Vault) with strict access controls.
  • Regularly rotate credentials and audit access logs.
  • Simulate account lockout or compromise scenarios to validate the recovery process.
  • Entra IDs have to be excluded from regular AD sync processes with cloud environments to reduce exposure.

These accounts should be protected as crown jewels since their compromise could derail recovery efforts entirely.

3. Proactive hardening and monitoring

This forms the bedrock of any effective AD security program. Organizations should implement a tiered access model to enforce the principle of least privilege, so that users and administrators only have access to the resources absolutely necessary for their roles.

Regularly auditing for misconfigurations, such as weak password policies or excessive permissions, is crucial. Furthermore, deploying advanced threat detection and response solutions provides real-time visibility into suspicious activities, helping enable security teams to identify and neutralize threats before they can escalate.

4. Immutable backup and recovery readiness

Backups should be stored in an immutable, air-gapped location to protect against encryption or deletion by ransomware. This provides a clean recovery point.

Recovery readiness goes a step further by regularly validating the integrity and recoverability of these backups. By automatically testing the recovery process in an isolated environment, organizations can confirm that their backups are not only safe but also fully functional, reducing the risk of a failed recovery during a real crisis.

A Unified Front: The HCLTech and Commvault Joint Solution

HCLTech and Commvault have forged a powerful partnership to deliver a comprehensive, end-to-end identity resilience solution that automates forest-level recovery for AD, helping reduce downtime from days or weeks to hours. With Commvault and HCLTech, customers can expect:

  • Knowledge and strategic guidance from the experts at HCLTech to design, implement, and sustain a resilient AD environment aligned with zero-trust principles.
  • Proactive hardening, regular testing, and continuous monitoring.
  • A comprehensive, tailored recovery plan that includes automated forest-level recovery enabled by the industry-leading capabilities of Commvault Cloud.
  • Unified protection of hybrid identity systems (AD + Entra ID) that simplifies operations and reduces tool sprawl, enabling consistent security across environments.

Together, HCLTech and Commvault provide a truly holistic approach to identity security and business continuity. By combining Commvault’s rapid, automated recovery technology with HCLTech’s strategic, security-first services, organizations are equipped not just to survive an AD-related disaster, but to emerge stronger.

This unified front helps keep your most critical identity infrastructure ready for the worst-case scenario, delivering a rapid, clean, and reliable recovery when it matters most. Don’t wait for a crisis to test your defenses. The time to act is now. Take the first step toward true AD resilience and help your organization prepare for any eventuality.

To learn more and demo the solution, visit the página da solução do Active Directory.


More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

At Commvault, we believe that the well-being of our employees is fundamental to our success as a company. That’s why we’re committed to providing a comprehensive approach to wellness that addresses the various aspects of our Vaulters’ total wellbeing.

Recognizing that wellness encompasses more than just physical health, we’ve developed a multi-faceted approach that includes medical, financial, and physical wellness initiatives.

Apresentando uma plataforma abrangente de bem-estar

We’re thrilled to have recently launched our new wellness platform, CommWell. This innovative platform consolidates various wellness-related benefits into a single, user-friendly interface, making it easier for our employees to access the resources they need to maintain and improve their health. The platform offers a range of features, including:

  • Avaliações de saúde para identificar áreas de melhoria.
  • Planos de bem-estar personalizados, adaptados às necessidades individuais.
  • Ferramentas interativas para monitorar o progresso e incentivar hábitos saudáveis.

Ao simplificar o gerenciamento dos benefícios de bem-estar, nós nos esforçamos para oferecer aos nossos funcionários, independentemente de sua localização, acesso ao suporte de que precisam.

Apoio à saúde mental com o Spring Health

We understand that mental health is just as important as physical health. That’s why we’ve partnered with Spring Health, a global provider of mental health support services. Its comprehensive platform offers more than just traditional EAP services, providing:

  • 6 sessões de aconselhamento para tratar de problemas específicos de saúde mental.
  • 6 sessões de treinamento para apoiar o crescimento pessoal e profissional.
  • Acesso a um centro de cursos e recursos para desenvolvimento contínuo.

Capacitando o bem-estar financeiro com o Origin

O estresse financeiro pode ter um impacto significativo no bem-estar geral. Para ajudar a aliviar esse fardo, oferecemos os serviços financeiros da Origin, proporcionando aos funcionários acesso a consultores financeiros e planejadores financeiros certificados gratuitamente. A plataforma da Origin oferece orientação especializada sobre diversos temas, incluindo:

  • Estratégias e planejamento tributário.
  • Otimização de prêmios de ações e benefícios do empregador.
  • Orçamento e gerenciamento de fluxo de caixa.
  • Seleção de investimentos e planejamento de aposentadoria.
  • Análise de riscos e planejamento de seguros.

Additionally, Origin’s AI Budget Builder (currently available in the U.S. and soon to be expanded globally) provides a cutting-edge tool for managing finances.

Promovendo o bem-estar físico com o Wellhub

Exercícios regulares, nutrição saudável e atenção plena são componentes essenciais do bem-estar geral. Para apoiar esses aspectos, oferecemos acesso ao Wellhub, um aplicativo digital que oferece uma variedade de recursos de condicionamento físico, nutrição e atenção plena. Em locais selecionados, os funcionários também podem participar de academias em níveis diferenciados, facilitando a incorporação da atividade física em sua rotina diária.

Uma cultura de cuidado e suporte

At Commvault, we’re committed to creating a culture that prioritizes employee wellness and encourages our employees to value their wellbeing. By providing a comprehensive range of wellness initiatives, we’re empowering our teams to deliver for themselves first, which in turn allows them to thrive both personally and professionally.

To learn more about what it’s like to work at Commvault, click Saiba mais no SHIFT 2025.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

The Australian Security of Critical Infrastructure Act 2018 (SOCI) is the cornerstone of the government’s strategy to manage risks to critical infrastructure. Its objectives are to confirm operators of essential infrastructure assets take appropriate security measures and to give government the information and powers to respond to threats.

Originally targeting just four sectors (electricity, gas, water, and ports), SOCI has since been expanded to cover 11 sectors across the economy. The act aims to keep critical infrastructure assets and services across these 11 sectors protected and resilient against disruptions to Australia’s security, economy, and society.

To achieve this, the Act imposes obligations on critical-asset owners, via the form of Positive Security Obligations (PSOs)Enhanced Cyber Security Obligations (ECSOs), and Government Assistance Measures.

For example, responsible entities must register asset details and maybe required to report cyber incidents to the Australian Cyber Security Centre (ACSC) and maintain a formal risk management program known as a Critical Infrastructure Risk Management Program (CIRMP). Assets deemedSystems of National Significance could face even stricter requirements, including, for example, mandatory incident response plans, cyber exercises, and vulnerability assessments. SOCI essentially codifies what was once considered industry best practice into enforceable law.

Dois campos de impacto: Setores antigos vs. novos entrantes

Os setores originalmente regulamentados provavelmente veem a SOCI como uma extensão das estruturas existentes. Durante décadas, os setores de energia e serviços públicos operaram sob rigorosos padrões de confiabilidade e segurança (como os códigos NEM ou as leis de segurança da água), de modo que a formalização dessas práticas na SOCI pode parecer uma continuação da governança existente.

Em contrapartida, as organizações nos setores incluídos mais recentemente, como comunicações, armazenamento e processamento de dados, saúde, ensino superior e transporte, estão enfrentando um novo cenário regulatório. Esses setores muitas vezes não contam com um histórico de regulamentação de infraestrutura, o que significa que a conformidade com o SOCI exige a criação de muitos processos a partir do zero. Isso inclui a criação de registros de ativos, a elaboração de CIRMPs, a implementação de controles e o treinamento de equipes nos procedimentos de notificação de incidentes.

Por exemplo, uma rede universitária ou hospitalar pode agora ser classificada como operadora de infraestrutura crítica, o que exige que ela identifique os ativos cobertos, avalie as dependências e implemente um CIRMP em conformidade.

This often involves building formal security governance from the ground up – aligning to frameworks such as the ASD Essential Eight, ISO 27001, or the NIST Cybersecurity Framework – and establishing mechanisms for timely incident detection, response, and reporting to the ACSC.

By contrast, operators in traditionally regulated sectors may already have mature risk programs in place and can adapt existing controls to meet SOCI’s requirements. Regardless of sector, all organisations must now integrate cyber risk management into core business processes, not treat it as a parallel or isolated activity.

OT e o desafio da convergência de TI

A significant challenge presented by SOCI lies in securing Operational Technology (OT) environments: the industrial control systems that underpin many critical assets. OT brings its own set of risks.

Muitos dispositivos nunca foram projetados com a segurança cibernética em mente. Eles geralmente executam sistemas operacionais ou firmware desatualizados que não podem ser facilmente corrigidos e usam protocolos proprietários ou legados, como Modbus, DNP3 ou Profibus, que não possuem autenticação e criptografia básicas.

Ao mesmo tempo, a convergência das redes de TI e OT expandiu a superfície de ataque. Ambientes anteriormente isolados agora estão cada vez mais conectados aos sistemas de TI corporativos e à Internet para permitir o monitoramento remoto, a análise e a automação. Isso cria novos caminhos para que os invasores se movimentem lateralmente entre os ambientes e introduz o risco de interrupção operacional devido a ataques cibernéticos.

Os operadores industriais precisam encontrar um equilíbrio entre a disponibilidade do sistema e a proteção cibernética. Colocar os sistemas off-line para atualizações ou segmentação pode interferir nas operações, mas deixá-los expostos aumenta o risco.

A SOCI incentiva as organizações a adotarem estratégias específicas para OT. Essas estratégias podem incluir segmentação rigorosa da rede, acesso com privilégios mínimos, monitoramento fora de banda e projetos à prova de falhas para proteger esses ambientes.

Provedores de serviços de dados e deveres de notificação

One of the lesser-discussed but critically important elements of SOCI is the responsibility to notify data service providers. If a third party stores or processes business-critical data related to your regulated asset, you are obligated to inform them that SOCI applies. This verifies that your service providers understand their role in protecting critical data and are prepared to support you during an incident or audit.

In addition, incident notification is a central requirement of SOCI. A cyber security incident that has a significant or relevant impact on your essential services must be reported to the ACSC within strict timeframes. If the impact is significant, notification must occur within 12 hours. For relevant but lower-severity incidents, notification is required within 72 hours.

Essa não é uma atividade voluntária ou de melhor esforço. É uma obrigação legal. A comunicação oportuna dá à ACSC visibilidade das ameaças aos sistemas nacionais, permitindo que ela coordene respostas oportunas e eficazes. Ela também reforça o princípio de que a proteção de infraestruturas críticas é uma responsabilidade compartilhada entre o setor e o governo.

Além da prevenção: O verdadeiro significado de resiliência

Many organisations still interpret resilience as the ability to block or prevent threats. But true resilience goes beyond prevention. It is the ability to absorb shocks, recover quickly and continue operating, even under adverse conditions. SOCI pushes organisations to embrace this broader definition.

Resiliência significa ter planos de recuperação testados, backups off-line confiáveis, sistemas redundantes e um manual para retornar ao serviço durante ou após um incidente. Também significa aprimoramento contínuo, aprendendo com cada evento, adaptando as defesas e fechando as lacunas antes do próximo ataque.

This is especially important given recent trends.Reports from the Australian Signals Directorate(ASD) and other government bodies show that cyber incidents impacting sectors like water, energy, and transport are increasing.

Até mesmo eventos relativamente pequenos podem causar efeitos em cascata em sistemas interdependentes, afetando cadeias de suprimentos, segurança pública e serviços essenciais. Essas tendências destacam a urgência de uma abordagem focada na recuperação.

Os CISOs devem liderar a tarefa de tornar a resiliência cibernética mais do que uma caixa de seleção. Isso significa tratar a resiliência como um recurso dinâmico, de ponta a ponta, que envolve pessoas, processos e tecnologia trabalhando em conjunto.

Uma mudança regulatória com vantagens estratégicas

SOCI has represented a significant shift in Australia’s approach to cyber regulation. It moves beyond fragmented, voluntary approaches and creates a cohesive national framework for protecting critical infrastructure. While it certainly has introduced new complexity, reporting burdens, and compliance costs, it also provides an opportunity for organisations to elevate their security maturity and embed resilience at the core of their operations.

Rather than viewing SOCI as merely a compliance task, forward-thinking CISOs can treat it as a strategic catalyst. It provides board-level backing for investment, formalises risk practices, and improves alignment between business and security. The inclusion of government assistance measures and threat-sharing mechanisms further positions SOCI as a collaborative tool, not just a mandate.

As threats evolve and digital infrastructure becomes more embedded in national life, resilience must be the priority. SOCI sets the stage. Now it’s up to us to act.

Leia mais sobre suas obrigações emUm guia para a Lei SOCI.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

The Security Standard That’s Reshaping Business Strategy

While most organizations view FedRAMP High as a compliance hurdle – a necessary evil for selling to federal agencies – forward-thinking enterprises are discovering something remarkable: This rigorous security framework isn’t just about meeting government requirements.

FedRAMP High serves as a smart security blueprint for the private sector, and we’re seeing this translate into something even more powerful – a strategic foundation for building the kind of cyber resilience that transforms businesses from the inside out.

The bottom line: Organizations implementing FedRAMP High controls alongside enterprise data resilience strategies aren’t just checking compliance boxes – they’re gaining massive operational efficiencies, cost savings, and competitive advantages that extend far beyond government contracts.

Por que o FedRAMP High e o Zero Trust são inseparáveis

Here’s what’s resonating across the federal sector and bleeding into commercial enterprises: FedRAMP High controls and zero-trust architecture aren’t separate initiatives– they’re interdependent foundations that enable cyber resilience.

Think about it: How can any organization – federal agency or Fortune 500 company – achieve genuine zero trust without the stringent controls that FedRAMP High demands? FedRAMP High requires cloud providers to meet over 400 security controls, creating the robust foundation that zero-trust principles require to function effectively.

O governo federal reconheceu essa interdependência, com soluções de confiança zero agora obtendo a autorização FedRAMP High, provando que essas estruturas funcionam melhor quando implementadas em conjunto, e não como prioridades concorrentes.

A vantagem da resiliência de dados: Da segurança ao valor comercial

When organizations implement FedRAMP High controls with an enterprise approach to data resilience – encompassing both protection and management – something powerful happens: They simultaneously enable cyber resilience for their organization’s most critical asset – data.

Essa abordagem oferece valor transformacional em três dimensões críticas:

1. People: Consolidation and Cost Efficiency

Em vez de gerenciar várias soluções pontuais e treinar a equipe no uso de sistemas distintos, as organizações optam por consolidar tudo em uma única plataforma abrangente de gerenciamento de dados. O resultado? Custos com pessoal reduzidos e operações simplificadas, já que as equipes podem se concentrar em iniciativas estratégicas, em vez de gerenciar conjuntos de ferramentas complexos e fragmentados.

2. Process: Automation and AI-Driven Viability

FedRAMP High’s rigorous controls, when paired with modern data resilience platforms, enable organizations to automate critical processes and integrate AI capabilities from a position of strength. This automation helps maintain minimum viable operations during disruptions and maintain the highest security standards.

3. Technology: The Foundation for Modernization

High-security compliance using the right architecture and technology doesn’t just help build cyber resilience – it creates enormous operational efficiencies that become the basis for modernization and competitive advantage.

Impacto no mundo real: Eficiência governamental em ação

This isn’t theoretical – organizations are already seeing these benefits. Government agencies are recognizing solutions that meet FedRAMP High requirements while delivering the cost efficiency of SaaS, with enterprise approaches eliminating redundant legacy software tools and enabling significant operational savings.

This isn’t just a government success story. It’s a preview of what commercial enterprises can achieve when they stop viewing FedRAMP High as a burden and start seeing it as a strategic advantage.

O despertar do setor privado

Private sector organizations are increasingly recognizing that FedRAMP compliance offers high trust and oversight, enhances security, and provides a competitive edge. Companies in highly regulated industries – finance, healthcare, insurance, and defense contractors – are discovering that FedRAMP-compliant vendors often carry over lessons learned in their FedRAMP environments to their commercial environments, resulting in improved security postures, streamlined compliance efforts, and enhanced operational efficiency.

The smart money isn’t waiting for regulatory mandates. Many companies intentionally seek out FedRAMP Authorized cloud providers for their services even when they aren’t governmental agencies, specifically because they’re aware that FedRAMP is a high standard and that any cloud service provider willing to go through the work to adhere to it takes security seriously.

Três imperativos estratégicos para as empresas modernas

1. Treat FedRAMP High as a business accelerator, not a compliance tax.

Organizations that view FedRAMP High controls as the foundation for a comprehensive data resilience strategy gain operational efficiencies that more than offset implementation costs. The framework’s rigorous requirements force organizations to eliminate redundancies, consolidate systems, and optimize processes.

2. Implement data resilience and zero trust as integrated systems.

A arquitetura de confiança zero verifica o contexto disponível no momento do acesso, incluindo informações estáticas do usuário e informações dinâmicas, como geolocalização e credenciais, a sensibilidade dos dados e dos recursos, anomalias de acesso e se a solicitação é permitida com base nas regras de negócios. Quando essa abordagem é aplicada à resiliência de dados corporativos, as organizações ganham visibilidade e controle sobre seus ativos mais valiosos.

3. Choose technology partners with proven FedRAMP High capabilities.

A escolha de um fornecedor de SaaS em conformidade com o FedRAMP pode agilizar significativamente o processo de aquisição, ao oferecer uma lista de fornecedores pré-aprovados que já atendem a elevados padrões de segurança, economizando tempo, reduzindo riscos e simplificando o processo de tomada de decisão.

A realidade competitiva: Segurança como vantagem estratégica

The most successful organizations of the next decade won’t be those that treat security as a cost center or compliance checkbox. They’ll be those that recognize FedRAMP High controls as the foundation for building truly resilient, efficient, and competitive operations.

The security and regulatory compliance of cloud services are paramount. Organizations that master this intersection of security, compliance, and operational efficiency aren’t just protecting themselves – they’re positioning themselves to win in an increasingly complex and dangerous digital landscape.

O caminho a seguir: Da conformidade à vantagem competitiva

Atualmente, as organizações que implementam estratégias de resiliência de dados corporativos com controles FedRAMP High estão descobrindo algo notável: As mesmas estruturas que ajudam a proteger contra ameaças cibernéticas também impulsionam a excelência operacional, a eficiência de custos e a diferenciação competitiva. Sua organização pode escolher entre implementar os padrões do FedRAMP High estrategicamente para obter o máximo de valor comercial ou de forma reativa, como uma reflexão tardia sobre a conformidade.

The epiphany is clear: FedRAMP High isn’t just a security program – it’s a blueprint for building the kind of resilient, efficient, and competitive organization that thrives in our digital-first world.

Ready to transform your data resilience strategy? Learn how Commvault’s enterprise approach to data protection and management can help your organization achieve FedRAMP Highcompliance while driving operational excellence and competitive advantage.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

When someone suffers a debilitating injury, the first thing they want to know is how soon they’ll be back on their feet. Following a cyberattack, a healthcare company’s IT team faces the same question, but with added urgency.

Every minute of downtime poses a critical risk to your organization’s sensitive data, reputation, and patients. What will your answer be?

Em um post recente no blog,Rx para ameaças cibernéticas, discutimos a importância para as organizações de saúde de ter umaestratégia de recuperação mínima viável (MVR) – a business-first approach to restore the most critical services and functions for your core operations.

By prioritizing what matters most, you can recover more quickly, efficiently, and reliably. That’s especially important when lives are on the line.

But having a strategy is only the beginning. To protect your patients and your business, you also have to implement it effectively. That’s why Commvault offers a complimentary Minimum Viability Self-Assessment to help determine how well you’re prepared to resume core operations following a disaster, how you compare with peer organizations, and what you can do to improve your MVR capability. 

Do You Know Where to Begin?

According to a recent GigaOm report, “Recuperação mínima viável: Fechando a lacuna de recuperação,” 54% of organizations lack confidence in their own recovery plans. The Commvault Minimum Viability Self-Assessment can help you understand your readiness across the analyst firm’s three pillars of a successful MVR implementation:

  • Priorização crítica para os negócios
  • Resposta técnica mensurável
  • Prontidão de recuperação organizacional

The first pillar focuses on identifying your most critical functions and mapping their technical dependencies. By setting priorities before an attack, you can move more quickly and effectively in an emergency. Your Minimum Viability Self-Assessment will help you determine how well you’ve laid this foundation and where additional clarity and alignment might be needed.

How Will You Proceed?

Once you’ve mapped out your MVR strategy, the next step is to confirm that you are prepared to execute it effectively. Your technical response will depend on secure backups for critical systems and data, protection for the systems used for recovery, accurate threat detection and identification, clean infrastructure within which to rebuild systems, and other capabilities.

Your Minimum Viability Self-Assessment will help you understand whether you have the technical and organizational capability to not only stop the current attack, but also recover compromised data, rebuild damaged systems, and prevent similar attacks in the future. 

Is Your Organization Ready?

O terceiro pilar do modelo GigaOm concentra-se na prontidão para a recuperação contínua. Como as empresas do setor de saúdeestão entre os alvos mais frequentes for cybercriminals, it would be reasonable to assume that you’ll be attacked at some point and prepare accordingly.

Your Minimum Viability Self-Assessment is designed to address key elements of organizational readiness, from well-defined recovery roles, responsibilities, and procedures to clear SLAs for critical workloads. You’ll also learn whether your testing practices are sufficient to keep your plan up to date and your team ready for anything.

Your Lab Results Are Waiting …

At the end of your Minimum Viability Self-Assessment, you’ll receive a detailed report analyzing your recovery readiness across key elements of minimum viability, a high-level overview comparing your MVR strategy to your peers, and actionable recommendations to speed your response to the next disaster.

Don’t wait until you’re under attack to discover how well you’re prepared to recover. Comece agora sua autoavaliação de viabilidade mínimapara permitir o atendimento ininterrupto de seus pacientes e a resiliência de seus negócios.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements