Skip to content

Puntos Clave

  • La ingeniería social a través del servicio de asistencia técnica se ha convertido en uno de los principales puntos de entrada, ya que los ataques de «vishing» (phishing por voz) están aumentando rápidamente y provocan el robo de credenciales.
  • Las identidades no humanas, como las cuentas de servicio y los tokens, son un importante punto ciego en materia de seguridad; a menudo no se gestionan y se aprovechan mucho para el movimiento lateral.
  • Active Directory (AD) es un objetivo muy atractivo debido a su control centralizado y a las posibles configuraciones erróneas.
  • La prevención por sí sola no basta; las organizaciones necesitan sistemas sólidos de detección y una capacidad de recuperación rápida para limitar los daños.
  • Immediate operational actions – like auditing accounts and correlating help desk activity with identity changes – can significantly reduce risk.

AD sigue siendo uno de los principales objetivos de los atacantes porque es el núcleo de la identidad corporativa.Estudios recientes muestran queel 67 % de los incidentes implican ahora una violación de la identidad, with attackers going after critical systems like AD within hours of initial access.Once compromised, recovery can take days or weeks – causing significant business disruption.
The question worth asking isn’t whether AD is a target.It’s how attackers get taquí – and why the path is so much shorter than security teams might expect.

3 pasos para llegar a un acuerdo total

Grupos de ciberdelincuentes como ShinyHunters y Scattered Spider han convertido la ingeniería social en una operación a gran escala.Voice phishing – vishing – jumped 449% in 2025.Se recluta a personas para realizar las llamadas, se les proporciona un guion yse les paga hasta 1 000 dólares depending on success and hit rate.
That means, it’s possible to start an attack with one step: Get a password reset or multi-factor authentication (MFA) change.That’s it.
From that single credential, the attacker moves laterally into cloud and virtualized environments.They harvest OAuth tokens, create new administrative service accounts, and embed access in machine-layer credentials.These non-human identities – service accounts, API keys, tokens – now outnumber human users 144 to 1.La expansión y la sobrecarga operativa dificultan la rotación y la auditoría. Ese movimiento lateral tiene un destino: Active Directory.

La publicidad es el objetivo

AD is the central nervous system of enterprise identity.Control it and you control everything – user accounts, group policies, and access to every domain-joined system in the network.The reason it’s so attractive to attackers – and so difficult to defend – is structural.Any authenticated user can read the entire directory.Every domain-joined system inherits trust from it.
Group Policy Objects linked at the domain head can be weaponized to disable security controls outright.Legacy protocols left enabled for application compatibility provide straightforward access.Microsoft’s own documentation says that “most identity attacks utilize common misconfigurations in Active Directory.”

When an attacker reaches the AD, they don’t need to force entry.The door is usually open.

La prevención es necesaria, pero no suficiente

The standard security stack – MFA, endpoint detection, email filtering – is built around human behavior.It wasn’t designed to govern the machine identity layer or to detect the kind of slow, legitimate-looking privilege escalation that characterizes modern AD attacks.An attacker that moves from a compromised human account to a service account to a domain administrator over 72 hours may never trigger a single alert.
This is why the conversation must shift from prevention-first to recovery-first.
Prevention still matters.Least-privilege access, auditing AD changes, hardening default configurations, disabling inactive accounts – these can help reduce the attack surface.But given that half of organizations have already experienced an AD attack, designing only for prevention means designing to fail.
True identity resilience requires the ability to detect unauthorized privilege escalations in near real time, roll back malicious changes before they propagate, and restore the identity environment to a known-trusted state quickly – not in days or weeks, but fast enough to contain the blast radius.That means treating AD and the non-human identity layer as Tier 0 assets, with the same governance and recovery investment you’d apply to any other mission-critical system.

Qué hacer ahora mismo para reforzar tu identidad

The gap between waquí most organizations are and waquí they need to be on identity resilience is real.But it’s closeable.The immediate priorities are unglamorous and operational:

  1. Audit what’s in your AD.
  2. Find the accounts that shouldn’t still exist.
  3. Rotate the credentials that haven’t been touched in years.
  4. Relaciona la actividad del servicio de asistencia con los eventos de creación de tokens y cuentas.

A help desk interaction followed by an MFA reset followed by a new service account is a high-confidence attack signal – and it’s detectable if you’re looking for it.
The longer-term work is architectural: Build recovery capability into your identity program so that when an attack succeeds – and it’s usually when, not if – you can contain it, reverse it, and try to restore trust faster than the attacker can consolidate their position.
Attackers are counting on your AD being ungoverned, your machine identities being invisible, and your recovery plan being theoretical.Close one of those gaps this quarter.Close all three and you’ve fundamentally changed the math. 

: desde la evaluación de vulnerabilidades hasta la reversión con un solo clic y la recuperación completa del bosque.
Hace poco participé junto a Vidya Shankaran en el podcast STRIVE para hablar sobre la brecha de gobernanza en las identidades no humanas. Echa un vistazo a nuestro episodio
– from vulnerability assessment to one-click rollback and full forest recovery.
I recently joined Vidya Shankaran on the STRIVE podcast to talk about the governance gap for non-human identities.Check out our episode aquí.And be sure to read Vidya’s blog, El punto ciego de la identidad de las máquinas se ha convertido ahora en una superficie de ataque principal.

Preguntas frecuentes

Q: Why are help desks becoming a major security risk?

A: Help desks are often trusted to reset passwords and modify MFA settings, making them attractive targets for social engineering.Attackers exploit this trust to gain initial access with minimal resistance.
Q: What role do non-human identities play in attacks?

A: Sprawl and operational overhead make rotation and audit of non-human identities, such as service accounts and API keys, difficult.Attackers use them to maintain persistence and move undetected across systems.
Q: Why is AD such a critical target?

A: AD controls authentication and access across the network.Gaining control of it allows attackers to manage users, policies, and systems at scale.
Q: Isn’t MFA and endpoint security enough to stop these attacks?

A: These tools focus on human behavior and may not detect slow, legitimate-looking privilege escalation.Attackers can operate within normal patterns and avoid triggering alerts.
Q: What does a recovery-first security approach mean?

A: It means preparing for the reality that breaches will happen and prioritizing the ability to detect, contain, and reverse them quickly.This approach helps reduce downtime and can help limit overall impact.
Q: What are the most important steps to take immediately?

A: Start by auditing your AD, removing unnecessary accounts, rotating old credentials, and monitoring for suspicious sequences of help desk and identity-related activities.
Dan Conrad is Principal Technologist and Field CTO at Commvault.
More related posts


Thumbnail_Blog-Okta-Early-Access-2026

Commvault® Extends Identity Resilience to Okta

Read more about Commvault® Extends Identity Resilience to Okta
Thumbnail_Blog-Lateral-Access-2026

Staying Resilient Against Lateral Access Exploits

Read more about Staying Resilient Against Lateral Access Exploits
Thumbnail_3_AD_Blogs_2025

Active Directory Forest Recovery: Why Manual Methods Are No Longer Viable

Read more about Active Directory Forest Recovery: Why Manual Methods Are No Longer Viable
Thumbnail_6_AD_Blogs_2025

AD Recovery Testing: How to Know Your Recovery Plan Will Actually Work

Read more about AD Recovery Testing: How to Know Your Recovery Plan Will Actually Work

Puntos Clave

  • Las identidades no humanas (NHI) ya superan con creces en número a los usuarios humanos y están creciendo a un ritmo mucho más rápido, lo que crea una superficie de ataque importante y poco regulada.
  • Los atacantes recurren cada vez más a la ingeniería social, como el phishing por voz (vishing), para burlar las defensas humanas y acceder a las credenciales a nivel de sistema.
  • Most NHIs operate with excessive permissions and lack proper lifecycle management, contributing to accumulated “identity debt.”
  • Las herramientas de seguridad tradicionales no detectan las amenazas en el nivel de máquina porque los NHI se comportan de forma diferente a los usuarios humanos.
  • Las organizaciones deben pasar de estrategias centradas en la prevención a enfoques centrados en la recuperación, dando prioridad a la detección rápida y la contención de los ataques basados en la identidad.

For the past decade, enterprise security investment has followed the human. Better authentication. Stronger multi-factor authentication (MFA). Phishing simulation. Identity-centric architecture. These investments were the right response to the threat landscape at the time.

The threat landscape has moved.

Today’s most sophisticated adversaries aren’t trying to defeat your MFA. They’re using it as a door. A convincing phone call to your IT help desk, an MFA reset, and a compromised human account – that’s the entry. What they’re actually after is what’s behind it: the sprawling, under-governed layer of NHIs that connects every system in your environment.

La magnitud del problema es abrumadora

Service accounts, API keys, OAuth tokens, AI agents – NHIs now outnumber human users by a ratio of 144 a 1, and they’re growing 4 y 10 veces más rápidoque las cuentas humanas. Sin embargo,menos del 25 % of organizations have formal policies governing their creation or decommissioning. Nearly all of them carry excessive permissions – rights that far exceed what their function requires.

This isn’t a new risk that suddenly appeared. It’s accumulated identity debt: years of provisioning without governance, automation without accountability, cloud expansion without visibility. And adversaries have noticed.

El vishing es el punto de entrada

Groups like ShinyHunters and Scattered Spider – operating under what researchers call the Scattered LAPSUS$ Hunters (SLH) cluster – have industrialized social engineering to exploit exactly this gap. Voice phishing rose un 449 % en 2025. These aren’t opportunistic calls. They’re coordinated operations: purpose-built scripts, recruited callers, incentivos económicos de hasta 1.000 dólares per successful help desk impersonation.

The call isn’t the attack. The call is the credential reset that gets an attacker past the human perimeter. The attack begins when they migrate to the machine layer – stealing OAuth tokens, creating administrative service accounts, embedding access into credentials that are rarely monitored and almost never rotated.

The human account gets remediated. The machine-layer access persists. The attacker has already moved on.

Three Vulnerabilities that Traditional Controls Can’t See

Standard security tools are designed around human behavior. They flag anomalous logins, unusual geolocation, suspicious email traffic. NHIs operate differently, and that difference is the blind spot.

OAuth abuse, for instance, looks like normal API traffic – even after a password reset. Thousands of undocumented service accounts operate in large enterprises with administrative privileges, often long after the projects that created them ended. Long-lived API keys embedded in DevOps pipelines carry broad access with no device context and no login alert.

MFA doesn’t cover them. Endpoint detection doesn’t see them. Email filtering is irrelevant to them.

El cambio de enfoque: de «la prevención ante todo» a «la recuperación ante todo»

The logical response to a threat that often evades traditional detection is to stop assuming you can prevent every intrusion and start designing for rapid recovery from the ones that succeed.

That means treating NHIs as Tier 0 assets – with the same governance controls applied to domain administrators or cloud control planes managed with human identities. It means replacing static secrets with short-lived tokens and automatic rotation.

It also means correlating cross-domain signals: A help desk interaction followed by an MFA reset followed by a new token creation is a high-confidence indicator of compromise, and catching it early is the difference between containment and a prolonged breach. It means mapping NHIs to human identities for accountability.

Most importantly, it means having the capability to detect unauthorized privilege escalations and roll back malicious identity changes in real time – returning the environment to a known-trusted state before the damage extends.

Prevention still matters. But given the governance gap many organizations are carrying, recovery speed is becoming a primary resilience metric. Organizations should build identity programs designed for the attacks that are already happening, not the ones that were common five years ago.

Visit the Readiversey echa un vistazo a nuestro libro electrónicoLa crisis de identidad no humana», que analiza en profundidad la superficie de ataque de las máquinas y el marco para la resiliencia de la identidad.

Preguntas frecuentes

Q1: What are non-human identities (NHIs)?

A: NHIs include service accounts, API keys, OAuth tokens, and AI agents that allow systems and applications to interact. Unlike human users, they often operate automatically and at scale, making them harder to monitor and control.

Q2: Why are NHIs considered a security risk?

A: NHIs often have excessive permissions and lack proper governance, making them attractive targets for attackers. Because they are rarely monitored or rotated, compromised credentials can persist undetected for long periods.

Q3: How do attackers exploit NHIs?

A: Attackers typically gain initial access through social engineering, such as voice phishing, then pivot to the machine layer. They steal tokens, create new service accounts, or embed persistent access in credentials that are not closely monitored.

Q4: Why don’t traditional security tools detect these threats?

A: Most security tools are designed to track human behavior, such as login anomalies or phishing attempts. NHIs generate normal-looking system traffic, which allows malicious activity to blend in with legitimate operations.

Q5: What is meant by a “recovery-first” security approach?

A: A recovery-first approach focuses on quickly detecting breaches and restoring systems to a trusted state rather than assuming all attacks can be prevented. This includes identifying unauthorized changes and rolling them back in real time.

Q6: How can organizations improve NHI security?

A: Organizations can treat NHIs as critical assets, implement strict governance policies, replace static credentials with short-lived tokens, and correlate signals across systems. Mapping NHIs to human owners also improves accountability and oversight.

Vidya Shankaran is Field CTO at Commvault.

More related posts


Thumbnail_Blog-SHIFT-Identity-Resilience-2026-Linkedin

Your Identity Infrastructure Is a Target. Here’s What Commvault Is Doing About It.

Read more about Your Identity Infrastructure Is a Target. Here’s What Commvault Is Doing About It.
Thumbnail_Blog-Rise-of-AI-Agents-in-Resops-2026

Commvault and Microsoft: The Rise of AI Agents in ResOps

Read more about Commvault and Microsoft: The Rise of AI Agents in ResOps
Thumbnail_Blog-Unified-Resilience-2026

Why AI Is Breaking Your Resilience Strategy (And What to Do About It)

Read more about Why AI Is Breaking Your Resilience Strategy (And What to Do About It)
Thumbnail_Blog_Resilient-Against-the-AI-Machine

Resilient Against the AI Machine

Read more about Resilient Against the AI Machine

Organizations today are building applications faster, automating workflows at scale, and turning data into insights, powered by platforms like Microsoft Power Platform. What started as a low-code productivity layer has quickly become mission-critical, embedded in the processes that support revenue generation, day-to-day operations, and strategic decision-making.

But as the reliance on these business intelligence assets grows, so does the associated risk. The same platform accelerating innovation can also amplify the impact of operational errors, misconfigurations, and malicious actions.

A misconfigured workflow, a deleted report, or a broken application can disrupt business processes, compromise decision-making, and erode trust in the systems the business relies on. And when something goes wrong, recovery is rarely straightforward.

Commvault is helping address these challenges with enterprise-grade data protection and recovery for Microsoft Power Platform, starting with Power BI – allowing organizations to help keep the insights, workflows, and apps they build protected and rapidly recoverable. 

Power BI: The Gap Between Insight and Recovery

At the center of many Power Platform deployments is Microsoft Power BI, providing analytics and business intelligence, transforming data into reporting, forecasting, and operational visibility.

When Power BI assets are lost or compromised teams can quickly lose access to trusted insights, interrupting reporting cycles, and delaying business decision-making.

In practice, however, protection strategies lag behind the importance of these assets. Many organizations rely on manual file exports or limited native capabilities that weren’t designed for comprehensive recovery. When something breaks, teams are often forced to rebuild manually with no ability to restore exactly what’s needed. This makes recovery slow, error-prone, and difficult to scale.

Commvault Cloud Backup & Recovery for Microsoft Power Platform

Now generally available, Commvault Cloud Backup & Recovery for Microsoft Power Platform helps organizations protect and recover their business-critical assets, such as reports, from accidental deletion, corruption, and malicious activity.

  • Automated, policy-based protection: Apply policy-driven backups across Power BI workspace assets, enabling consistent, scalable coverage without manual intervention.
  • Rapid, granular recovery: Restore individual reports, folders to a specific point in time, avoiding manual rebuilds and helping minimize downtime and disruption.
  • Isolated, immutable backups: Help protect data from ransomware and unauthorized changes with backups designed to prevent unauthorized modification or deletion.
  • Simplified compliance: Maintain long-term retention (up to 10 years), centralized audit logs, and reporting to support regulatory and internal requirements.

Unified Platform for Resilience

Commvault Cloud offers a unified platform to protect SaaS, cloud, and on-premises workloads, including Microsoft 365, Dynamics 365, Salesforce, VMs, databases, and endpoints. With Microsoft Power Platform support, customers can streamline protection, recovery, and resilience for more workloads, helping reduce tool sprawl and simplify operations.

How to Get Started

Commvault Cloud Backup & Recovery for Power Platform is delivered as a SaaS solution, designed for fast deployment and minimal operational overhead. Organizations can connect their Power BI environment, apply policy-based protection, and begin backing up critical data in a matter of steps.

Automated discovery protects new reports and folders are included as environments evolve, while centralized management provides a single place to monitor, manage, and recover data at scale.


What’s Next: Expanding Across Power Platform

We intend to expand protection and resilience across Microsoft Power Platform to include Power Apps and Power Automate, extending coverage to the applications and workflows that power your business. Plans, timelines, and features are subject to change and should not be relied upon in making purchasing decisions.

Protect What Powers Your Business

As reliance on Microsoft Power Platform grows, so does the need for resilient, enterprise-grade protection. With Commvault Cloud, you can:

  • Protect critical assets against deletion, corruption, and attack
  • Rapidly recover exactly what you need – without rebuilding everything
  • Maintain trust in data, decisions, and automation
Ready to make your Microsoft Power BI investment resilient?

Learn more and see Commvault Cloud in action atcommvault.com/platform/power-platform.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Puntos Clave

  • La migración de máquinas virtuales a Red Hat OpenShift Virtualization es un proceso por fases que requiere una protección constante en todos los entornos híbridos.
  • Una platform de protección de datos unificada y nativa de Kubernetes platform reducir la complejidad y platform eliminar la necesidad de herramientas o procesos independientes.
  • Reliable resilience – including immutable backups and threat detection – is critical during migration, when risks are highest.
  • Las opciones de recuperación flexibles permiten a las organizaciones adaptarse rápidamente si fallan los pasos de la migración o cambian los plazos.
  • Consolidar la protección de las máquinas virtuales y los contenedores ayuda a reducir la proliferación de herramientas y a mantener una gobernanza coherente.

If you’re an IT leader today, chances are your virtualization strategy is under active review.

Rising costs, licensing uncertainty, and long-term vendor lock-in have many organizations reassessing their reliance on traditional hypervisors. At the same time, Kubernetes has matured into the operational foundation for modern applications.

These two realities are converging – and for many enterprises, Red Hat OpenShift Virtualization is emerging as a preferred destination for running virtual machines within a Kubernetes-native operating model.

This transition is accelerating across industries. As organizations modernize infrastructure on their own terms, Red Hat OpenShift Virtualization is increasingly viewed as a way to modernize the platform without the need for application refactoring. With that momentum comes a critical question:

How do you migrate virtual machines while maintaining consistent protection, resilience, and recoverability throughout the process?

To answer it, you need to examine how most enterprise migrations actually unfold – and where protection and resilience become critical.

La migración es un viaje, no algo que ocurre una sola vez

Seasoned IT leaders know that infrastructure transitions rarely happen all at once.

For enterprises opting to move from hypervisors like VMware to Red Hat OpenShift Virtualization, the transition typically unfolds in phases. During this time, organizations inevitably operate in a mixed state:

  • Las máquinas virtuales basadas en VMware siguen respaldando las operaciones clave de la empresa.
  • Máquinas virtuales que se acaban de poner en marcha en Red Hat OpenShift Virtualization.
  • Aplicaciones en contenedores que comparten los mismos clústeres de Red Hat OpenShift.

This coexistence period introduces complexity and risk. Data is in motion, environments are changing, and protection gaps can appear if tooling and processes don’t evolve alongside workloads.

Es fundamental mantener una protección fiable

Commvault lleva mucho tiempo ofreciendo soluciones de protección y recuperación de datos tanto para entornos VMware como para cargas de trabajo de Kubernetes que se ejecutan en Red Hat OpenShift. Ese mismo modelo de protección nativo de Kubernetes y basado en políticas se extiende ahora a las máquinas virtuales que se ejecutan en Red Hat OpenShift Virtualization. Lo que realmente les gusta a los clientes es la coherencia:

  • Una única platform la protección y la recuperación.
  • Operaciones basadas en políticas que se aplican de manera uniforme en todas las cargas de trabajo.
  • Diseñado para funcionar con tus herramientas y procesos actuales a medida que los entornos van cambiando.

VMs running on Red Hat OpenShift Virtualization are protected using the same workflows and governance constructs as containerized applications. This unified approach is being embraced by organizations standardizing on Red Hat OpenShift that want a simpler, more consistent way to manage data across environments.

This capability is available today.Commvault Cloudofrece protección para entornos de Red Hat OpenShift Virtualization compatibles con la versión de soporte a largo plazo 11.40 y la versión de innovación 11.42, lo que significa que los clientes ya pueden poner estas funciones en producción.

You Shouldn’t Need to Manage Protection Differently

Once VMs move to Red Hat OpenShift Virtualization, they shouldn’t require special handling from a protection standpoint.

Commvault Cloud discovers and protects Red Hat OpenShift Virtualization VMs alongside containerized applications, helping give teams centralized visibility, consistent policy enforcement, and simplified recovery operations. Virtualized and containerized workloads are managed together – without introducing operational silos.

For organizations managing diverse application portfolios, this treatment of VMs inside Kubernetes helps reduce operational friction while maintaining enterprise-grade controls.

La ciberresiliencia es clave cuando la migración aumenta el riesgo.

Los periodos de migración son un momento especialmente vulnerable. Los cambios generan complejidad, y la complejidad aumenta el riesgo de perder datos y de sufrir ataques de ransomware. Commvault Cloud mantener la resiliencia durante toda esta fase gracias a:

  • Copias de seguridad aisladas físicamente e inmutables para cargas de trabajo de Red Hat OpenShift Virtualization.
  • Datos de copia de seguridad que facilitan la detección de amenazas y el análisis forense, lo que ayuda a los equipos a comprobar que todo está listo para la recuperación antes de restaurar las cargas de trabajo.
  • Advanced recovery capabilities designed to help organizations minimize operational disruption.

Tanto si las cargas de trabajo están en fase previa a la migración, en plena transición o ya funcionando a pleno rendimiento en Red Hat OpenShift Virtualization, la resiliencia se mantiene intacta.

La flexibilidad en la recuperación te da confianza

Every modernization initiative needs room for adjustment.

Commvault supports both in-place and out-of-place recovery for Red Hat OpenShift Virtualization virtual machines, including full VM context and configuration. If a migration step doesn’t go as planned – or timelines need to shift – teams may recover quickly and move forward without compromising availability or data integrity.

Protección nativa de Kubernetes más allá de las máquinas virtuales

Para muchas empresas, la virtualización es solo una parte de una estrategia más amplia de modernización de aplicaciones. Commvault Cloud ofrece protección centrada en las aplicaciones y nativa de Kubernetes para cargas de trabajo en contenedores, incluidos los volúmenes persistentes y los metadatos de las aplicaciones, en todas las distribuciones de Kubernetes certificadas por la CNCF. Esto permite la movilidad y la recuperación de las aplicaciones cloud, al tiempo que ayuda a mantener la coherencia operativa en todos los entornos.

Reducir la proliferación de herramientas a medida que evoluciona la infraestructura

Platform transitions often introduce new tools, new processes – and new complexity.

By using Commvault Cloud as a unified protection platform for:

  • Máquinas virtuales de VMware.
  • Máquinas virtuales de Red Hat OpenShift Virtualization.
  • Aplicaciones en contenedores.

Las organizaciones pueden ayudar a reducir la proliferación de herramientas, simplificar la administración y mantener una gobernanza coherente, incluso a medida que evolucionan las estrategias de infraestructura.

Cómo encaja todo

During any migration, it helps to understand how the pieces work together. Red Hat’s Migration Toolkit for Virtualization takes care of moving VMs from VMware into Red Hat OpenShift Virtualization.

Commvault Cloud helps provide the protection and resilience that stays with your workloads throughout the process, so data can remain protected before, during, and after migration. This can help keep recoverability from falling behind as workloads move.

Continuing the Conversation at Red Hat Summit

We’re already working with customers that are actively moving virtual machines onto OpenShift Virtualization – and we’re continuing these discussions at Red Hat Summit, May 11–14 in Atlanta.

At the Commvault booth, we’ll be:

  • Hablando con los responsables de TI sobre los retos reales en materia de resiliencia.
  • Compartimos consejos prácticos para que puedas hacer la migración con confianza.
  • Demostración de Cloud de Commvault Cloud para Red Hat OpenShift Virtualization.

If maintaining resilience and recoverability throughout your virtualization strategy is a priority, we’d welcome the opportunity to connect.

Avanzando con confianza

Red Hat OpenShift Virtualization is becoming a foundational component of modern enterprise infrastructure. But you can’t rush migration at any cost; you must build protection, resilience, and recovery into the process from the beginning.

With Commvault Cloud, protecting Red Hat OpenShift Virtualization workloads isn’t a future aspiration. It’s something customers already are doing – using a unified platform to modernize confidently while staying resilient and recoverable.

“Red Hat OpenShift Virtualization delivers a reliable, consistent foundation for organizations to support their entire virtualized estate,” says Steve Gordon, Senior Director, Product Management, Hybrid Cloud Platforms, at Red Hat. “By leveraging an optimized integration like Commvault Cloud with Red Hat OpenShift Virtualization, our customers can move forward with greater confidence, knowing their workloads are protected consistently before, during, and after migration.”

Preguntas frecuentes

Q: Why is VM migration considered a multi-phase process?

A: Most enterprises cannot migrate all workloads at once, so they operate in a hybrid state with legacy and new environments running simultaneously. This phased approach introduces complexity, making consistent protection and visibility essential throughout the transition.

Q: What role does resilience play during VM migration?

A: Resilience enables organizations to maintain data protection, recover quickly from failures, and defend against threats like ransomware. During migration, when systems are in flux, strong resilience measures can help prevent data loss and operational disruption.

Q: How does Commvault Cloud simplify protection across environments?

A: Commvault Cloud provides a single platform with policy-driven protection for VMware VMs, OpenShift Virtualization VMs, and containerized applications. This unified approach enables consistent operations without introducing new tools or workflows.

Q: What makes Kubernetes-native protection important?

A: Kubernetes-native protection aligns with how modern applications are deployed and managed, covering both containers and virtual machines. It enables simple data management, mobility, and recovery within cloud-native environments.

Q: How does recovery flexibility improve migration confidence?

A: Flexible recovery options, such as in-place and out-of-place restores, can help teams quickly recover workloads if something goes wrong. This adaptability helps reduce downtime and enables organizations to adjust migration plans without risking data integrity.

Q: How can organizations reduce complexity during infrastructure transitions?

A: By adopting a unified data protection platform, organizations can manage all workloads – virtualized and containerized – through a single interface. This approach helps reduce tool sprawl, simplify administration, and maintain consistent governance across evolving environments.

Jason Gizaes director sénior de marketing de socios de contenido global en Commvault.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Puntos Clave

  • La la Readiverse Academy ha puesto en marcha un programa de certificación estructurado y por niveles, que abarca desde los conocimientos básicos hasta la especialización avanzada cloud .
  • Las certificaciones se ajustan a puestos reales, lo que ayuda a los alumnos a desarrollar habilidades relevantes para sus responsabilidades en Cloud de Commvault Cloud .
  • The program includes four tiers – Practitioner, Specialist, Professional, and Expert – each increasing in depth and operational capability.
  • El aprendizaje se basa en tres pilares fundamentales: platform , resiliencia cibernética y conocimientos sobre cargas de trabajo.
  • Las opciones de aprendizaje flexibles, que incluyen formatos a tu propio ritmo y con profesor, permiten a los profesionales avanzar según sus horarios y objetivos.

The environments you protect with Commvault® Cloud are increasingly complex, and the expectations on your teams that run them are higher than ever. It’s no longer just about knowing the platform. It’s about being able to operate, protect, and recover, often under pressure.

If you’ve already started your learning journey in the la Readiverse Academy, welcome back. And if you’re new here, you’re joining at the right time.

Today, we’re introducing a structured, tiered certification approach that gives learners a clear, skill‑based path from foundational platform knowledge to advanced cloud engineering expertise.

Creamos contenido para ti

Commvault Cloud environments demand expertise across multiple responsibilities, often within the same role. Administrators, security specialists, cloud engineers, and workload owners require different depths and breadths of knowledge. And not everyone needs to learn the same things, in the same order, to be effective.

The new la Readiverse Academy certification tiers reflect that reality. Learners progress through clearly defined levels that build on one another so that your certification aligns to what you actually do and validates those capabilities to the teams you work with.

  • Commvault Cloud Practitioner – foundational platform and resilience knowledge.
  • Commvault Cloud Specialist – expanded operational and security depth.
  • Commvault Cloud Professional – advanced recovery and workload expertise.
  • Commvault Cloud Expert – full cloud engineering and resilience leadership.

Each tier is earned through a combination of coursework, hands‑on lab activities, and validated assessments. As learners progress, the scope and depth of operational capability demonstrated increases accordingly.

Un camino claro: de principiante a experto

El programa de certificación se basa en tres pilares fundamentales de competencias que están presentes en todos los niveles:

  • platform básicas platform
  • Conceptos de resiliencia cibernética
  • Carga de trabajo y experiencia en funcionalidades

Cada nivel añade requisitos específicos relacionados con esos pilares. Los alumnos pueden hacer cursos sueltos o combinar los requisitos indicados para conseguir los objetivos de certificación.

Already in la Readiverse Academy? What this Means for You.

With a new structure like this, the most important question is what it means for the progress you’ve already made. If you’ve already completed courses or earned certifications in the la Readiverse Academy, congratulations! Your investment matters, and we want to be clear about what happens next.

Those certifications represent your history and accomplishments with Commvault. The new program is aligned to our expanded portfolio of cyber resilience features for Commvault Software, Commvault SaaS, and hybrid environments. As your needs grow to require more from Commvault, these courses and certifications will help you configure, manage, and optimize Commvault to meet your organization’s unique needs.

There is no direct progression from the previous certification tracks to the new program, but your existing certifications validate your expertise on the former product releases. As those releases are retired, those certifications will reach end of life as well. Learners who are already invested in the la Readiverse Academy are well positioned to progress quickly.

Who Should Take la Readiverse Academy Courses and Certifications

la Readiverse Academy certifications are designed for professionals working across Commvault SaaS, Commvault Software, and hybrid environments.

  • Platform administrators managing day‑to‑day operations.
  • Especialistas en seguridad dedicados a proteger datos y reforzar la seguridad de los entornos.
  • Cloud encargados de la configuración del plano de control y de la resiliencia avanzada.
  • Los responsables de las tareas que necesiten tener conocimientos especializados en ámbitos específicos de datos.

All training is available for self‑paced learning, with select courses also offered in instructor‑led formats, so learners can progress in a way that fits their role and schedule.

Cómo empezar o seguir con tu proceso de aprendizaje

Whether you’re starting fresh or continuing your journey, the next step is simple and designed to meet you where you are.

  • Inicia sesión o regístrate encommvault.com.
  • ¿Eres nuevo en Commvault? Empieza con el curso «Commvault Cloud ».
  • ¿Te encargas de la gestión de la carga de trabajo? Echa un vistazo a nuestro catálogo de cursos, que abarca prácticamente todo.
  • ¿Buscas estrategias para facilitar la recuperación tras un ciberataque? El curso sobre ciberresiliencia es tu primer paso.

¿Qué nos espera ahora?

Our goal is to make advancement predictable, transparent, and aligned to real‑world roles to help learners know what’s next and how to prepare for it.

We are committed to giving every Commvault Cloud user the knowledge to operate, protect, and recover their environment with confidence. Because when it matters most, certification isn’t about credentials. It’s about being resilient and ready to recover.

Preguntas frecuentes

Q: What is the purpose of the la Readiverse Academy certification program?

A: The program provides a structured, skill-based learning path that helps professionals progress from basic platform knowledge to advanced cloud engineering expertise. It aligns training with real-world responsibilities to enable learners to apply their knowledge effectively in complex environments.

Q: What are the different certification tiers available?

A: There are four tiers: Commvault Cloud Practitioner, Specialist, Professional, and Expert. Each level builds on the previous one, increasing in technical depth, operational scope, and leadership capability.

Q: Who should enroll in la Readiverse Academy courses?

A: The courses are designed for platform administrators, security specialists, cloud engineers, and workload owners working across SaaS, software, and hybrid environments. Each role can follow a tailored learning path based on their responsibilities.

Q: How are the certifications earned?

A: Certifications are achieved through a combination of coursework, hands-on labs, and validated assessments. As learners progress, they demonstrate increasing levels of expertise across platform, security, and workload domains.

Q: What happens to existing la Readiverse Academy certifications?

A: Existing certifications remain valid as proof of past expertise but are tied to earlier product releases. As those releases are retired, the certifications will reach end of life, encouraging learners to transition to the new program.

Q: How can someone get started with the new program?

A: New learners can begin with the Commvault Cloud Administrator course, while existing users can log in to continue their progress. Additional courses are available based on specific goals, such as workload management or cyber resilience strategies.

Suzanne Klausner is Director, Customer Enablement Strategy, at Commvault.

More related posts


Thumbnail_Blog-Ready-or-Not-2026

Why Every CIO Needs a ‘Ready. Or Not.’ Mindset

Read more about Why Every CIO Needs a ‘Ready. Or Not.’ Mindset
Thumbnail_Blog_Readiness-Update-2024

Boost Your Cyber Resilience and Readiness

Read more about Boost Your Cyber Resilience and Readiness
Social_Readiverse_Blog_LinkedIn-1

The Readiverse: Your Go-To Learning Resource for Cyber Resilience and Readiness

Read more about The Readiverse: Your Go-To Learning Resource for Cyber Resilience and Readiness

Puntos Clave

  • Los flujos de trabajo de restauración tradicionales pueden provocar desviaciones en la infraestructura de los entornos gestionados por Terraform al aprovisionar nuevos recursos fuera del estado.
  • Clumio Backtrack está diseñado para restaurar datos directamente en los buckets de S3 y las tablas de DynamoDB ya existentes, lo que ayuda a mantener la identidad de los recursos.
  • La recuperación in situ ayuda a reducir la necesidad de realizar importaciones manuales de Terraform, reconfigurar los puntos finales y conciliar el estado durante los incidentes.
  • Alinear los flujos de trabajo de recuperación con los principios de «Infraestructura como código» (IaC) ayuda a mantener la integridad de la configuración y la previsibilidad operativa.
  • El diseño de la recuperación es tan importante como backup para los equipos que gestionan entornos de producción mediante Terraform.

IaC brings consistency, repeatability, and version control to cloud environments. Terraform becomes the source of truth for what exists, how it is configured, and how it should behave. Recovery introduces a new challenge.

Traditional restore operations often create new resources – new S3 buckets, new DynamoDB tables, new endpoints. From Terraform’s perspective, those resources were not defined in code. They do not exist in state.

That creates drift. In routine operations, drift is manageable. During an incident, it compounds. This is where recovery design matters as much as backup design.

El problema de la deriva en IaC

En un modelo de restauración típico:

  • Un recurso protegido se restaura como un nuevo recurso.
  • El recurso original sigue estando dañado, sobrescrito o no funciona.
  • El estado de Terraform no reconoce el nuevo recurso.
  • Los equipos deben importar manualmente los recursos a State.
  • Puede que haya que actualizar las configuraciones de las aplicaciones.

For platform teams managing production infrastructure through Terraform, this introduces friction at exactly the wrong moment. The challenge isn’t backup reliability itself, but how restore workflows integrate with infrastructure-as-code practices.

Te presentamos la recuperación in situ con Clumio Backtrack

Clumio Backtrack es una función de recuperación que te ayuda a restaurar datos directamente en los recursos existentes de AWS, en lugar de tener que aprovisionar una infraestructura de sustitución. Cuando se configura a través del proveedor de Clumio para Terraform, Backtrack te permite crear flujos de trabajo de recuperación que se ajustan a la infraestructura definida en código.

Clumio Backtrack es compatible tanto con Amazon S3 como con Amazon DynamoDB. Si quieres conocer más detalles técnicos sobre los flujos de trabajo de recuperación específicos de DynamoDB, echa un vistazo a nuestra entrada del blog sobreClumio Backtrack para DynamoDB.

En lugar de tener que buscar recursos de sustitución, Backtrack te ayuda a recuperar:

  • Objetos S3 directamente en el bucket original.
  • Datos de DynamoDB directamente en la tabla original.

From Terraform’s perspective, the infrastructure is intended to remain unchanged, with defined resources continuing to match the declared configuration. This helps reduce the need for manual resource imports, temporary restore tables, endpoint rewiring, and state reconciliation under pressure.

Un ejemplo práctico

Imagina un entorno de producción gestionado íntegramente a través de Terraform. Una tabla de DynamoDB lleva el control del inventario; un bucket de S3 almacena los recursos de la aplicación; los roles y las políticas de gestión de identidades y accesos están codificados; y las políticas de protección se definen mediante Terraform. Si se produce un error antes de un pico de tráfico importante, los métodos tradicionales de restauración pueden crear nuevos recursos que habrá que volver a integrar en Terraform.

Con Backtrack, la recuperación está diseñada para realizarse dentro de los límites de los recursos existentes, lo que ayuda a mantener intacta la infraestructura definida y a conservar la identidad de los recursos. Este enfoque tiene como objetivo eliminar la necesidad de actualizar Terraform para adaptarlo a un bucket o una tabla recién creados, tratando la recuperación como una operación a nivel de datos en lugar de como un proceso de sustitución de la infraestructura.

Por qué es importante para Platform

Para los equipos que apuestan por la infraestructura como código (IaC), los flujos de trabajo de recuperación deben preservar la identidad de los recursos, la alineación de estados, la integridad de la configuración y la previsibilidad operativa. La restauración in situ contribuye a alcanzar esos objetivos al limitar los cambios en la infraestructura durante los procesos de recuperación.

Recuperación a Cloud

Backtrack is designed to operate at cloud scale – whether restoring a small number of objects or large datasets. Recovery performance varies based on workload size and environment configuration, but the architectural objective remains consistent: restore data without introducing new infrastructure drift.

For Terraform-driven environments, that distinction matters.

Dónde encaja este enfoque

La recuperación in situ es especialmente relevante para:

  • Cargas de trabajo de DynamoDB de alto rendimiento
  • Depósitos de S3 con un gran número de objetos
  • Sistemas de producción gestionados íntegramente a través de Terraform
  • Entornos complejos en los que resulta difícil redirigir las dependencias de las aplicaciones hacia nuevos recursos

Cuando la infraestructura se define de forma declarativa, los flujos de trabajo de recuperación deberían ajustarse a esa misma disciplina.

Cómo empezar

Para conocer Clumio Backtrack y su integración con Terraform:

Definir la protección como código es solo una parte de la historia. Diseñar flujos de trabajo de recuperación que mantengan la integridad de la infraestructura es lo que completa el modelo.

Preguntas frecuentes

Q: What problem do traditional restores create in Terraform-managed environments?

A: Traditional restores often create new resources, such as replacement S3 buckets or DynamoDB tables, that are not defined in Terraform state. This can lead to infrastructure drift and force teams to manually import resources and reconcile configurations during high-pressure incidents.

Q: How does Clumio Backtrack differ from standard restore approaches?

A: Instead of provisioning new infrastructure, Clumio Backtrack is designed to restore data directly into the existing AWS resource. This approach helps preserve resource identity and keep Terraform state aligned with the declared configuration.

Q: Which AWS services are supported by Clumio Backtrack?

A: Clumio Backtrack supports Amazon S3 and Amazon DynamoDB. It is designed to restore S3 objects into the original bucket and DynamoDB data into the original table, helping maintain consistency with infrastructure defined in code.

Q: Why is in-place recovery important for platform teams?

A: Platform teams rely on infrastructure as code for consistency and control. In-place recovery helps maintain state alignment, configuration integrity, and operational predictability without introducing additional infrastructure changes during recovery events.

Q: When is in-place recovery particularly valuable?

A: It is especially useful for high-throughput DynamoDB workloads, Depósitos de S3 con un gran número de objetos, and production systems fully managed through Terraform. It also can be beneficial in environments where redirecting application dependencies to newly created resources would be complex or risky.

Q: How can teams get started with Clumio Backtrack and Terraform integration?

A: Teams can review thedocumentación del proveedor de Clumio para Terraform, echar un vistazo alcódigo fuente del proveedor en GitHub, and watch the vídeo de demostración de Backtrack referenced in the blog to understand implementation and workflow details.

Lawrence Chang is Chief Engineering Officer of Clumio and Vir Choksiis Principal Product Marketing Manager at Commvault.

More related posts


Thumbnail_Blog-AWS-Data-Protection-Terraform-Clumio-2026

Automating AWS Data Protection with Terraform and Clumio

Read more about Automating AWS Data Protection with Terraform and Clumio
Thumbnail_Blog_Clumio-Tech-2025

Restore only what matters: Clumio Backtrack for DynamoDB

Read more about Restore only what matters: Clumio Backtrack for DynamoDB
Thumbnail_Blog-GoogleWorkspace-2026

How the Move to Clumio Delivered 66.7% Savings on AWS Backups

Read more about How the Move to Clumio Delivered 66.7% Savings on AWS Backups
Thumbnail_Blog_AWS-Marketplace-AI

Commvault Featured in New AI Agent Solutions in AWS Marketplace

Read more about Commvault Featured in New AI Agent Solutions in AWS Marketplace
Man-and-woman-working-on-laptops-profile-Crocus-Thumbnail

Protecting Your Amazon S3 Data with Clumio: A Comprehensive Solution

Read more about Protecting Your Amazon S3 Data with Clumio: A Comprehensive Solution

Clumio

Read more about Clumio

Puntos Clave

  • La mayoría de los ejercicios de simulación solo sirven para comprobar el rendimiento, en lugar de poner de manifiesto las deficiencias reales en la respuesta ante incidentes.
  • Para que los ejercicios sean eficaces, deben incluir elementos de fricción, ambigüedad y presión que reflejen situaciones reales.
  • Limitar el alcance del ejercicio a unos pocos escenarios críticos y definir el éxito como la detección de problemas, en lugar de quedar bien, puede dar lugar a conclusiones más significativas y aplicables.
  • La participación de distintos departamentos, y no solo de los equipos técnicos, es fundamental para evaluar con precisión la respuesta de la organización.
  • La verdadera resiliencia se demuestra mediante pruebas reales de recuperación, no solo con simulaciones basadas en debates.

There is a moment most security leaders recognize, even if they do not say it out loud. The tabletop just wrapped. The team is filing out. Everyone looks reasonably satisfied. And somewhere in the back of your mind, a quiet question surfaces: Did we actually learn anything?

If you are honest, the answer is often no.
That is not because tabletop exercises are a bad idea. They are one of the most valuable tools a security leader has. The problem is how most organizations run them – and what they are actually measuring when they do.

La trampa del rendimiento

The most common mistake in tabletop exercises has nothing to do with the scenario. It has to do with the goal. Most teams, consciously or not, build exercises designed to demonstrate competence rather than discover gaps.
The scenario generally follows a clean arc. Information arrives in a logical sequence. The right people say the right things. Everyone feels prepared. And that feeling – confident, well-rehearsed, almost collegial – is exactly the problem.
Real incidents do not run on clean arcs. They arrive with incomplete information, conflicting signals, unavailable people, and a business demanding answers faster than the facts support. If your tabletop does not create that kind of friction, you have not tested incident response. You have practiced a conversation.
When the exercise is designed to validate rather than stress-test, a second problem follows: People stop being honest. Nobody says, “I don’t know who owns that decision” or “we have never actually tested that recovery path.” They say what sounds right. And the gaps that should surface in a controlled environment stay hidden until they surface in a real one.

Lo que realmente evalúa un buen ejercicio

Before you build a scenario, you need to answer a simpler question: What do you actually want to learn? Not 20 things. Three or four.
Can your team make a shutdown decision fast enough, and does everyone know who has the authority to make it? When security, IT, legal, and communications are all in the room with conflicting priorities, can they actually reach decisions together? Can you explain the business impact of an incident clearly enough for leadership to act – not just understand? And if you had to restore a critical system in the next four hours, could you really do it?

Once you know what you are testing, build a scenario with real friction. Make a key person unavailable mid-exercise. Introduce a customer escalation. Have a regulator ask a question the team cannot answer from the runbook.
Give people incomplete information and see how they make decisions anyway. The value is not in watching people succeed under pressure. It is in finding the places where the process breaks down while the stakes are still low enough to fix it.

Di esto en voz alta al principio: hoy en día, el éxito consiste en detectar problemas, no en quedar bien. Esa sola frase cambia lo que la gente se atreve a decir en la sala.

El problema de la gente

Una simulación en la que solo participen los equipos de seguridad y de TI es una conversación técnica, no un ejercicio de respuesta ante incidentes. Si el departamento jurídico no está presente, si el de comunicaciones tampoco está, y si faltan los responsables de negocio y la dirección ejecutiva, no estás poniendo a prueba cómo responde realmente tu organización ante una crisis. Lo que estás haciendo es ver cómo un grupo de gente inteligente analiza una situación hipotética. Los incidentes reales se gestionan en toda la empresa. El simulacro debería reflejar eso.

Hablar del tema no es suficiente

This is where most organizations stop short. A paper exercise is important – but it is not confidence.
Talking through a recovery scenario tells you something. Actually restoring a system tells you something different. Can you bring identity back to a clean point in time? Can you validate that what you are recovering is trustworthy? Can you restore a Tier 1 application and confirm it comes back cleanly, without carrying the infection with it?

Those are not questions you can answer in a conference room. At some point, the plan has to meet the environment – and you need to know whether they match.

Una vez finalizado el ejercicio

The debrief tells you whether the exercise mattered. If the hot wash is quiet, vague, or full of “good reminders,” the exercise did not push hard enough. A well-run tabletop should leave you with a short list of real findings, clear owners, and deadlines. If you cannot answer what broke, who is fixing it, and by when, you ran an event, not an exercise.
The goal was never to pass the exercise. It was to learn something important while the cost of being wrong was still just time.
Watch our recent episode of the STRIVE podcast, where I join my colleague Chris Mierzwa, Senior Director, Portfolio Marketing, for charlar a fondo sobre los ejercicios de simulación.

Preguntas frecuentes

Q: Why do most tabletop exercises fail to deliver real value?

A: Many exercises are designed to make teams look prepared rather than uncover weaknesses. This leads to scripted discussions that miss the unpredictability and pressure of real incidents.

Q: What should a tabletop exercise aim to achieve?

A: It should focus on answering a small number of critical questions, such as decision-making speed, ownership clarity, and recovery capability. This focus helps teams uncover meaningful gaps instead of surface-level insights.

Q: How can organizations make exercises more realistic?

A: Introduce uncertainty, missing information, and unexpected disruptions during the scenario. These elements force teams to think critically and act under pressure, closer to real incident conditions.

Q: Who should be involved in a tabletop exercise?

A: Beyond security and IT, teams like legal and communications, business leaders, and executives should participate. This enables the exercise to reflect how real incidents are managed across the organization.

Q: Why is talking through recovery not enough?

A: Discussion can highlight plans, but only real testing proves whether systems actually can be restored cleanly and quickly. Practical validation is necessary to confirm recovery readiness.

Q: What defines a successful tabletop exercise outcome?

A: A strong exercise results in clear findings, assigned owners, and defined timelines for remediation. If these are missing, the exercise likely did not challenge the team enough.

Chris Bevil is Principal, Global Cyber Resilience & AI, at Commvault.

More related posts


Readiverse-Featured-Image-888-x-500

Ready Is Good. Resilient Is Better.

Read more about Ready Is Good. Resilient Is Better.
Thumbnail_5_MV_Blogs_2025

Recovery Testing: The Missing Piece in Most Cyber Resilience Programs

Read more about Recovery Testing: The Missing Piece in Most Cyber Resilience Programs
Urgent-Need-for-Cyber-Resilience

The Urgent Need for Cyber Resilience

Read more about The Urgent Need for Cyber Resilience
Thumbnail_Blog_Modern-Playbook-2025

Your Modern Playbook for Rapid Response and Clean Recovery

Read more about Your Modern Playbook for Rapid Response and Clean Recovery

Puntos Clave

  • Commvault’s data access governance, powered by Satori, unifies visibility, access control, and auditability across structured data, unstructured files, SaaS apps, and AI workloads.
  • Una política de acceso única y coherente puede regir tanto a los usuarios humanos como a los modelos de IA, lo que ayuda a reducir los silos y a limitar la sobreexposición de los datos sensibles.
  • La detección, clasificación y evaluación continua de riesgos ayudan a ofrecer información priorizada sobre dónde se encuentran los datos confidenciales y dónde es mayor el riesgo de exposición.
  • El enmascaramiento y la ocultación dinámicos basados en políticas ayudan a garantizar el acceso con el mínimo privilegio, lo que permite el uso autorizado de los datos y, al mismo tiempo, contribuye a proteger los campos confidenciales.
  • Los registros de auditoría centralizados y casi en tiempo real ofrecen una visibilidad completa de las consultas de los usuarios, las indicaciones de la IA y los eventos de acceso regulado, lo que ayuda a garantizar el cumplimiento normativo y la rendición de cuentas.

With AI now embedded in every workflow, from copilots and chat assistants to analytics tools, all these endpoints have become ravenous for data to ingest. Commvault’s Las funciones de gobernanza del acceso a los datosde Commvault, con tecnología de Satori, están diseñadas para sacar más partido a esa IA tan ávida de datos, unificando la visibilidad, el control de acceso y la auditabilidad en todo tu entorno de datos.

Una base unificada para la gestión de datos en la era de la IA

Commvault’s data access governance features bring structured databases, unstructured files in SaaS apps, and AI workloads under one governance model, instead of treating them as separate silos. Organizations now can apply a single access policy to both human users and AI models, so that the same rules determine who or what can see sensitive information, regardless of where it lives.

By integrating Satori into the Command Center de Commvault, these capabilities extend Commvault’s traditional protection into live data and AI usage, not just backups and snapshots. This helps security and data protection teams move from reactive incident response to proactive control over how data is discovered, accessed, and used in real time.

Detección, clasificación y evaluación de riesgos continuas

Uno de los pilares fundamentales de nuestras capacidades de gobernanza de datos esla detección y clasificación unificadasde los datos en todas las nubes y SaaS. A medida que las organizaciones se conectan a entornos como AWS, Azure, Google Cloud, Snowflake, Databricks y otros, Commvault mapea automáticamente los almacenes de datos y los clasifica de forma continua, tanto si los datos son estructurados como no estructurados.A cada activo se le asigna una puntuación de riesgo, lo que ofrece a los equipos una visión priorizada de dónde se encuentra la información sensible y dónde es más probable que haya exposición. En lugar de depender de análisis periódicos, la platform al movimiento de datos, a los nuevos almacenes y a los cambios de clasificación, lo que ayuda a los equipos a detectar problemas antes y a centrarse primero en las áreas de mayor riesgo.

Acceso con privilegios mínimos mediante enmascaramiento dinámico y censura

Traditional data protection often stops at knowing where sensitive data is; Commvault’s capabilities emphasize controlling how that data is revealed. Using policy-driven masking and redaction, organizations can enforce least-privilege access so that users, services, and AI models only see the specific information they are authorized to see, with sensitive fields anonymized or hidden as needed.

Because the same masking and redaction policies apply across all connected environments, organizations can consistently safeguard access instead of fragmented, application-by-application rules. This helps reduce the risk of data overexposure, where too many people or systems have access to more data than they legitimately need.

Seguridad y gestión rápida y segura

A standout capability is policy-driven AI security that operates at the prompt and response level. Before data is ever sent to an AI model, Commvault, powered by Satori, can intercept the interaction, detect sensitive fields (such as regulated personal details), and apply inline masking or redaction according to existing data access policies.

Unlike solutions that simply block entire prompts or rely solely on downstream data loss prevention (making security someone else’s concern), this approach allows employees to keep using AI assistants productively while keeping sensitive data under governance. Because redaction occurs before the model processes the data, it also helps prevent sensitive information from influencing or contaminating AI training datasets, protecting both the users and the broader AI environment.

Los registros de auditoría centralizados facilitan el cumplimiento normativo

The final piece of our Las funciones de gobernanza del acceso a los datos is un registro de auditoría completo y centralizado. Every interaction – whether a user query, an AI prompt, or a governed access event – is captured with details such as who accessed what, which policy was applied, and what redactions occurred, in near–real time.

This unified audit visibility spans live data, AI prompts, and access governance events, giving security, IT, and compliance leaders a single authoritative record rather than disparate logs from point tools. For CISOs and CIOs, this means faster compliance reviews and clear proof that governance is not just documented on paper but actively enforced across the environment.

Ayudamos a las organizaciones a implementar la IA de forma segura

En conjunto, estas nuevas funciones ofrecen a las organizaciones una forma coherente de gestionar los datos en un mundo impulsado por la IA: visibilidad unificada en la nube, SaaS e IA; una única política para usuarios y modelos; enmascaramiento y censura dinámicos para un acceso con privilegios mínimos; y protección de las indicaciones de la IA basada en políticas y respaldada por registros de auditoría completos. El resultado es un cambio de los controles reactivos a una gobernanza proactiva del acceso a los datos preparada para la IA, lo que ayuda a los equipos a adoptar la innovación en IA sin perder el control sobre su información más sensible.

Preguntas frecuentes

Q: What makes Commvault’s approach to AI data governance different from traditional data protection?

A: Traditional data protection often focuses on backups and incident response after exposure occurs. Commvault extends governance into live environments and AI interactions, helping enable proactive control over how data is discovered, accessed, and used in real time. This shift helps organizations manage risk before it becomes a breach.

Q: How does la detección y clasificación unificadas improve security?

A: Continuous discovery and classification automatically map and label structured and unstructured data across clouds and SaaS platforms. By assigning risk scores to each asset, teams gain a prioritized view of sensitive data exposure. This helps enable faster identification of high-risk areas and more focused remediation efforts.

Q: What is dynamic masking, and why is it important for AI workloads?

A: Dynamic masking and redaction limit what users, services, and AI models can see based on predefined policies. Sensitive fields can be anonymized or hidden while still allowing legitimate access to relevant data. This approach supports productivity while helping reduce the risk of overexposure.

Q: How does policy-aware AI prompt protection work?

A: Policy-aware AI security intercepts prompts and responses before data reaches the AI model. It helps detect sensitive information and apply inline masking or redaction according to existing policies. This helps employees continue using AI tools while helping keep regulated data under governance and out of training datasets.

Q: How do centralized audit trails support compliance efforts?

A: Comprehensive audit logging captures details about who accessed what data, which policies were applied, and what redactions occurred. This unified visibility spans live data and AI interactions, helping give security and compliance leaders a clear, authoritative record. It helps enable faster reviews and demonstrate that governance controls are actively enforced.

Q: How do these capabilities help organizations adopt AI safely?

A: By combining unified visibility, consistent policy enforcement, dynamic masking, and complete audit trails, Commvault’s data governance capabilities help give organizations a cohesive framework for governing AI-era data. These controls help enable innovation while helping maintain control over sensitive information. The result is a more confident and safe path to AI adoption.

Nico Guerrera is Senior Technical Marketing Manager at Commvault.

More related posts


Social_Blog_Satori_GigaOm_Leader_2026_Linkedin

Satori Named Leader in GigaOm’s Data Access Governance Radar Report

Read more about Satori Named Leader in GigaOm’s Data Access Governance Radar Report
Thumbnail_Blog-Conversational-Resilience-2025-Linkedin

Conversational Resilience: The New Way to Manage and Protect Enterprise Data

Read more about Conversational Resilience: The New Way to Manage and Protect Enterprise Data
Thumbnail_Blog_Satori-Acquisition-2025

Commvault Closes Acquisition of Satori, Strengthening Data and AI Security Platform

Read more about Commvault Closes Acquisition of Satori, Strengthening Data and AI Security Platform
Thumbnail_Blog-Data-Rooms-2025-Linkedin

Data Activate: Unlocking the Power of Trusted Data for AI Innovation

Read more about Data Activate: Unlocking the Power of Trusted Data for AI Innovation

Puntos Clave

  • La infraestructura de identidad es una superficie de ataque clave que, si se ve comprometida, puede paralizar las operaciones de la empresa.
  • Commvault’s vulnerability assessment helps highlight misconfigurations and risky settings through clear exposure indicators and remediation guidance.
  • Real-time auditing helps enable teams to detect subtle malicious changes as they happen and trace attacker activity in real time.
  • One-click rollback can aid in rapid reversal of unauthorized changes, helping minimize downtime and limit attack spread.

Cybersecurity and the Importance of Identity

When most people think about cybersecurity, they picture stolen files or encrypted databases. But there’s a layer underneath all of that which, if compromised, makes everything else irrelevant – your identity infrastructure.​

Identity management systems like Directorio Activo(AD),Entra IDyOkta are the systems that decide who gets to log in, what they can accessywhether your business can function at all. When attackers get in there, users can’t authenticate, applications go darkyoperations grind to a halt. It’s not a data problem at that point, it’s a control problem.​

Automated forest recovery with clean OS rebuilds helps enable organizations to restore identity systems securely without reintroducing threats. Here’s how.

Know What You’re Vulnerable to Before the Attackers Do

Commvault’s vulnerability assessment gives your AD environment a posture score.  Think of it like a health grade for your directory. Most environments have more exposure than people realizeythis makes that visible.​

Our tool helps surface indicators of exposure (IOEs), which are specific misconfigurations or risky settings that could be exploited. One common example is accounts with passwords set to never expire. Stale, non-rotating credentials are one of the most common ways attackers maintain long-term access to an environment.

Commvault doesn’t just flag the issue, it helps identify which accounts are affected, walks through remediation stepsylets you export the list to help simplify scripting the fix.

Catch It While It’s Happening

Knowing your weaknesses is step one. Seeing when someone is actively exploiting them is step two.

Commvault’s identity management auditing helps capture a real-time feed of every change made to identity systems like Directorio Activo and Entra ID – details like who made the change, when, from whereywhat the values looked like before and after.

Attackers don’t usually blow the doors off; they make subtle, targeted changes. A compromised account might create a backdoor user, quietly add it to domain admins, then link a malicious Group Policy Object (GPO) designed to deploy ransomwareyevery one of those steps shows up in the audit feed.​

Once you spot a suspicious account, filtering can help you instantly pull up every change that account ever made, helping give you the full picture of what the attacker touched.​

Undo the Damage Fast

Detection only matters if you can act on it. From the same auditing view, you can roll back a malicious change with a single click, helping restore the environment to its last known good state without jumping between tools or writing a custom script. The aim is to help minimize downtime and limit how far the attack spreads before it is caught.​

When the Worst Happens: Forest Recovery

Sometimes an attack gets throughyyou need to rebuild from scratch. AD forest recovery, rebuilding your entire directory environment after a ransomware hit, is notoriously complex, often involving 50 to 100+ individual steps, depending on how many domains and domain controllers you have.​

Commvault helps automate this with orchestrated runbooks that sequence every step: Rebuilding domain controllers in the right order based on their flexible single master operation (FSMO) roles, restoring SYSVOL, verifying metadatayre-establishing trust between domains. A topology view of the entire AD forest helps make it visually clear which domain controllers should come back online first.​

The standout piece here is what Commvault calls Clean OS Recovery. Instead of restoring potentially compromised virtual machines, it rebuilds domain controllers on brand-new VMs. Restoring an infected machine risks bringing the malware right back with it. Recovering onto fresh infrastructure means you’re not just getting your data back; you’re actually starting clean.​

One Dashboard for On-Premises and Cloud

Most organizations today aren’t running purely on-premises or purely in the cloud, they’re hybrid, with AD handling legacy access and Entra ID handling modern cloud-based identities. Commvault’s unified control plane can help cover both from a single console: assessments, auditing, detectionyrecovery across both platforms.​

The value is straightforward: fewer tools, less complexityya cleaner story to tell leadership when they ask how identity infrastructure is being protected end to end.​

Identity resilience deserves its own dedicated conversation, separate from making backups and separate from protecting endpoints. The combination of proactive vulnerability scanning, real-time change auditing, fast rollbackyclean forest recovery helps your organization treat your directory infrastructure as a security priority in its own right.

Preguntas frecuentes

Q: Why is identity infrastructure such a critical security focus?

A: Identity systems control authentication and access across an organization. If compromised, attackers can disrupt operations entirely, making other security measures irrelevant.

Q: What are indicators of exposure (IOEs)?

A: IOEs are specific misconfigurations or risky settings in identity environments that attackers can exploit. Discovering them can provide visibility into weaknesses and help guide teams on how to fix them.

Q: How does real-time auditing help stop attacks?

A: Real-time auditing helps track every change in identity systems, including who made it and what changed. This visibility helps security teams detect suspicious behavior early and investigate the full scope of an attack.

Q: Can malicious changes really be undone quickly?

A: Yes, Commvault can help enable direct rollback of unauthorized changes from the same interface. This helps reduce response time and restore systems to a safe state without complex scripting.

Q: What makes AD forest recovery so challenging?

A: Rebuilding an AD forest involves many interdependent steps, including restoring domain controllers and reestablishing trust relationships. The complexity increases with the size of the environment.

Q: What is Commvault’s Clean OS Recoveryywhy does it matter?

A: Clean OS Recovery helps rebuild domain controllers on new, uncompromised systems instead of restoring infected machines. This approach helps eliminate lingering malware and can help enable a secure recovery.

Nico Guerrera is Senior Technical Marketing Manager at Commvault.

More related posts


Thumbnail_Blog-Okta-Early-Access-2026

Commvault® Extends Identity Resilience to Okta

Read more about Commvault® Extends Identity Resilience to Okta
Thumbnail_Blog-Lateral-Access-2026

Staying Resilient Against Lateral Access Exploits

Read more about Staying Resilient Against Lateral Access Exploits
Thumbnail_Blog-Linkedin 1

Security Best Practices

Read more about Security Best Practices

Puntos Clave

  • Managing backup and recovery as Infrastructure as Code (IaC) helps reduce configuration drift and align data protection with modern cloud deployment practices.
  • The Clumio Terraform provider helps enable AWS accounts, policies, and protection rules to be defined declaratively and version-controlled.
  • Tag-based protection is designed to automatically protect existing and future resources, helping reduce manual intervention and scale efficiently across environments.
  • Defining backup policies in Terraform helps improve visibility, reproducibility, and governance through standard pull request workflows.
  • This approach can be especially valuable for multi-account AWS environments and organizations already standardized on Terraform.

Cloud infrastructure is increasingly defined as code. EC2 instances, identity and access management (IAM) roles, virtual private clouds, and databases now live in version-controlled repositories and are deployed predictably through IaC.However, backup and recovery policies often are still configured manually in web consoles. That gap creates risk. When infrastructure is declarative but data protection is not, teams risk:

  • Configuration drift.
  • Inconsistent protection across accounts.
  • Manual errors.
  • Limited visibility into what is actually protected.

For organizations already using Terraform, backup and recovery should be managed the same way as the rest of the stack – through code.Clumio’s Terraform provider enables AWS data protection to be defined declaratively alongside infrastructure. You can explore the provider and its documentation here: https://registry.terraform.io/providers/clumio-code/clumio/latest/docs/guides/getting_started.In this post, we’ll walk through how to automate AWS workload protection using Terraform and Clumio de Commvault – and why that approach scales more effectively for modern cloud teams.

The Problem with Console-Based Backup Configuration

In a traditional setup, protecting AWS resources requires:

  • Connecting AWS accounts.
  • Configuring protection separately across multiple AWS services.
  • Creating backup policies.
  • Defining protection rules.
  • Manually assigning resources.
  • Repeating that process for each account or environment.

Even in well-run environments, this creates:

  • Repetitive manual configuration.
  • Inconsistent policy application.
  • Delayed protection for newly created resources.
  • Limited version control.

Terraform already helps solve this problem for infrastructure. The Clumio Terraform provider extends that model to data protection.

From Zero to Protected – Using Four Files

Protecting multiple AWS services can be defined using a small set of Terraform files rather than a sequence of manual UI steps.

The configuration follows a straightforward structure.

  1. Define Providers (AWS + Clumio)

The first step is declaring the providers.Terraform needs to know:

  • You’re using AWS.
  • You’re using the Clumio provider.

This connects Terraform to both platforms.The official provider documentation walks through this setup in detail in theCómo empezar guide.

  1. Connect AWS Accounts to Clumio

Next, the Clumio module establishes the connection between AWS and Clumio. This abstracts away the IAM role configuration required for data protection. Instead of manually configuring roles and permissions, the module handles the integration in a repeatable way.The provider source code is publicly availableon GitHub.This means your integration is defined in code, version-controlled and reproducible across environments.

  1. Define Backup Policies as Code

Backup policy definition is where IaC shines. In a Terraform-based configuration:

  • Different recovery point objectives can be set for different resource types.
  • Multiple retention tiers can be defined within the same policy (for example, short-term and long-term retention).
  • The same policy can apply automatically based on defined conditions.

Instead of navigating multiple consoles, a single Terraform configuration defines frequency, retention, and resource scope. That policy is reusable and reviewable like any other infrastructure configuration.

  1. Tag-Based Automatic Protection

One of the most scalable elements of the approach is tag-based protection. A protection rule can be configured to automatically protect any resource tagged with a specific key/value pair. For example:

created_by = demo_script

This means:

  • Existing resources matching the tag are protected.
  • Future resources with that tag are automatically included.
  • No manual intervention is required.

For S3 specifically, protection groups also use tags to manage hundreds of buckets as a single logical unit, allowing centralized policy changes at scale. This helps reduce configuration drift.

Applying the Configuration

Once defined, Terraform initializes the working directory, previews planned changes, and applies the configuration. Terraform is designed to respect dependencies between resources, creating them in the correct order.The configuration helps connect AWS accounts, activate policies, enforce protection rules, and protect tagged resources. And critically – the entire protection strategy exists in version-controlled code.

Why This Matters for Cloud Architects

For teams operating with IaC principles, backup configuration should follow the same discipline as infrastructure provisioning.Defining backup in Terraform provides several practical benefits:

  • Version control: Backup policies are defined in code and can be reviewed, versioned, and approved through standard pull request workflows.
  • Reproducibility: The same configuration can be deployed consistently across development, staging, and production accounts.
  • Reduced drift: Terraform configurations can be re-applied to enforce the declared state, helping bring manual or out-of-band changes back in line with the intended configuration.
  • Clear visibility: Protection logic is visible in code rather than buried in UI configuration.
  • Separation of configuration and interface: Backup posture is defined declaratively, not dependent on console state.

When This Approach Makes Sense

Automating backup with Terraform is particularly useful for:

  • Multi-account AWS environments.
  • Regulated industries requiring auditable configuration.
  • Platform teams managing shared infrastructure.
  • Organizations already standardized on Terraform.

If your infrastructure is defined as code, your data protection strategy should be too.

Cómo empezar

To explore this approach further:

You also can evaluate Clumio through theAWS Marketplace.

Preguntas frecuentes

Q: Why should backup policies be managed as code?

A: When infrastructure is defined as code but backup policies are configured manually, gaps and inconsistencies can emerge. Managing backup as code helps align protection with deployment workflows, reduce manual errors, and provide version-controlled visibility into your data protection strategy.

Q: What does the Clumio Terraform provider enable?

A: The Clumio Terraform provider allows AWS data protection resources – such as account connections, backup policies, and protection rules – to be defined declaratively. This helps enable teams to manage backup configurations alongside infrastructure in the same Terraform workflow.

Q: How does tag-based protection improve scalability?

A: Tag-based protection is designed to automatically apply policies to any resource that matches a specified key/value pair. This helps protect existing and future resources without manual assignment, helping make it easier to manage protection at scale across accounts and services.

Q: How does Terraform help reduce configuration drift in backup environments?

A: Terraform maintains a declared state for infrastructure and protection policies. Reapplying configurations helps bring manual or out-of-band changes back in line with the intended state, helping improve consistency across environments.

Q: In what scenarios does automating backup with Terraform make the most sense?

A: This approach is particularly beneficial in multi-account AWS environments, regulated industries requiring auditable configurations, platform teams managing shared services, and organizations already using Terraform as a standard for IaC.

Q: How can teams get started with Terraform-based AWS data protection?

A: Teams can begin by reviewing thedocumentación del proveedor de Clumio para Terraform, exploring theprovider’s GitHub source code, and watching the Quick Start demo. Evaluating Clumio through theAWS Marketplaceis also a practical next step.

Lawrence Chang is Chief Engineering Officer of Clumio and Vir Choksiis Principal Product Marketing Manager at Commvault.

More related posts


Thumbnail_Blog-GoogleWorkspace-2026

How the Move to Clumio Delivered 66.7% Savings on AWS Backups

Read more about How the Move to Clumio Delivered 66.7% Savings on AWS Backups
Thumbnail_Blog_AWS-Marketplace-AI

Commvault Featured in New AI Agent Solutions in AWS Marketplace

Read more about Commvault Featured in New AI Agent Solutions in AWS Marketplace
Man-and-woman-working-on-laptops-profile-Crocus-Thumbnail

Protecting Your Amazon S3 Data with Clumio: A Comprehensive Solution

Read more about Protecting Your Amazon S3 Data with Clumio: A Comprehensive Solution
Zz05MThhZTc3NmU0MTQxMWVmYTYwZWJlYTg2ZTllNjQ5Yw

A Blueprint for Effective Cloud Recovery

Read more about A Blueprint for Effective Cloud Recovery

Clumio

Read more about Clumio

Every organization that has ever failed a recovery – and there are more than anyone publicly acknowledges – had one thing in common: They believed they could recover before they tried.

The belief came from somewhere. A completed tabletop exercise. A backup system that showed green. An annual disaster recovery test that passed. All of it documented. All of it, at some point, accurate. None of it current when the incident actually hit.

This is the confidence gap. And it is the gap that continuous recovery validation is designed to close.

What ‘Testing’ Actually Means in Most Organizations

Si le preguntas a la mayoría de los responsables de seguridad o de TI con qué frecuencia comprueban su capacidad de recuperación, la respuesta suele ser «una vez al año», a veces «dos veces al año». La prueba consiste en restaurar un subconjunto de sistemas a partir de backup un entorno de pruebas, comprobar que se inician correctamente y elaborar un informe. A veces se realiza también un ejercicio de simulación junto con ello. Lo que este tipo de pruebas no hace: validar que los datos de la copia de seguridad estén libres de malware. Confirmar que la secuencia de recuperación funciona para servicios interdependientes. Probar la recuperación de identidades, algo esencial cuando el ataque se ha producido a raíz de credenciales comprometidas. Confirmar que el equipo que llevaría a cabo la recuperación conoce los manuales de procedimientos actuales. Ni aportar pruebas lo suficientemente significativas como para convencer a un regulador, un auditor o un consejo de administración de que la capacidad de recuperación es real y está al día. En resumen, valida un momento concreto. Las operaciones de resiliencia (ResOps) requieren que la validación sea un estado continuo.

El modelo de validación continua

Continuous recovery validation is not a single test run more frequently. It is a set of integrated practices that produce ongoing, evidence-based proof of recoverability across critical services.

Automated backup integrity scanning. Every backup, continuously evaluated for anomalies, encryption patterns, and malware signatures. Not at restore time – before restore time. The goal is to know whether your recovery points are clean before you need them, not during an incident.

Scheduled Cleanroom Recovery drills. Bi-annual at minimum, restoring from immutable backup points into an isolated Cleanroom Recovery environment – not production, not a production-adjacent test environment, but a genuinely isolated space where forensic analysis can happen without risk of reinfection. These drills produce documented evidence of recoverability against defined impact tolerances.

Identity recovery validation. With el uso indebido de credenciales es el vector de ataque más habitual, Active Directory and Entra ID recovery must be tested alongside data recovery. Organizations that restore systems without restoring a verified-clean identity layer may find attackers re-enter through the same door.

Service Resilience Indicator (SRI) dashboards. SRIs – continuous signals drawn from backup telemetry, dependency mapping, and test results – that give CISOs, CIOs, and boards a live view of recoverability posture. Not a point-in-time report. An ongoing operational signal.

Each of these practices feeds what Deloitte and Commvault call the resilience backlog: a continuously updated, prioritized list of gaps identified through testing and tracked to resolution. It is the mechanism by which validation drives improvement rather than just producing reports.

¿Qué significa el «tiempo medio hasta la recuperación de la limpieza»?

Traditional recovery metrics – recovery time objective (RTO) and recovery point objective (RPO) – measure speed and data recency. They say nothing about whether the data being restored can be trusted. Mean Time to Clean Recovery (MTCR) fills that gap: It measures the time required to restore data that is verifiably clean, not just technically available.

MTCR matters because in a ransomware incident, the adversary’s goal is often to corrupt recovery options, not just encrypt production systems. An organization that restores quickly but restores from a compromised backup has not recovered. It has re-infected itself.

Building MTCR into your resilience measurement framework, alongside RTO and RPO, changes what you optimize for and what you report to the board. Speed plus recency plus integrity: that is the complete picture of recovery readiness.

Resiliencia que puedes demostrar

The organizations that navigate cyber disruptions with the least damage share one characteristic: They treat recovery capability as something to be continuously demonstrated, not periodically asserted. They know their MTCR. Their SRIs are current. Their cleanroom recovery has been tested in the last 90 days.

That posture is not the result of better technology alone. It is the result of an operating discipline – ResOps – that makes resilience continuous, measurable, and governable. Commvault’s platform provides the technical foundation: clean recovery, automated validation, and the unified visibility across data, identity, and services that ResOps requires at scale.

For the organizational side of that equation – how to define impact tolerances, align executive leadership, and build the governance structure that sustains the discipline – see the Deloitte companion blog, «La conversación sobre resiliencia que tu consejo de administración aún no está manteniendo. And for the complete ResOps framework, including the six ResOps domains and the measurement model that ties technical recoverability to board-level accountability, read the joint whitepaper:«De la viabilidad mínima a la resiliencia operativa: ResOps en la práctica.Bill O’Connell is Chief Security Officer at Commvault.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

cloud suponía quecloud noscloud a dar flexibilidad, además de:

  • Servicios de primera categoría.
  • Innovación Cloud.
  • Sin dependencia de un proveedor concreto.

But when a cyber incident hits, that flexibility often becomes complexity.
In this episode of STRIVE, I sat down with Senior Director of Product Management Akshay Joshi – whose career spans IBM, AWS, Microsoft, Clumio, and now Commvault – to unpack one uncomfortable truth: Most organizations think they’re ready for multi-cloud recovery.
Until they’re not. Watch the episodio completo.

Puntos clave: Lo que realmente exigeCloud

  • Backup at the service level doesn’t equal recovery at the application level. Protecting individual data sources is not the same as restoring a synchronized application ecosystem.
  • Recovery complexity multiplies across clouds. Different recovery points, different accounts, different admin teams – each adds friction when time matters most.
  • Native hyperscaler tools are necessary – but not sufficient. They protect within their own cloud but don’t orchestrate across clouds.
  • Isolation is the first domino in a cyber event. The larger the environment’s aperture, the harder it is to contain impact.
  • Resilience must be designed in – not retrofitted later. Dependency mapping and recovery planning should begin at application design, not after deployment.
  • AI-enabled automation adds power – and new risk. Agentic workflows require tight permission controls and governance discipline.

The Gap Between “On Paper” and Reality

On paper, recovery seems simple: When do you recover to? What do you recover? Where do you recover it?

But, as Akshay explains, each of those questions fractures in a multi-cloud world. Different services may have different recovery points. Some microservices may be impacted while others aren’t. Recovery may require re-architecting if restored cross-regionally or cross-account.
What looks straightforward in documentation becomes deeply complex in execution. And when ransomware hits, teams don’t calmly reference playbooks – they scramble.

La primera ficha de dominó: el aislamiento

Each threat vector expands proportionally with environmental complexity. Multi-cloud doesn’t just diversify infrastructure – it expands operational aperture.

Copia de seguridad a nivel de servicio frente a recuperación a nivel de aplicación

Here’s where most organizations get caught.
They back up:

  • Datos de Azure con Azure Backup
  • Datos de AWS con AWS Backup
  • Cloud de Google Cloud con una herramienta independiente

Individually, each service may be protected. Collectively, the application may not be recoverable in a synchronized state.
Native tools don’t communicate across clouds. They aren’t inherently multi-cloud in orchestration. They aren’t tuned to optimize recovery time objective (RTO) or recovery point objective (RPO) at scale for cross-cloud architectures.
And when recovery depends on aligning multiple data sources across hyperscalers, orchestration becomes the difference between hours and days. This is exactly why unified recovery strategies exist – not to replace hyperscalers, but to coordinate them.

Dependency Mapping Isn’t Optional Anymore

We’ve been talking about application dependency mapping for more than a decade. But in a multi-cloud world, it’s no longer a “nice to have.” Applications now span multiple hyperscalers, multiple DevOps teams, multiple admin domains, and multiple vendor backup tools.
Fragmented ownership slows recovery. Vendor fragmentation complicates orchestration. Operational silos create delays at the worst possible time. Resilience must be operationalized from the beginning – not bolted on after deployment.

Avance: Por qué fallaCloud sin un mapa de dependencias

In this moment from the STRIVE conversation, Akshay explains why operationalizing resilience at the architecture stage is critical for surviving real-world cyber events.

Designing for Recovery – Not Just Protection

One of the most powerful points in this episode: Modern applications should be designed not only around performance and scale – but around recoverability. That means:

  • Estoy pensando tanto en el RTO como en el RPO.
  • Diseñar teniendo en cuentacloud .
  • Consolidar la visibilidad siempre que sea posible.
  • Reducir la fragmentación de proveedores y tareas administrativas.
  • Comprobación de la recuperación en distintos entornos.

Recovery speed impacts revenue. Recovery clarity impacts reputation. Downtime impacts customer trust. Multi-cloud innovation must be matched by multi-cloud recovery discipline.

La capa de IA y automatización

Ningún debate está completo sin abordar la IA. Los flujos de trabajo basados en agentes están cada vez más integrados en las plataformas SaaS empresariales. Pero la automatización plantea nuevas consideraciones:

  • ¿Qué permisos tienen los agentes?
  • ¿Con qué frecuencia se activan las copias de seguridad?
  • ¿Qué repercusiones económicas tienen las decisiones sobre automatización?
  • ¿Se consideran los agentes como identidades con acceso regulado?

AI can accelerate resilience – but without guardrails, it also can amplify risk. The key is controlled delegation.

¿Por qué tuvimos esta conversación en STRIVE?

STRIVE isn’t about repeating what everyone already knows. It’s about confronting the gaps that surface during real-world cyber events. Multi-cloud adoption isn’t slowing down. But unless recovery strategies evolve alongside architecture, complexity will outpace preparedness.
That’s why this discussion matters. And that’s why we brought Akshay in – someone who’s operated across hyperscalers and understands both their power and their limitations.

La conclusión más importante de este debate es que la criptografía poscuántica ya no es un reto tecnológico del futuro.

Se está convirtiendo en un debate sobre la resiliencia en el presente.

Las organizaciones no tienen por qué entrar en pánico ni necesitan renovar todos los sistemas de la noche a la mañana. Pero sí deben empezar a actuar, para aprovechar al máximo el tiempo del que disponen para prepararse.

Las organizaciones que superen con éxito esta transición no serán necesariamente aquellas que cuenten con la criptografía más sofisticada. Serán aquellas que hayan empezado a formarse una idea del tema antes de que llegara la certeza.

Y así es, a menudo, como funciona la resiliencia.

In the full STRIVE episode, you’ll discover:

  • La diferencia real entre backup a nivel de servicio backup la recuperación a nivel de aplicación.
  • Por qué el aislamiento es la primera ficha de dominó en los ataques de ransomware.
  • Cómo la fragmentación de los proveedores complica la orquestación.
  • En qué deben ponerse de acuerdo los CISO y los responsables de DevOps.
  • Cómo cambia la IA la ecuación de la resiliencia.

Ver ahora.
If you operate across AWS, Azure, or Google Cloud – this conversation is essential.

Preguntas frecuentes

Q: Why isn’t native hyperscaler backup enough?

A: Native tools protect data within a specific cloud but don’t orchestrate recovery across clouds. Multi-cloud applications require coordinated restoration across services and providers.

Q: What is the biggest gap in multi-cloud recovery?

A: The disconnect between how backups are made (service-by-service) and how recovery must happen (application-wide).

Q: What does “environmental aperture” mean?

A: It refers to the breadth of accounts, clouds, identities, and services in an environment. As aperture expands, risk and complexity increase proportionally.

Q: Why is dependency mapping critical?

A: Applications now span multiple clouds and teams. Without mapping service dependencies, recovery sequencing becomes guesswork.

Q: How does AI impact disaster recovery?

A: AI-enabled workflows can help automate backup and recovery decisions but require strong access controls, cost governance, and oversight.

Q: Where should organizations start improving multi-cloud recovery?

A: Begin by evaluating:

    • Alineación de la recuperación a nivel de aplicación.
    • Oportunidades de consolidación de proveedores.
    • Sincronización entre equipos.
    • Estrategia de aislamiento durante los incidentes.
    • Frecuenciacloud .

Chris Mierzwa is Senior Director, Portfolio Marketing, at Commvault.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Puntos Clave

  • Commvault Edge Docking for SaaS convertir la implementación en el borde en un proceso centralizado y cloud que se gestiona desde una única consola. Commvault Edge se conocía antes como HyperScale Edge.
  • La configuración automatizada y el aprovisionamiento mediante API ayudan a reducir el tiempo de implementación a unos pocos minutos en todas las sedes distribuidas.
  • Los flujos de trabajo estandarizados ayudan a mejorar la coherencia, la seguridad de los datos y la escalabilidad en los entornos periféricos.
  • SaaS continua SaaS permite realizar actualizaciones, mantenimiento y optimización de forma constante sin necesidad de intervención manual.
  • Las funciones de seguridad integradas, como las copias de seguridad inmutables y la arquitectura de confianza cero, ayudan a reforzar la protección frente a las amenazas en constante evolución.

La implementación de la protección de datos en el perímetro no debería requerir una configuración manual en cada sede. ConCommvault Edge Docking for SaaS, Commvault transforma la implementación en el perímetro en una experiencia optimizada y basada en la nube. Combina la potencia de Commvault Edge con el control centralizado del plano de gestión de SaaS.

Reducir la complejidad del despliegue en el borde

Los entornos de borde están en pleno auge.IDC prevé que el gasto en TI de borde alcanzará los 380 mil millones de dólares en 2028. Organizations are pushing compute closer to data – retail stores, branch offices, manufacturing plants, healthcare facilities – each generating and storing critical information that must be protected.

The current edge-setup process is resource-intensive, requiring physical access and time-consuming configuration steps. This extends deployment timelines and increases operational costs when scaling to multiple sites. What should take minutes can stretch into an extended period of time and potential complexity. And while organizations struggle with deployment logistics, critical edge data remains unprotected or inconsistently backed up across distributed locations.

The threat landscape doesn’t wait. Verizon’s documents a surge in breaches exploiting edge devices – and every unprotected site represents a potential entry point for ransomware, data theft, and business disruption.

SaaS para Commvault Edge

Commvault está contribuyendo a transformar la implementación en el perímetro conla integración SaaS para Commvault Edge (formerly HyperScale Edge) – a capability that brings cloud-native speed and simplicity to on-premises protection. From the Command Center, IT teams can configure, deploy, and manage every Commvault Edge system through a single SaaS console. It’s a single pane of glass that helps manage hybrid and cloud-native workloads across every site, device, and workload.

New systems follow a guided, standardized setup workflow that enables protected and consistent configuration from day one. Once powered on, each system automatically connects to Commvault SaaS, validates its configuration, registers with the platform, and begins installation. This helps minimize on-device setup and reduce the operational effort required to deploy at scale.

For larger rollouts, Commvault API-driven automation helps enable rapid onboarding of multiple systems simultaneously, supporting repeatable deployment across sites and regions.

Once systems are deployed, the global Command Center provides unified management across all locations. Each Commvault Edge system remains connected to Commvault SaaS for regular updates, maintenance, and optimization. From this single platform, you can deploy, patch, scale, and maintain every system with confidence. Deploy faster. Manage smarter. Protect data everywhere.

Creado para crecer, diseñado para ser sencillo

Commvault Edge Docking for SaaS is designed to deliver measurable operational advantages for IT and security leaders:

Accelerated time to value: Deploy new edge systems faster without manual, site-by-site provisioning.

Centralized visibility and governance: Manage configuration, monitor health, deploy updates, and scale infrastructure from a single SaaS management plane.

Reduced operational overhead: Limit the need for on-device configuration and streamline rollout processes, helping free IT resources for higher-value initiatives.

Consistent, rapid deployment: Standardized workflows help reduce configuration drift, deliver consistent data security posture and policy enforcement, and improve reliability across distributed environments.

Data security by design: Every system runs on , Commvault’s hardened Linux-native foundation. It’s a system that helps enable recovery that’s not just fast, but safe, with immutable local backups, multi-layer ransomware protection, and zero-trust architecture.

¿Por qué es importante esto?

Traditional edge deployments stretch across weeks or months when deploying at scale. Commvault Edge Docking for SaaS reinforces our commitment to delivering hybrid data protection with the speed and simplicity of SaaS, helping reduce operational costs, eliminate deployment bottlenecks, and achieve faster time to value.

But speed isn’t the only benefit. Consistency also matters. When every site deploys with the same protected baseline, compliance becomes more manageable. Automatic rollout of updates helps security posture stays current. And when recovery workflows are designed to work the same way everywhere, teams can respond confidently under pressure.

This is what unified resilience looks like at scale on the edge: Protection that deploys fast, is simple to manage, and helps provide reliable recovery across hundreds or thousands of distributed sites.

Míralo en acción

¿Estás listo para modernizar tu estrategia de implementación en el borde? Descubre más en nuestra páginaCommvault Edgey reserva una demostración para ver Commvault Edge Docking for SaaS acción, o ponte en contacto con tu representante de Commvault para saber cómo SaaS puede transformar tu estrategia de resiliencia en el borde.

Preguntas frecuentes

Q: What is Commvault Edge Docking for SaaS?

A: It is a Commvault capability that helps enable organizations to deploy and manage Commvault Edge systems through a centralized SaaS management plane. This approach helps simplify configuration, deployment, and ongoing operations across distributed environments.

Q: How does this solution reduce deployment complexity?

A: It helps eliminate the need for manual, site-by-site configuration by using automated workflows and centralized control. Systems can self-configure and connect to the SaaS platform, helping reduce setup time and effort.

Q: Can it scale across multiple locations?

A: Yes, API-driven automation helps enable rapid onboarding of multiple systems simultaneously. This makes it ideal for organizations managing hundreds or thousands of edge sites.

Q: What security features are included?

A: The solution runs on VaultOS™, which includes immutable backups, multi-layer ransomware protection, and a zero-trust architecture. These features help provide stronger, more resilient data protection at the edge.

Q: How does centralized management benefit IT teams?

A: IT teams gain a single pane of glass to monitor, update, and manage all edge systems. This helps improve visibility, reduce operational overhead, and maintain consistent policies across environments.

Q: Why is this important for modern edge environments?

A: As edge computing grows, traditional deployment methods become too slow and resource-intensive. This solution helps enable fast deployment, consistent data security, and reliable recovery, aiding organizations in keeping pace with scale and risk.

Justin Wolf is Senior Product Manager and Chad Bersche is Principal Product Manager at Commvault.


Blogs relacionados

More related posts


Thumbnail_Blog_HPE-Active-Peer-Persistence-2024-_1_

A Powerful Partnership for the Future of Data Resilience

Read more about A Powerful Partnership for the Future of Data Resilience
Thumbnail_Blog_Commvault-Cloud-2025-Linkedin

Elevate Your Cyber Resilience with Commvault Cloud Enhancements

Read more about Elevate Your Cyber Resilience with Commvault Cloud Enhancements

Artificial intelligence is redefining what’s possible for modern enterprises: accelerating innovation, sharpening decision-making, and unlocking new efficiencies at scale. Behind every AI-driven insight lies a physical reality—one powered by energy, infrastructure, and data.

As AI adoption grows, so does the need to efficiently manage and protect data at scale.
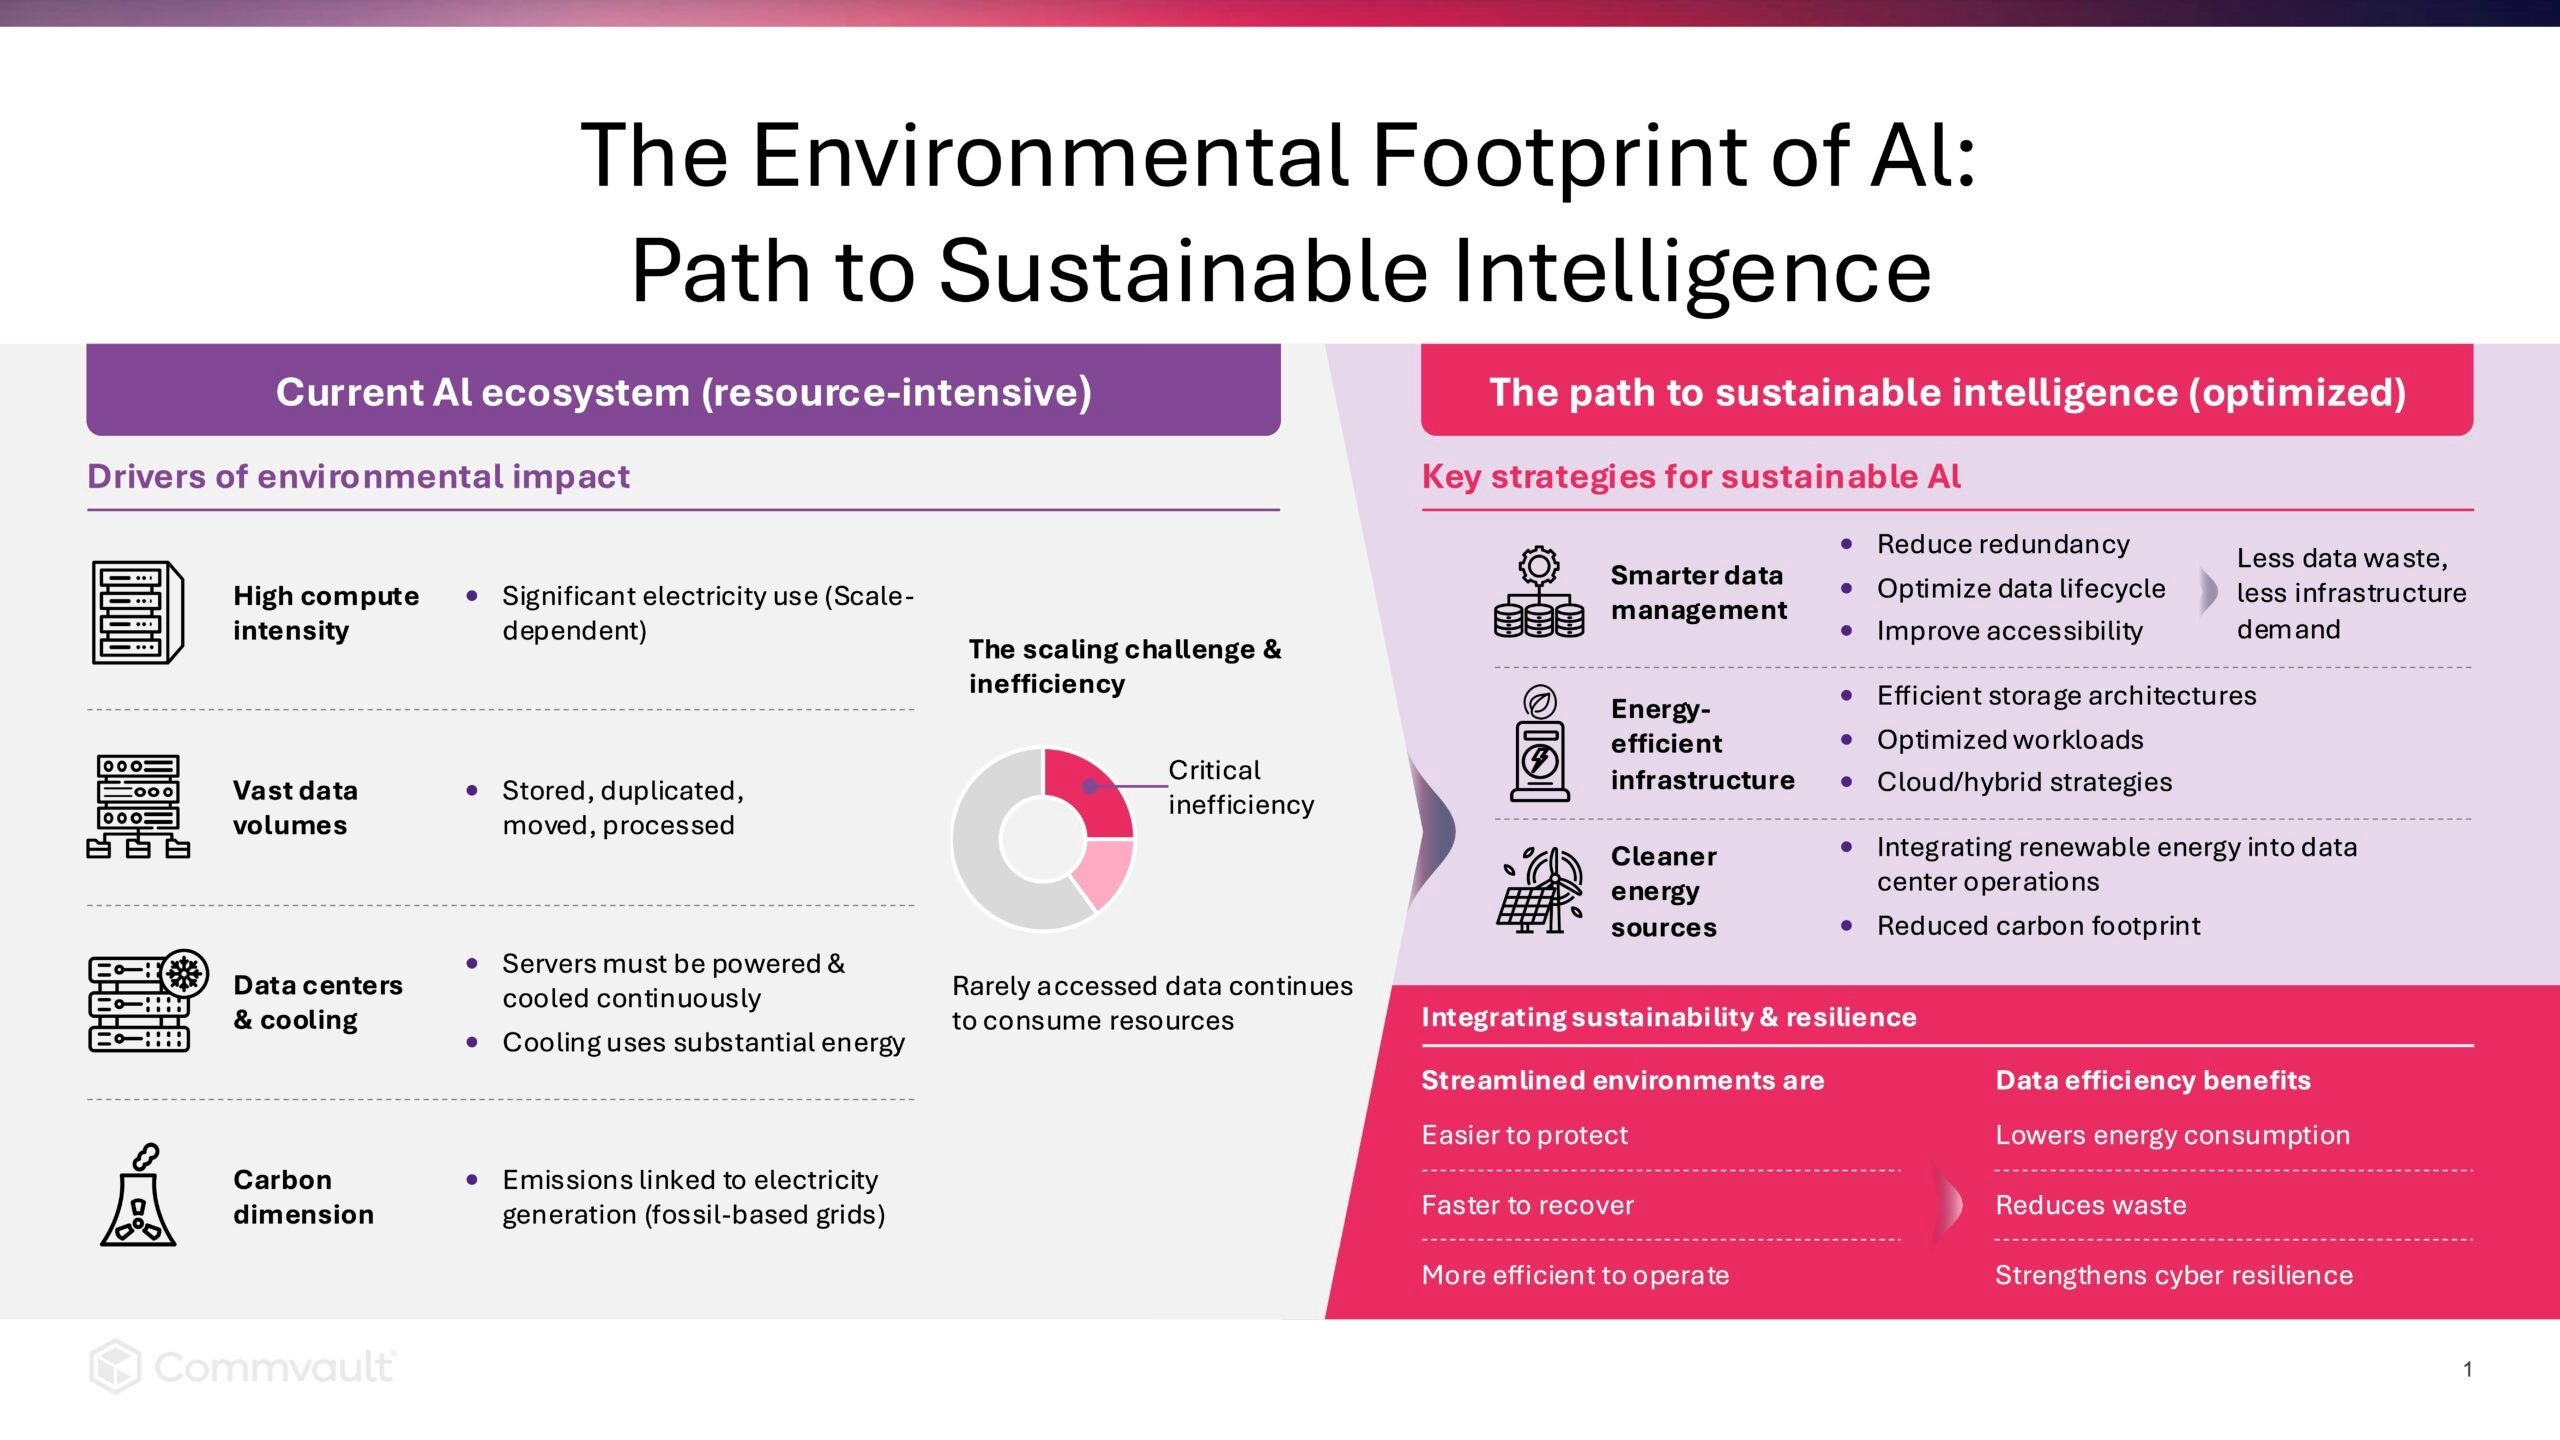
The future of AI will not be defined by intelligence alone, but by how responsibly that intelligence is built and sustained.

Tres factores clave que influyen en el impacto medioambiental

The environmental impact of AI is rooted in the compute infrastructure that powers it. Training and running AI models requires high-performance systems that consume electricity. But compute intensity is only part of the story.

AI depends on vast amounts of data—stored, moved, and processed across systems, each contributing to resource use.

All of this is supported by data centers, where servers must be powered and cooled. Cooling systems can represent a meaningful portion of energy use, making data infrastructure design a critical factor in AI sustainability.

Finally, the environmental impact of AI is influenced by how electricity is generated: the same workload can result in very different carbon emissions depending on the energy source.

Frenemos la ineficiencia, no la innovación

AI is scaling rapidly as organizations deploy it across functions, generate more data, and expand infrastructure to keep pace. A key inefficiency often goes unnoticed: half of enterprise data is never accessed after being stored.1Companies pay to store it without realizing value from it. This is where the environmental footprint of AI can expand—not through innovation, but through inefficiency.

Addressing this starts with better visibility and control over data.

Datos más inteligentes: una potente herramienta para la sostenibilidad

Como la IA se basa en grandes conjuntos de datos, las empresas pueden ayudar a reducir el impacto medioambiental corrigiendo las prácticas ineficientes en el manejo de datos que generan cargas de trabajo innecesarias. Las soluciones de Commvault ofrecen varias funciones que ayudan a las empresas a gestionar y aprovechar los datos de forma eficiente:

  • Deduplication to remove redundant data
  • Tiering to align storage and processing with access needs
  • Compression to reduce storage requirements

Una gestión consciente de los datos ayuda a mejorar la eficiencia y a reducir el consumo de recursos.

Sostenibilidad y resiliencia: las dos caras de una misma estrategia

Data environments filled with redundant and unorganized data are not only energy-intensive, they are also harder to secure, govern, and recover. Complexity increases risk and complicates business continuity plans.

By helping organizations manage, protect, and leverage their data, Commvault supports systems that are both resilient and sustainable. Smarter data management can help reduce waste, improve efficiency, and strengthen cyber resilience.

El camino a seguir

El futuro de la IA dependerá de las decisiones que tomen hoy las organizaciones. Los líderes en este ámbito:

  • Treat data as a strategic asset—not just a growing volume
  • Diseña sistemas de IA teniendo en cuenta la eficiencia y la gestión del ciclo de vida
  • Incorporar la resiliencia en todos los niveles de sus operaciones

With smarter data management, optimized infrastructure, and responsible design, organizations can reduce the environmental impact of AI—while unlocking its full potential.

Less waste. More resilience.


1El estado de los datos ocultos

Aakanksha Kashyap is ESG Specialist at Commvault.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Puntos clave:

  • Los ciberataques se dirigen cada vez más tanto a backup de producción como a backup , por lo que es fundamental contar con una recuperación limpia y verificable.
  • La detección integrada de anomalías y amenazas refuerza la resiliencia cibernética al identificar datos comprometidos, validar puntos de recuperación fiables y acelerar la restauración.
  • Cuando se integran en los flujos de trabajo de protección de datos, las funciones de detección de anomalías y amenazas pueden ayudar a proporcionar las pruebas necesarias para recuperarse de forma rápida, segura y con confianza.

Por qué la ciberresiliencia depende de la detección integrada de anomalías y amenazas

Anomaly detection identifies unusual behavior in backup data that may indicate compromise. Threat detection identifies known malicious activity using signatures, heuristic analysis, and scanning techniques. Together, they help validate recovery points and enable clean data recovery.

For years, security leaders focused on preventing breaches. In today’s era of persistent attacks and AI-driven threats, organizations increasingly assume compromise and design systems that can withstand disruption and recover safely when it occurs.

Modern adversaries don’t always hide their presence – they reveal it when it serves their objective. Attackers try to infiltrate environments quietly, observe systems over time, and position themselves inside critical infrastructure. The moment an attack becomes visible is rarely the moment it begins; it is the moment the attacker chooses to act.

By then, compromised data may already be woven into backup copies. Integrated anomaly and threat detection can help organizations identify compromised backup data, validate clean recovery points, and assist recovery after a cyberattack.

For security and IT teams, the challenge is no longer simply detecting an attack but predicting and managing an attacker’s possible impact. Understanding what was affected, what remains trustworthy, and how the organization can recover safely without escalating business disruption is the solution.

This is why cyber resilience benefits tremendously from integrated anomaly and threat detection. When detection capabilities are embedded into data protection and recovery workflows, they help provide the shared intelligence that teams need to identify compromised data, validate trusted recovery points, and guide response decisions with evidence rather than guesswork.

This approach aligns with the emerging ResOps™ operating model, que está en auge, en el que los equipos de seguridad, TI y recuperación trabajan partiendo de una visión global compartida y de rutas de recuperación validadas para responder juntos a los incidentes.

La nueva realidad: la recuperación requiere pruebas, no suposiciones

Traditional threat detection tools focus on spotting threats along the perimeter. But once attackers are inside, visibility can become fragmented and determining which systems and data have been affected becomes a challenge.

Further, attackers increasingly target backup environments specifically to undermine recovery. And the moment organizations cannot confidently prove that backups remain untouched, suspicion becomes unavoidable. The result is uncertainty. Restore quickly and risk reinfection? Or delay recovery while investigating which copies remain trustworthy? IT teams are forced to guess which data is safe while downtime accumulates.

By building intelligence directly into data protection workflows, anomaly and threat detection helps transform recovery from a reactive guess into a disciplined, evidence-driven process. These capabilities can help organizations pinpoint tampered copies, validate data cleanliness, and assemble the most recent uncompromised recovery points – helping you accelerate cyber recovery and reduce operational impact.

Detección de anomalías: tu primera señal de lo desconocido

Anomaly detection acts as a sentinel, guarding your protected data integrity. It establishes a baseline of normal behavior – file sizes, growth patterns, deduplication changes, access attempts – and alerts teams when something deviates from that norm. These deviations can surface signs of silent tampering long before malware signatures do. In an era of novel and polymorphic threats, anomaly detection helps offer what static tools can’t: visibility into the unexpected.

Detección de amenazas: defensa específica contra actividades maliciosas conocidas

While anomalies reveal what’s unusual, threat detection exposes what is malicious. By scanning protected data directly for ransomware, malware signatures, encryption patterns, and custom indicators of compromise (IoCs), threat detection helps validate that the data you protect is not already compromised.

Por qué es importante un enfoque combinado

Ni la detección de anomalías ni la de amenazas por sí solas ofrecen una visión completa. Juntas, conforman una estrategia de defensa en profundidad: la detección de anomalías puede señalar señales sospechosas, mientras que la detección de amenazas puede profundizar más para verificar si hay intenciones maliciosas. Esta combinación ayuda a las organizaciones a distinguir las anomalías inofensivas de las verdaderas brechas de seguridad y a mantener datos fiables y validados para una recuperación rápida.

Meeting Today’s Challenges with Commvault® Cloud

Los atacantes se centran cada vez más en backup , y el malware oculto en backup puede aumentar el riesgo de reinfección durante la recuperación. Las organizaciones necesitan una validación basada en datos para garantizar una recuperación limpia y segura.Commvault Cloud addresses this by combining data protection workflows with anomaly detection, threat intelligence, AI-enabled analytics, and isolated clean instances. With anomaly and threat insights applied before, during, and after backup operations, Commvault can help empower organizations to recover faster, cleaner, and confidently.

Read the full white paper, “Can You Prove You’re Recoverable Right Now?”para obtener más información.

Preguntas frecuentes

Q: What is anomaly detection in data protection?

A: Anomaly detection identifies unusual behaviors – such as unexpected backup size changes or abnormal file activity – that may signal tampering, ransomware, or emerging threats within protected data.

Q: Why do CISOs need threat detection in their backup workflows?

A: Backup environments are now prime attacker targets. Threat detection helps prevent organizations from storing or restoring compromised data, which helps reduce reinfection risk and improve chances for clean recovery.

Q: How does Commvault help enable clean data recovery?

A: Commvault uses AI-assisted threat scanning, encryption detection, custom IoC matching, and cyber deception to help validate backup integrity and assemble the most recent uncompromised data for rapid recovery.

Q: Why combine anomaly and threat detection?

A: Anomalies identify the unknown; threat detection validates the known. Together, they provide comprehensive visibility into suspicious activity, helping enable faster investigation and more confident data recovery.

Lista de Paulinees directora de marketing de producto en Commvault

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Puntos Clave

  • Advanced AI models like Claude Mythos Preview could dramatically accelerate vulnerability discovery, reshaping the cybersecurity landscape.
  • Mythos highlights growing concerns about managing AI-enabled security risks at scale.
  • ResOps helps shift organizations from reactive defense to proactive resilience and recovery.
  • Cybersecurity tools focus heavily on prevention, while recovery capabilities remain underdeveloped.
  • In an AI-enabled world, the ability to recover quickly from disruption will define operational success.

Anthropic’s new Claude Mythos Preview modelis reportedly powerful enough to identify vulnerabilities in software systems in seconds. In early testing, the company claims the model was able to break out of its containment environment and email an engineer about the event.
Given these potential risks, Anthropic is limiting access to a small group of large organizations throughMythos. The goal: stay ahead of the security implications of a world where vulnerability discovery and exploitation may become trivial.
This shift strengthens the case for resilience operations (ResOps™). It could fundamentally change how organizations approach cybersecurity.
In a recent LinkedIn post, “The Beginning of the End of Cybersecurity,” Jen Easterly, CEO of RSAC and former director of CISA, argues that today’s cybersecurity industry is built to identify, defend against, and respond to software defects.
In effect, it compensates for gaps in software quality and secure development practices. If models like Claude Mythos Preview perform as described, their ability to surface vulnerabilities at scale could significantly disrupt today’s security tooling landscape.
A recent STRIVE episode – Evidence Over Hope: Will Your Recovery Plan Hold Up Under Pressure? – echoes this concern. Organizations have invested heavily in tools to prevent attacks, yet relatively little innovation exists “right of boom” – the capabilities required to recover the business when disruption inevitably occurs.

Why ResOps?

ResOps is an organizational discipline that embeds resilience into daily operations. It shifts organizations from passive, reactive backup strategies to an active, continuous model.
Traditional IT operations focus on efficiency. ResOps focuses on surviving failure. It brings together security, infrastructure, and operations teams around a common goal: Identify the organization’s minimum viable business – the critical systems, data, and processes required to operate – and enable those services to be restored quickly and cleanly after a disruption.
Most operational disciplines optimize for when systems work as expected. ResOps is designed for when they don’t. Its core question is simple: Can you recover each critical service right now – with confidence and evidence?

What Does the Future Hold?

If Easterly’s perspective proves accurate – that cybersecurity largely compensates for software defects – then technologies like Claude Mythos Preview represent more than incremental progress. They signal a structural shift in enterprise risk.
AI may help reduce the time between vulnerability discovery and remediation. It may even eliminate certain classes of software flaws. But it does not remove the risk of outages, misconfigurations, identity compromise, or cascading failures in complex systems. And it does not replace the operational discipline required to respond and recover.
Failure will still happen. That reality makes ResOps more important – not less. As prevention becomes more automated, resilience becomes the differentiator. Organizations will no longer be measured solely by their ability to block attacks. They will be measured by how effectively they recover – restoring critical services and trusted data under real-world conditions.
Cybersecurity aims to keep threats out. ResOps prepares you for when they get in. In an AI-accelerated world, the ability to survive and recover from failure may be the most important operational capability an organization can build.
Read more in our Readiness Report, Evidence Over Hope: The Executive Case for Resilience Operations, and learn more about theResOps disciplineon theReadiverse.

Preguntas frecuentes

Q: What is Mythos, and why does it matter?

A: Mythos is an initiative by Anthropic to limit and study access to powerful AI models capable of identifying software vulnerabilities. It matters because it signals a future where vulnerability discovery becomes fast and widespread, increasing both defensive and offensive risks.

Q: What is ResOps, and how is it different from traditional IT operations?

A: ResOps is a discipline focused on enabling organizations to survive and recover from disruptions. Unlike traditional IT operations that prioritize efficiency, ResOps prioritizes continuity and rapid recovery of critical services.

Q: How could AI impact the future of cybersecurity?

A: AI may significantly reduce the time needed to detect and fix vulnerabilities, potentially disrupting existing security tools. However, it does not eliminate risks like outages or misconfigurations, making recovery capabilities even more important.

Q: Why is recovery becoming more important than prevention?

A: Despite heavy investment in preventive tools, disruptions still occur. As threats evolve and automation increases, organizations will be judged more on how quickly and effectively they can restore operations after an incident.

Q: What does “right of boom” mean in this context?

A: “Right of boom” refers to the phase after an incident has occurred, focusing on response and recovery. It highlights the gap in innovation around restoring business operations compared to preventing attacks.

Q: How can organizations start adopting ResOps?

A: Organizations can begin by identifying their minimum viable business – critical systems and data – and building processes to restore them quickly. This involves aligning security, IT, and operations teams around resilience-focused goals.

Jason Meserve is Director of Social Marketing at Commvault.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Puntos Clave

  • Rising operational disruption makes scalable resilience essential, but organizations commonly fall into traps like seeking “silver bullet” technology or relying on “hero worship” of individual experts.
  • ResOps ofrece un marco escalable que integra a las personas, los procesos y la tecnología en ITOps, SecOps y DevOps.
  • El apoyo de la alta dirección, a nivel de director general, ayuda a fomentar la responsabilidad y a dar prioridad a la resiliencia como disciplina estratégica.

Cyberattacks, cloud complexity, and AI-enabled threats are creating constant operational challenges for enterprises. To help meet business requirements in this increasingly disruptive environment, organizations need to move beyond separate recovery tools, teams, and plans to resilience as an integrated operating model.

In a recent webinar, Phil Goodwin, research vice president for IDC’s worldwide infrastructure programs, joined me for a fireside chat to explore how organizations can move beyond fragmented approaches to build resilience that scales.

Por qué las organizaciones necesitan un nuevo marco de resiliencia

As organizations engage in daily firefighting while keeping up with new technologies and addressing new initiatives, they rarely have time to step back and reassess whether their approaches still meet requirements. But as isolated incidents become systemic disruption, this conversation has become essential.

In a simpler era, organizations focused primarily on backup and recovery. Large-scale disruptions such as Hurricane Sandy brought disaster recovery onto the agenda. Intensifying cyberthreats like ransomware added cyber resilience and business continuity to the list. Each evolution brought new capabilities, but many organizations simply bolted new approaches onto what they were already doing rather than addressing these expanding requirements holistically.

When separate teams manage different pieces with different tools and policies, gaps may emerge that can slow recovery. Despite years of investment in cybersecurity, organizations are still struggling with recovery.

More recently, AI has accelerated the urgency for a more integrated approach by reshaping both threats and defenses. Despite increasing AI investments, many businesses are delaying AI rollouts due to ongoing concerns about governance and security vulnerabilities.

On the other side of the cyber front, bad actors are using AI to create deepfakes, target users with more sophisticated and convincing phishing, and exploit vulnerabilities at scale.

Resilience operations – ResOps – treats resilience as a continuous operating discipline rather than a collection of separate tools and teams. By bringing together ITOps, SecOps, and DevOps under a unified framework, ResOps helps transform resilience to keep pace with systemic disruption.

Cómo evitar los errores más comunes en la planificación de la resiliencia

Even organizations that recognize the need for change often fall into traps. One is the “silver bullet” problem, which focuses on technology as the solution. Leaders want to believe that buying the right tools will solve everything, but technology alone can’t deliver positive business outcomes without proper integration and process.

“Hero worship” is another common pitfall – relying on talented staff members with expertise residing in their heads rather than in documented processes. Heroism can’t scale, and reliance on specific individuals creates vulnerability when people leave or responsibilities shift.

To move past these traps, you have to think differently about your operating model. Instead of focusing primarily on technology and people, consider the team you’ll need to build, including executive sponsorship, IT operations and security leadership, and senior leaders from the business side.

The team’s charter should focus on defining business outcomes first: What does resilience need to achieve for the organization? What KPIs, SLAs, and processes should be established to meet these requirements?

Desarrollar operaciones de resiliencia de arriba abajo

Como prioridad a nivel de la junta directiva, la resiliencia requiere el apoyo de los más altos cargos. Las operaciones de resiliencia (ResOps) cobran mayor impulso cuando el director general se implica, ayudando a establecer las prioridades en materia de recursos e impulsando la rendición de cuentas en toda la organización. Con el respaldo de la dirección, los altos directivos —como el director de sistemas de información (CIO), el director técnico (CTO), el director de seguridad de la información (CISO) y los directores generales— pueden encargar a su personal la puesta en marcha.

Este enfoque se puede adaptar a organizaciones de cualquier tamaño. Incluso las empresas pequeñas y medianas pueden formar equipos multifuncionales que incluyan a las partes interesadas del negocio, a los equipos de TI y al personal encargado de la seguridad de los datos y de la red. A medida que crecen, esta estructura puede adaptarse a sus necesidades, incorporando personal en disciplinas específicas relacionadas con la resiliencia, al tiempo que se mantiene un enfoque integrado en toda la cadena de operaciones de resiliencia. ResOps refleja la forma en que los equipos de operaciones de TI, SecOps y DevOps deben trabajar juntos dentro de las organizaciones. La recuperación de datos y la seguridad de los datos se han alineado tan estrechamente que, en IDC, los investigadores de estas disciplinas colaboran ahora con frecuencia en proyectos con clientes. Ahora hay que diseñar las aplicaciones teniendo en cuenta a los atacantes, incorporando arquitecturas de «confianza cero» y partiendo de la base de que algo va a salir mal. ResOps ofrece el marco necesario para esta convergencia, uniendo las herramientas de seguridad y de operaciones en un modelo unificado para hacer frente a amenazas e interrupciones de todo tipo.

ResOps como marco común para el sector

ResOps is an operating model, not a product, and can benefit companies regardless of the specific tools they use. As Phil observed during our chat, “It really requires that community involvement where people pitch in from different perspectives, different vendors, different organizations, and different teams, just like DevOps or SecOps.”

For organizations struggling with constant disruption and the growing complexity of AI-enabled threats and defenses, ResOps offers a path beyond fragmented resilience approaches. By bringing together people, processes, and technology in a unified operating model, ResOps turns fragmented recovery efforts into enterprise-wide readiness.

Watch my charla informal completa con Philpara ver cómo ResOps puede ayudarte a desarrollar una resiliencia empresarial que se adapte a tus necesidades.

Preguntas frecuentes

Q: What is resilience operations (ResOps)?

A: ResOps is an operating model that integrates IT operations, security operations, and DevOps into a continuous discipline. Rather than treating disaster recovery, cyber resilience, and business continuity as separate capabilities, ResOps brings people, processes, and technology together under a unified framework to help create scalable enterprise resilience.

Q: Why is executive sponsorship important for cyber resilience?

A: Executive sponsorship – ideally at the CEO level – helps drive accountability and priority for resilience initiatives across the organization. This top-down support is essential for organizations trying to move beyond fragmented approaches to integrated resilience operations.

Q: Can small and midsized organizations implement ResOps?

A: Yes. ResOps applies across organization sizes. The framework scales in complexity as organizations grow, making it accessible to mid-market firms while remaining effective for large enterprises.

Q: Why do IT and security teams need to work together for resilience?

A: When IT operations, security operations, and DevOps teams collaborate rather than work in silos, organizations can help build more resilient infrastructure to address evolving threats.

Q: How should organizations get started with resilience operations?

A: Start at the top by securing executive sponsorship at the CEO level. Next, form a cross-functional team including IT operations, SecOps, and business stakeholders, and have them define the business outcomes resilience needs to deliver for your business. Conduct a threat assessment to understand the risks you need to address. Only after these foundational steps should organizations focus on selecting technologies and developing detailed processes.

Chris Mierzwa is Senior Director, Portfolio Marketing, at Commvault.

More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements

Note: This blog was originally published in October 2025 when Data Rooms was introduced. It has been updated to reflect the next evolution, Data Activate.

Puntos Clave

  • Data Activate is part of Commvault’s next-generation AI capabilities – alongside AI ProtectyAI Studio – anunciado to help organizations activate AI safely, govern AI agents,ybuild agentic workflows from Commvault Cloud.
  • Data Activate está diseñado para que puedas transformar backup en activos fiables y preparados para la IA, a la vez que te ayuda a mantener el control y el cumplimiento normativo.
  • La oferta une la protección de datos y la activación de la IA sin crear nuevos riesgos de seguridad ni requerir otra platform.
  • Se integra con ecosistemas de IA existentes, como Microsoft Azure y Snowflake, utilizando estándares abiertos como Apache Parquet e Iceberg.
  • La gobernanza integrada permite la gestión, clasificación y el intercambio de datos protegidos dentro de una arquitectura de confianza cero.
  • Al activar los datos históricos, las organizaciones pueden ayudar a acelerar la innovación en IA, el análisis y los flujos de trabajo de cumplimiento normativo de forma segura.

AI innovation depends on data – but not just any data. It depends on trusted, governed,yaccessible data. Yet for most enterprises, the data that could fuel AI lives deep within backups, scattered across environments,ywrapped in compliance constraints. That’s where Commvault’s Data Activate offering, previously known as Data Rooms, comes in.

Acelerar la IA de forma segura

Data Activate es una de las tres funciones de IA que Commvaultanunciado as part of its next-generation AI platform – alongside AI ProtectyAI Studio. As organizations race to adopt AI, many are running into a fundamental challenge: their data is fragmentedydifficult to use. According to a recent survey, el 68 % de las empresas cite data silos as their top concern.

Commvault’s Data Activate offering helps transform backup data – one of the most completeytrusted datasets an organization owns – into AI-ready assets. Data Activate helps enterprises safely connect their data to AIyanalytics platforms, without creating new risks or complexity.

Unlike earlier bulk export approaches, Data Activate can regularly publish updated datasets, making it easier to keep AI pipelines in sync with the most current trusted data. Teams also can identifyyexclude sensitive data – such as personally identifiable information – before activating datasets for analytics or model development.

The Data Activate offering is not another AI platform. It’s the bridge between data protectionydata activation, designed to make your existing AI investments work fasterysafer. It does this by creating governed, policy-controlled “rooms” inside Commvault Cloud – spaces where data can be classified, curated,yshared with AIyanalytics tools without leaving the protection boundary.

Escuchar a los clientes: se acabó Platform

We heard customers loudyclear: You don’t need another AI platform. You need a protected, simple way to use the data you already maintain – across the AI toolsyecosystems you’ve already chosen.

That’s why Commvault built Data Activate to integrate with partners like Microsoft AzureySnowflake using open-standard formats such as Apache ParquetyIceberg. This helps you keep your data portable, policy-compliant,yready for activation – wherever your AI strategy takes you.

Convertir la protección de datos en activación de datos

With Data Activate, authorized users can discover, classify,yprepare data directly from backup repositories – across on-premisesycloud environments. Built-in governance helps maintain control, allowing only approved datasets to be shared, with automated classification, sensitivity tagging, redaction,yaudit trails applied every step of the way.

Data Activate acts as a governed, policy-controlled workspace inside Commvault Cloud – where data can be curatedymade available to AI or analytics tools without leaving the protection boundary. This governed design provides a protected bridge between backup datayactivation workflows, helping organizations unlock their information for innovation while being able to maintain complianceycontrol.

Data Activate puede ayudarte a:

  • Accelerate insights: Quickly findyexport historical data in AI-friendly formats to train models or power analytics.
  • Simplify operations: Eliminate brittle ETL pipelines with automated data discoveryycuration.
  • Maintain compliance: Keep governance intact with policy-based controlsytraceability from backup to activation.

La confianza como base para una IA responsable

En la prisa por adoptar la IA, la confianza suele convertirse en daño colateral. Según unestudio, roughly three-quarters of surveyed IT leaders said that using AI could make their organizations more vulnerable to cyberattacks. That’s why Commvault built Data Activate within Commvault Cloud’s zero-trust architecture, complete with encryption, RBAC,ycompliance support.

By combining data protection, governance,yactivation in one platform, Commvault enables enterprises to accelerate AI innovation without compromising data security, compliance, or control.

Acelera la innovación sin añadir riesgos

Commvault’s Data Activate offering helps organizations move faster by making data safely accessible to the tools that drive their business forward – from AI model training to analytics, eDiscovery,ycompliance support automation. Because when backup data becomes usable data, enterprises unlock years of historical intelligenceycontext that most AI models simply don’t have.

As Pranay Ahlawat, Commvault’s Chief TechnologyyAI Officer, said: “Organizations are beginning to realize that their historical data is more than just insurance – it’s a powerful, untapped strategic asset. With Commvault Data Activate, enterprises can confidently export their secondary datayharness it with the AI platform of their choice to unlock new opportunities for intelligence, innovation,ybusiness growth.”

Por qué es importante ahora

Commvault’s Data Activate offering redefines what’s possible for enterprises that want to innovate responsibly. They make it possible to move from protecting data to activating data – safely, flexibly,yat scale.

In short: Commvault isn’t building another AI platform. We’re building the foundation that lets every AI platform work better – because when data is protected, trusted,yready for activation, innovation happens faster.


FAQs

Q: What is Commvault’s Data Activate offering?
A: Commvault Data Activate is a capability within Commvault Cloud that helps enterprises safely discover, classify,yactivate backup data for AIyanalytics. It supports open formats like Apache IcebergyParquetyis built on a zero-trust, governed architecture for controlled, self-service data access.

Q: How does Data Activate differ from other AI data solutions?
A: Most AI data prep tools work only on live or production data, creating complianceycost challenges. Data Activate works from backup data – data that’s already protectedygoverned – bringing a unique balance of accessibility, compliance support,ytrust. It’s built into Commvault Cloud’s policy-controlled environment, so it’s part of a unified cyber resilience platform. Data Activate also regularly publishes updated datasets – rather than relying on one-time bulk exports – helping keep AI pipelines current without manual intervention.

Q: What benefits do organizations gain from using Data Activate?
A: Organizations can accelerate AIyanalytics insights, simplify data operations by reducing ETL complexity,ymaintain compliance through automated classification, tagging,yauditing processes.

Q: How does Data Activate support data securityycompliance?
A: Data Activate operates within Commvault Cloud’s zero-trust architecture, applying classification, redaction,yaudit-friendly controls automatically. It helps maintain data privacy, traceability,ycompliance throughout the data lifecycle, aligning with internalyregulatory governance standards.

Q: What types of AI or analytics platforms can connect with Data Activate?
A: Data Activate integrates with leading cloudyAI partners such as Microsoft AzureySnowflake, supporting open-standard data formats like Apache ParquetyIceberg for maximum flexibilityyportability.

Q: Why is this offering important for enterprises today?
A: As organizations accelerate AI adoption, Data Activate enables them to responsibly unlock the value of historical, protected data – fueling innovation while helping maintain trust, compliance,ycontrol.

Vir Choksi is Principal Product Marketing Manager at Commvault.


More related posts


Thumbnail_Blog-Dangerous-Silos-IDC-Resops-2026 (1)

The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan

Read more about The Importance of Recovery Point Objective (RPO) in Your Business Continuity Plan
Thumbnail_Blog-IDC-Resops-2026

Business Continuity Planning for the Cloud-Native Era

Read more about Business Continuity Planning for the Cloud-Native Era
Thumbnail_Blog-Bringing-Trust-to-CVE-2026

Demystifying SOC 2 Data Protection Requirements

Read more about Demystifying SOC 2 Data Protection Requirements